
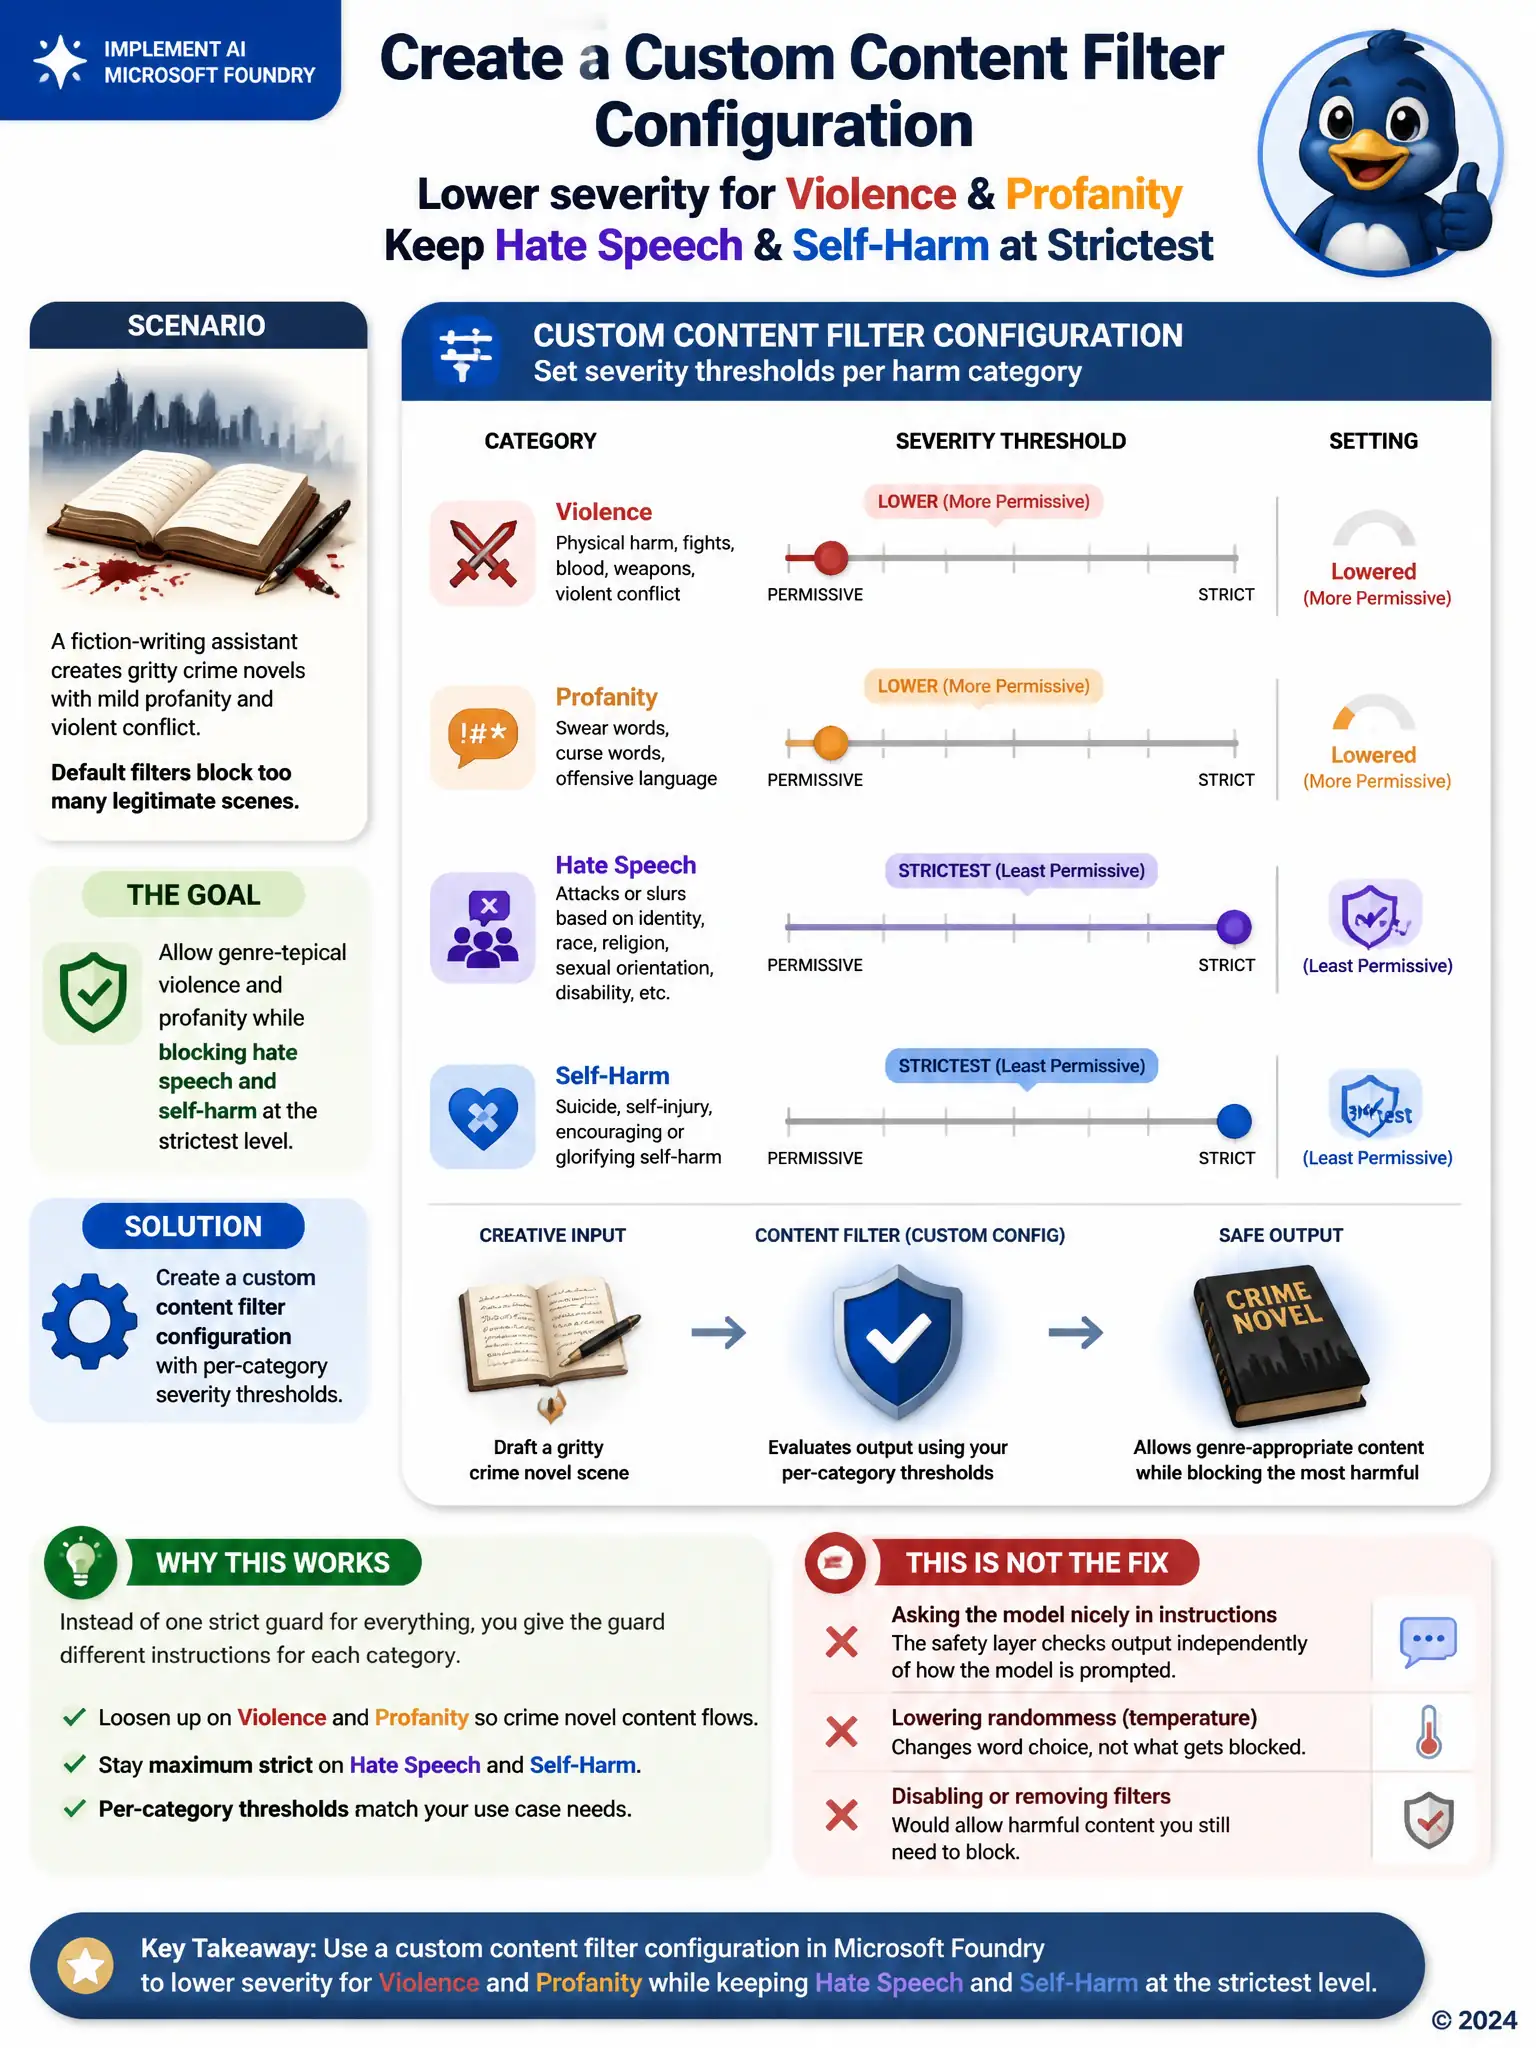
A fiction-writing assistant built on a Foundry-hosted model is meant to help authors draft gritty crime novels containing mild profanity and violent conflict typical of the genre. The default content filter blocks too many legitimate scenes, but the team still wants hate speech and self-harm content blocked at the strictest level. What should they configure?
Select an answer to reveal the explanation.
Short Explanation
Think of the default filter as one strict guard watching every category at the same tight setting, so it flags stuff that's completely normal for a crime novel, like a tense standoff or a swear word in dialogue. You don't fire the guard, since you still absolutely want hate speech and self-harm stopped cold; you give the guard different instructions for different categories, loosen up on violence and rough language, but stay just as strict on the categories that matter most. Asking the model nicely through instructions doesn't change what the safety layer allows through, because that layer checks the output independently of how the model was prompted, and dialing down randomness just changes word choice, not what gets blocked.
Full Explanation
The custom content filter configuration that lowers the severity threshold for violence and profanity while keeping hate speech and self-harm at their strictest settings is correct because Azure AI Foundry allows each harm category, such as violence, hate speech, self-harm, and sexual content, to have its own severity threshold. This lets the team loosen the threshold specifically for violence and profanity to fit the crime-fiction genre while leaving hate speech and self-harm at the strictest blocking level, exactly matching the stated requirement. Turning off content filtering entirely for this deployment so drafts are never blocked is incorrect because disabling filtering entirely removes protection against hate speech and self-harm too, which the team explicitly wants to keep blocked. Adding a system message asking the model to write violent scenes tastefully is incorrect because a system message is a prompt-level instruction to the model, not a control on the content filter itself; the filter operates independently of the model's own text and can still flag or block output regardless of how politely the system message asks the model to behave. Reducing the model's temperature so violent scenes are described more conservatively is incorrect because temperature controls how random or varied the model's word choices are, not what the safety filter allows through; a lower temperature might produce more predictable prose but does nothing to change which categories get blocked. Per-category severity configuration is the mechanism built for this exact tradeoff.