
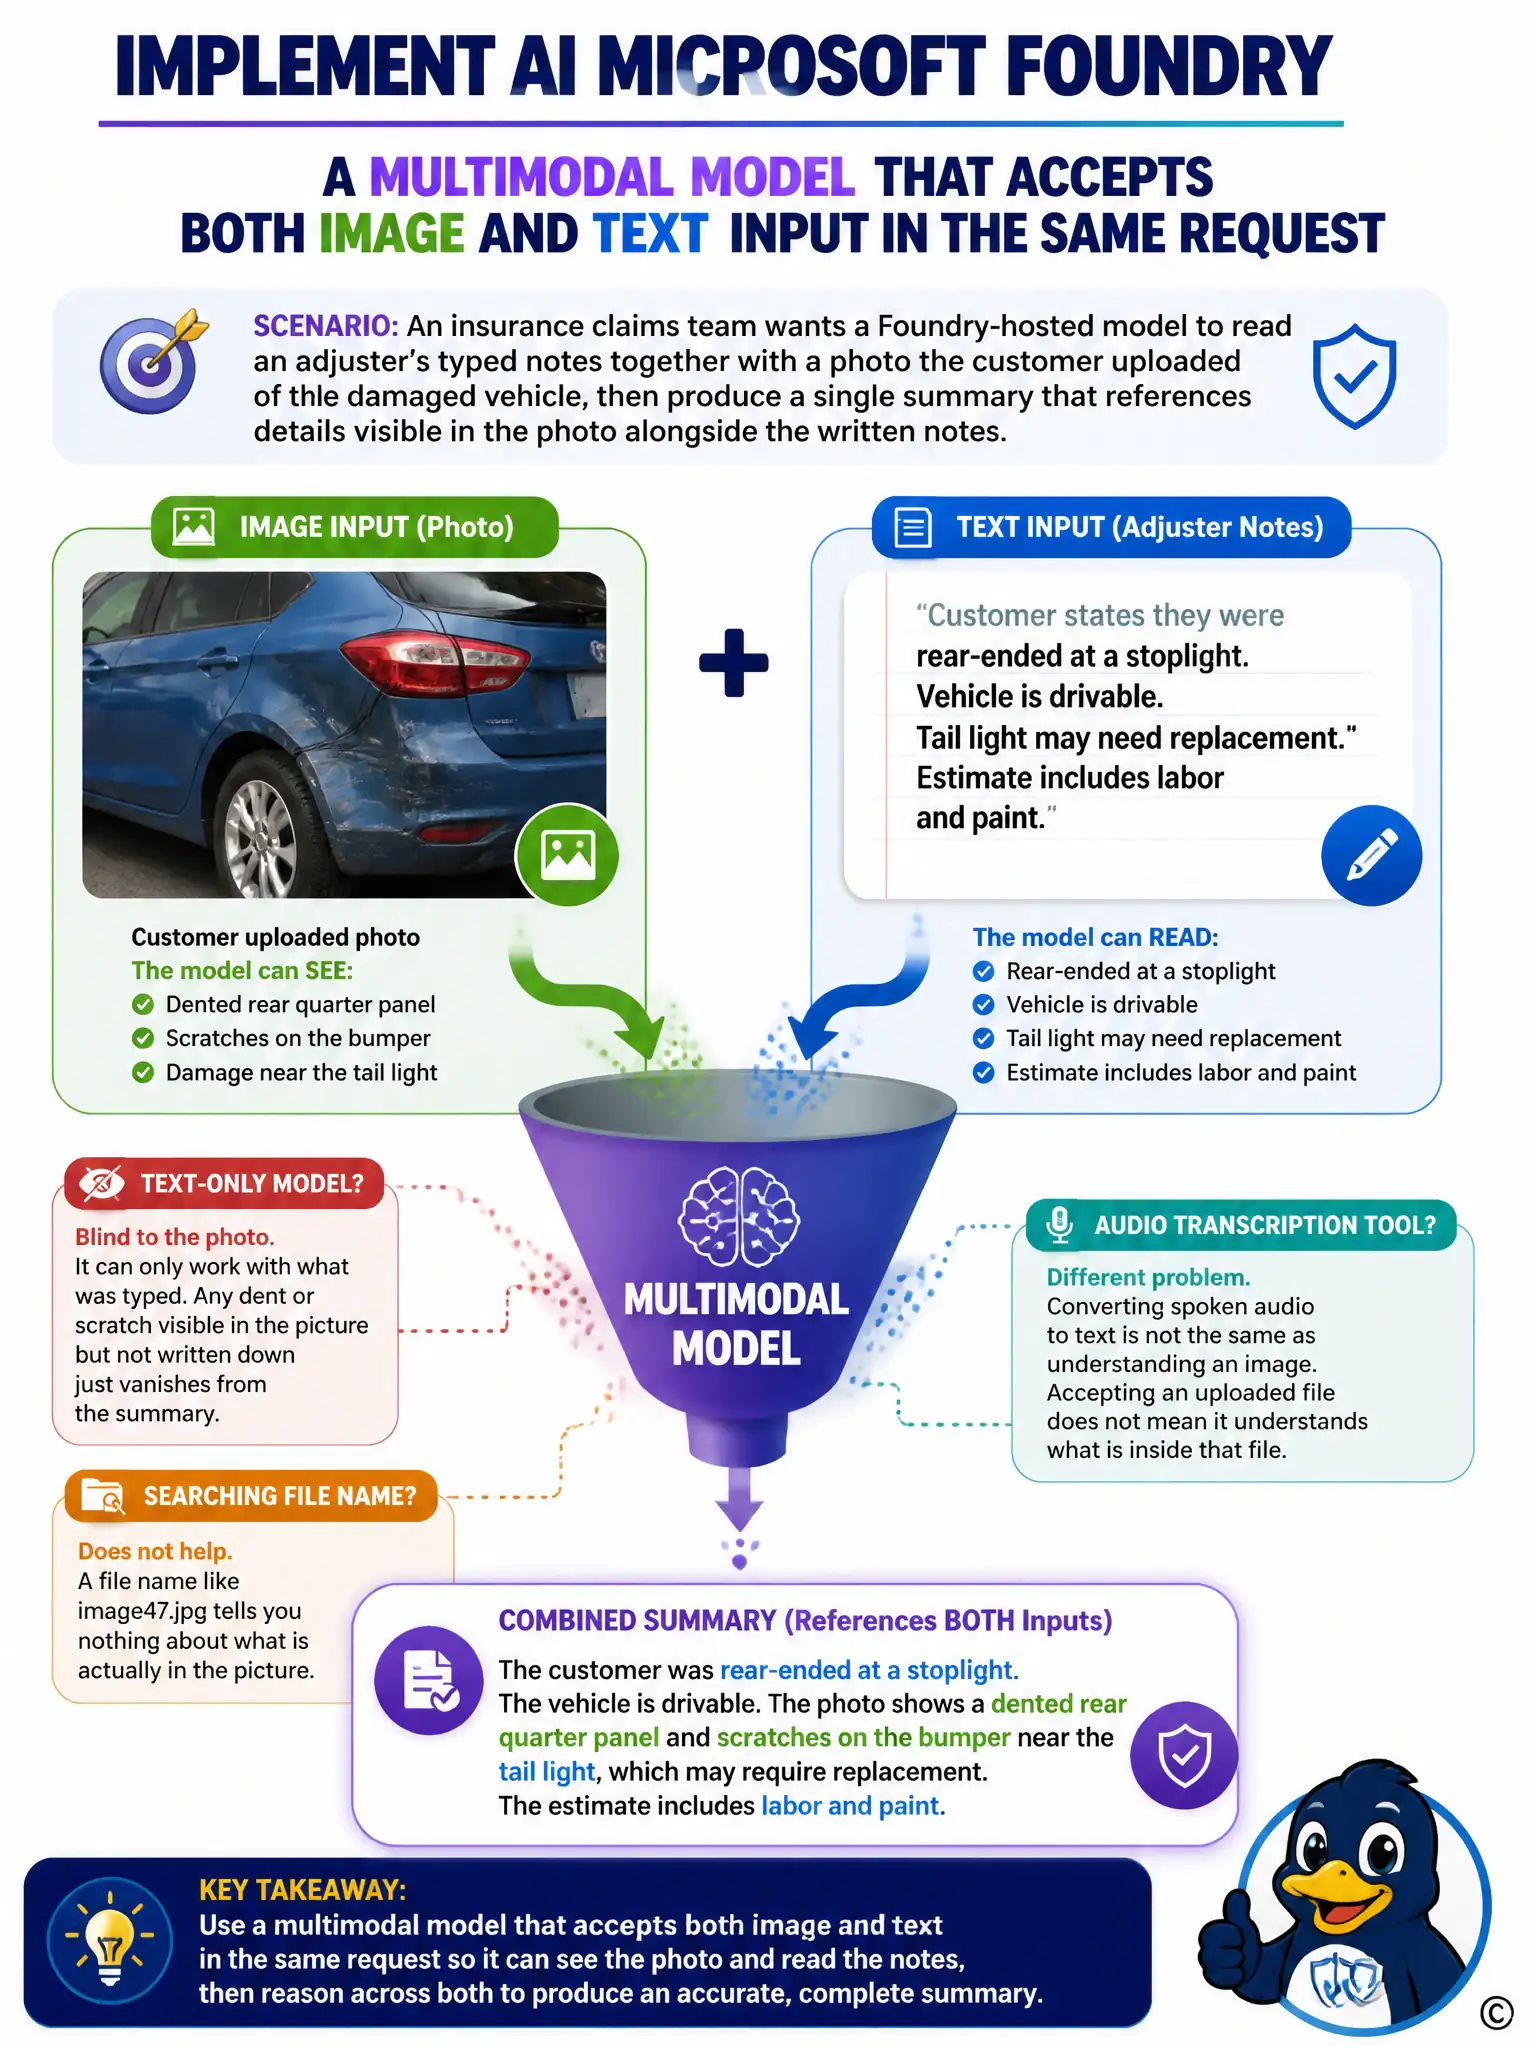
An insurance claims team wants a Foundry-hosted model to read an adjuster's typed notes together with a photo the customer uploaded of the damaged vehicle, then produce a single summary that references details visible in the photo alongside the written notes. Which type of model should they deploy for this task?
Select an answer to reveal the explanation.
Short Explanation
You need a multimodal model that accepts both image and text input in the same request, because the summary has to connect what's visible in the photo with the adjuster's notes. Text-only models can't see the photo, and speech-to-text models don't understand image content.
Full Explanation
Producing one summary that references details visible in the photo alongside the adjuster's written notes requires a model that can accept and reason over both an image and text together in a single request, which is what a multimodal model that accepts both image and text input in the same request is built to do. The text-only model that assumes the written notes already describe the damage in enough detail is incorrect because a text-only model has no way to interpret the uploaded photo at all, so any damage visible only in the image, and not already transcribed into the notes, would be missed entirely, defeating the purpose of including the photo. The text-only model paired with a separate keyword search over the photo's file name is incorrect because a file name is just a short label and carries essentially none of the visual information in the actual photo, so keyword searching it cannot substitute for the model actually analyzing the image content. The speech-to-text model that claims it can process any file the customer uploads is incorrect because a speech-to-text model is built to transcribe spoken audio into text, not to interpret a photograph; being able to accept a file upload does not mean it can extract meaning from an image, and it would still leave the visual damage details unaddressed.