
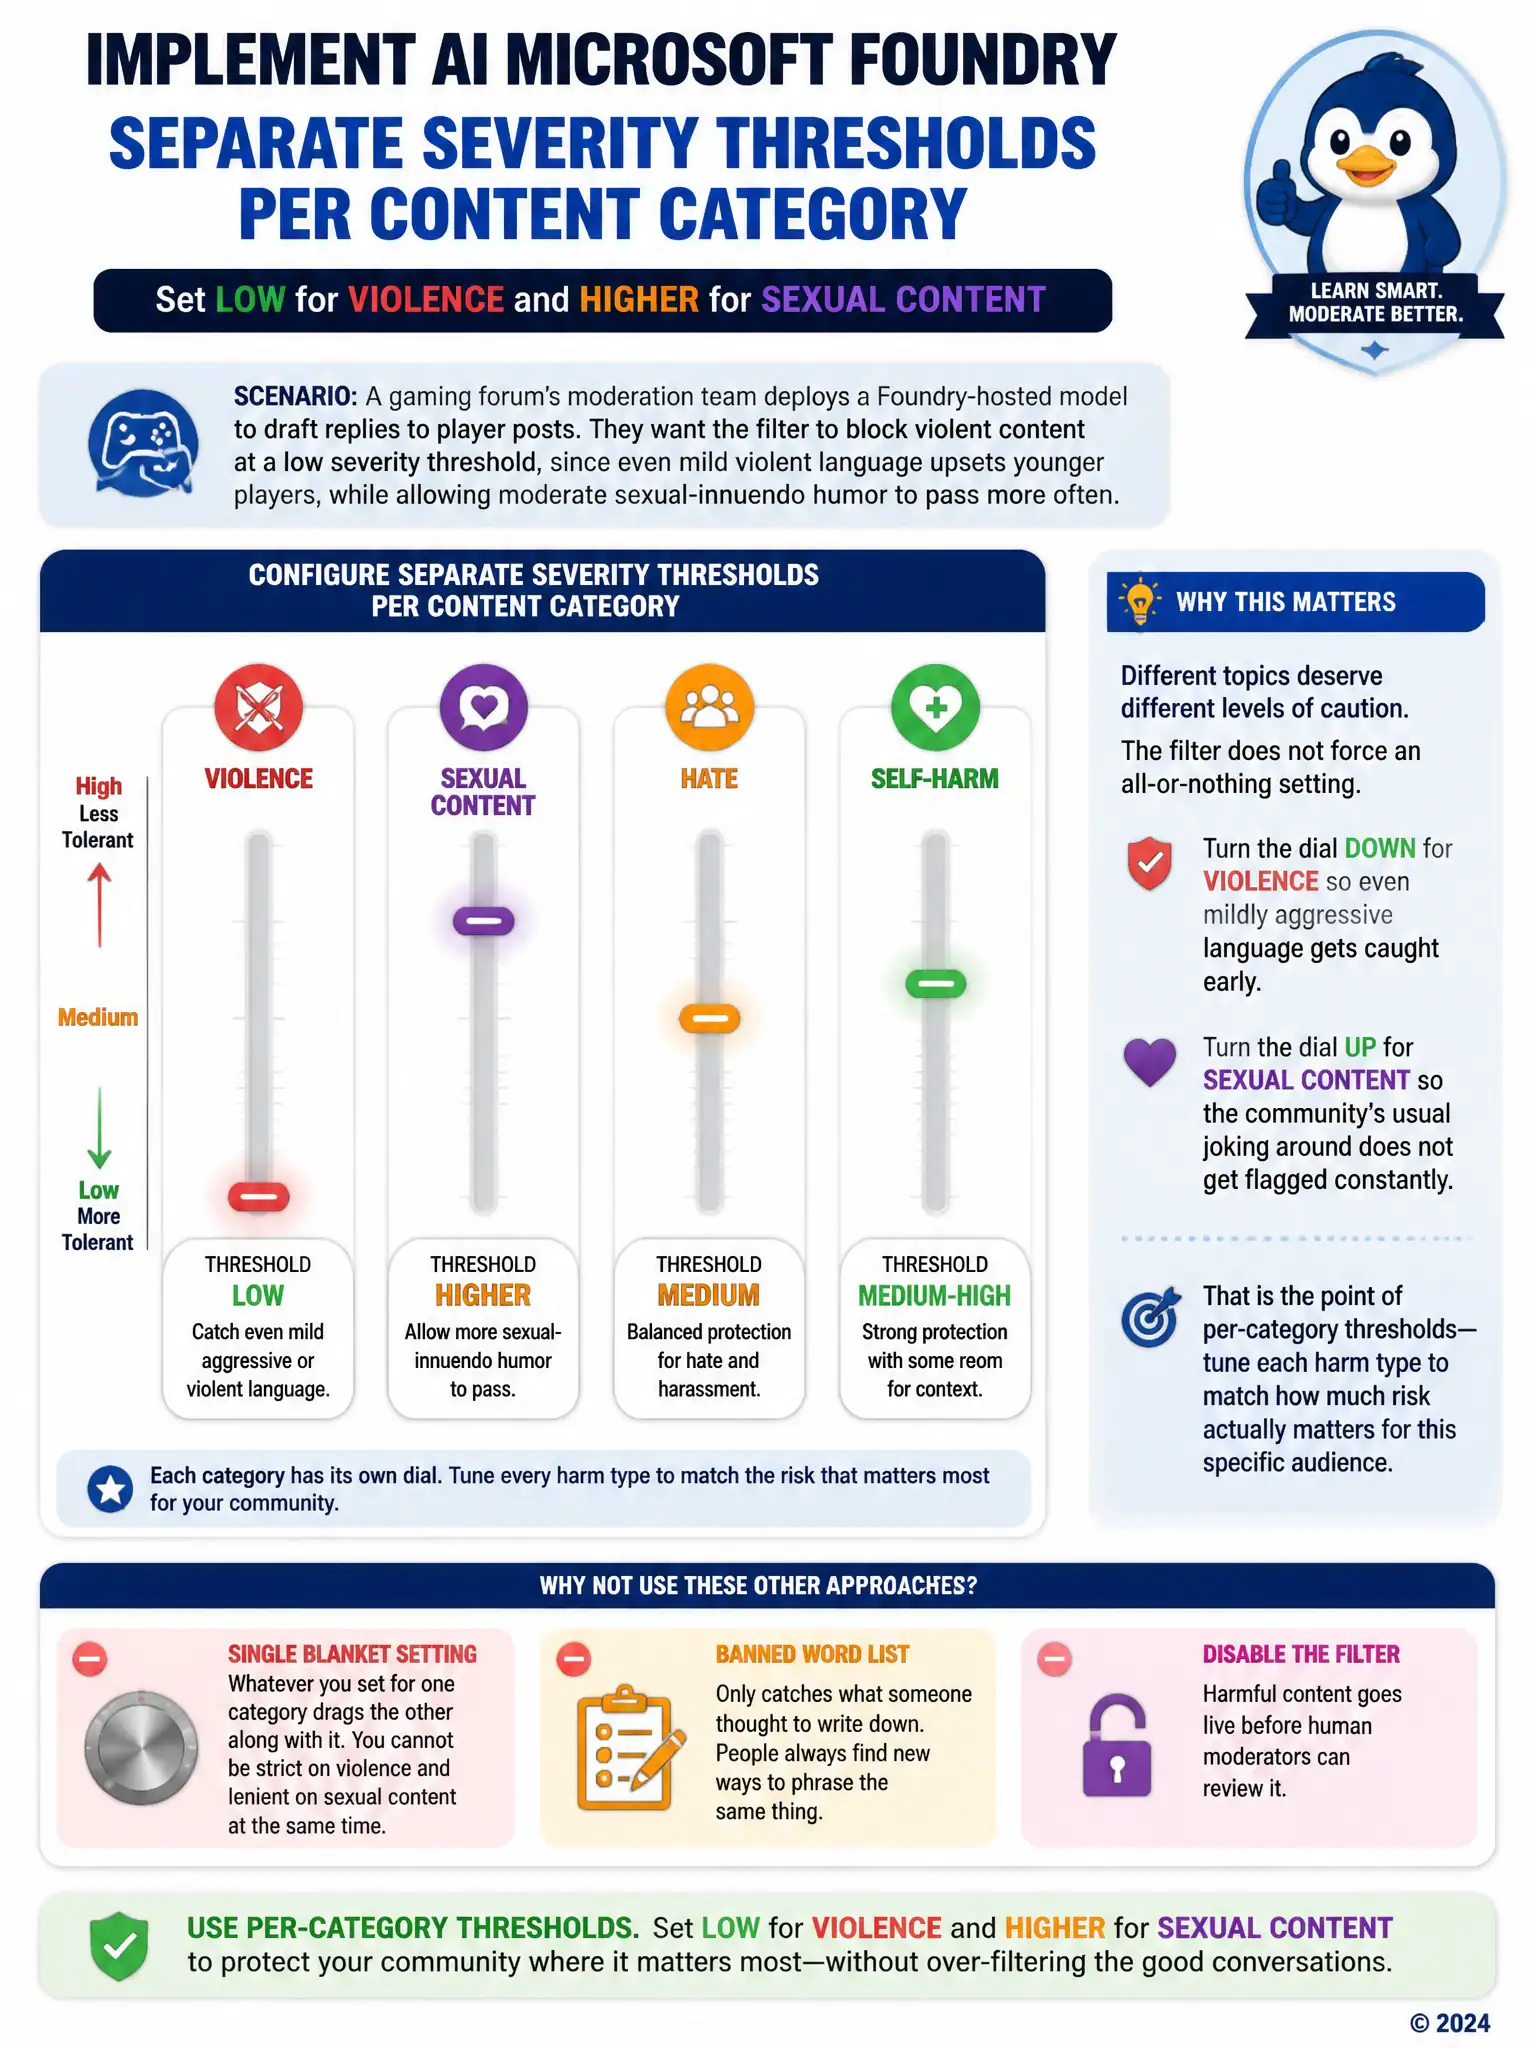
A gaming forum's moderation team deploys a Foundry-hosted model to draft replies to player posts. They want the content safety filter to block violent content at a low severity threshold, since even mild violent language upsets younger players, while allowing moderate sexual-innuendo humor common in the community to pass more often. What should they configure?
Select an answer to reveal the explanation.
Short Explanation
You need separate severity thresholds per content category, with violence set low and sexual content set higher. That lets the filter catch mild violent language early while letting the community's usual innuendo humor pass more often. Blanket settings, keyword-only filtering, or human-only review can't meet that split requirement.
Full Explanation
The configuration that fits this scenario is separate severity thresholds per content category, set low for violence and higher for sexual content. Azure AI Foundry's content safety filtering lets teams set independent severity thresholds for different harm categories, so the forum can configure strict, low thresholds that block violent content early while allowing comparatively higher thresholds for sexual content so mild innuendo humor typical of the community is not over-blocked. This matches the two different tolerance levels the team wants. The single overall safety threshold applied identically across all harm categories is incorrect because one uniform threshold across categories cannot express the team's actual requirement; tightening violence sensitivity would also tighten sexual-content sensitivity, and loosening one to fit community humor would loosen the other, which is not what they want for violent content. The content filter that only scans replies for manually typed banned keywords is incorrect because it only catches exact wording the team thought to include and misses paraphrases or new phrasing, unlike the built-in categorized filter, which uses trained classifiers. Disabling the content filter and relying on human moderators to review every post after publication is incorrect because it removes automated protection entirely and shifts the full moderation burden to humans reviewing content only after it has already been published, which does not prevent the harmful content from appearing in the first place.