
A content-moderation platform hosts a Foundry-deployed model for a public forum. The team wants to strictly block violent language in what users type into the box, since that could indicate a real threat, but they do not want the model prevented from generating its own responses that reference violence when discussing safety resources, news summaries, or crisis-support information. What configuration addresses this?
Select an answer to reveal the explanation.
Short Explanation
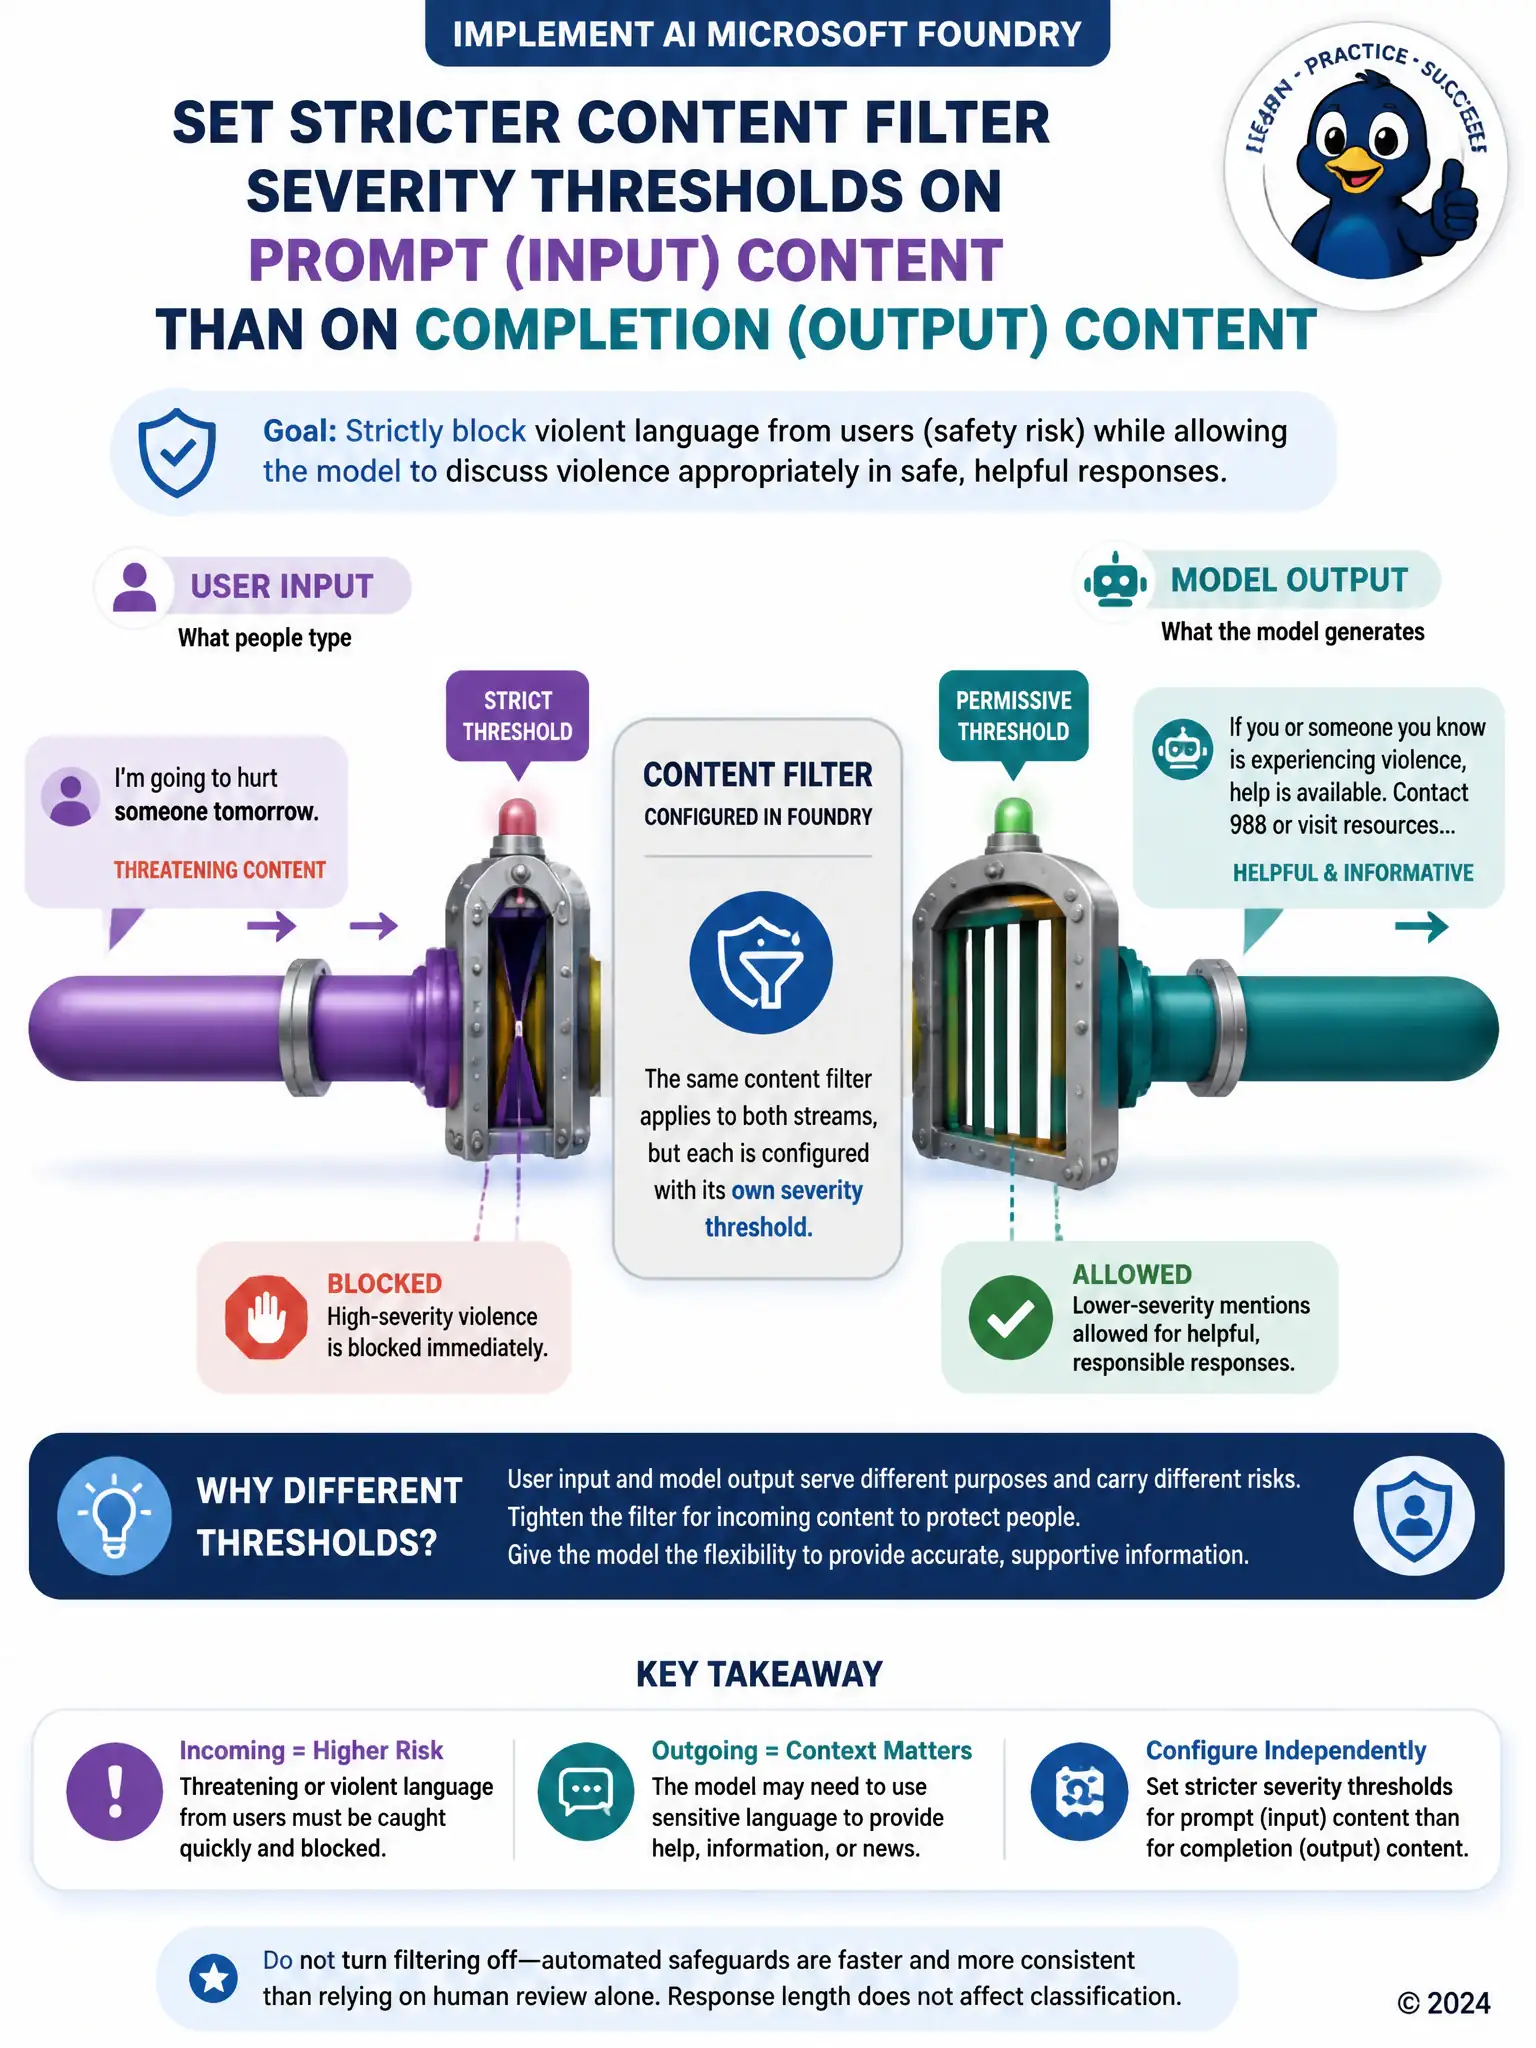
You need separate thresholds for what users type and what the model generates. Set a stricter filter on prompt content so threats get caught, while letting completion content reference violence when explaining safety resources, news, or crisis support. Turning filtering off or making responses longer doesn't solve the problem.
Full Explanation
Foundry content filters can be configured with independent severity thresholds for prompt content and completion content, so the team can set a strict, low-tolerance threshold on what users submit while allowing a more permissive threshold on the model's own generated responses that legitimately reference violence in a safety or informational context. The approach of applying the same content filter severity threshold uniformly to both prompts and completions is incorrect because applying one uniform threshold to both directions would either block the legitimate safety-resource responses along with user threats, or loosen screening on user input to the point it misses real threats, failing one side of the stated requirement. Disabling content filtering entirely and relying on manual moderator review of every post is incorrect because disabling filtering removes the automated safeguard against threatening user content entirely and shifts all risk onto manual review, which does not scale to a public forum's volume and leaves harmful posts live until a human catches them. Increasing the model's maximum output token limit so violent terms are diluted across longer responses is incorrect because token limits control response length, not content classification, and padding a response with more text does nothing to change whether violent content is detected or how it is judged.