
An insurance company is building a claims-intake tool where an adjuster uploads a photo of vehicle damage along with a short written description, and the Foundry-hosted model must assess both together in a single response to estimate damage severity. Which type of model should they select from the catalog for this task?
Select an answer to reveal the explanation.
Short Explanation
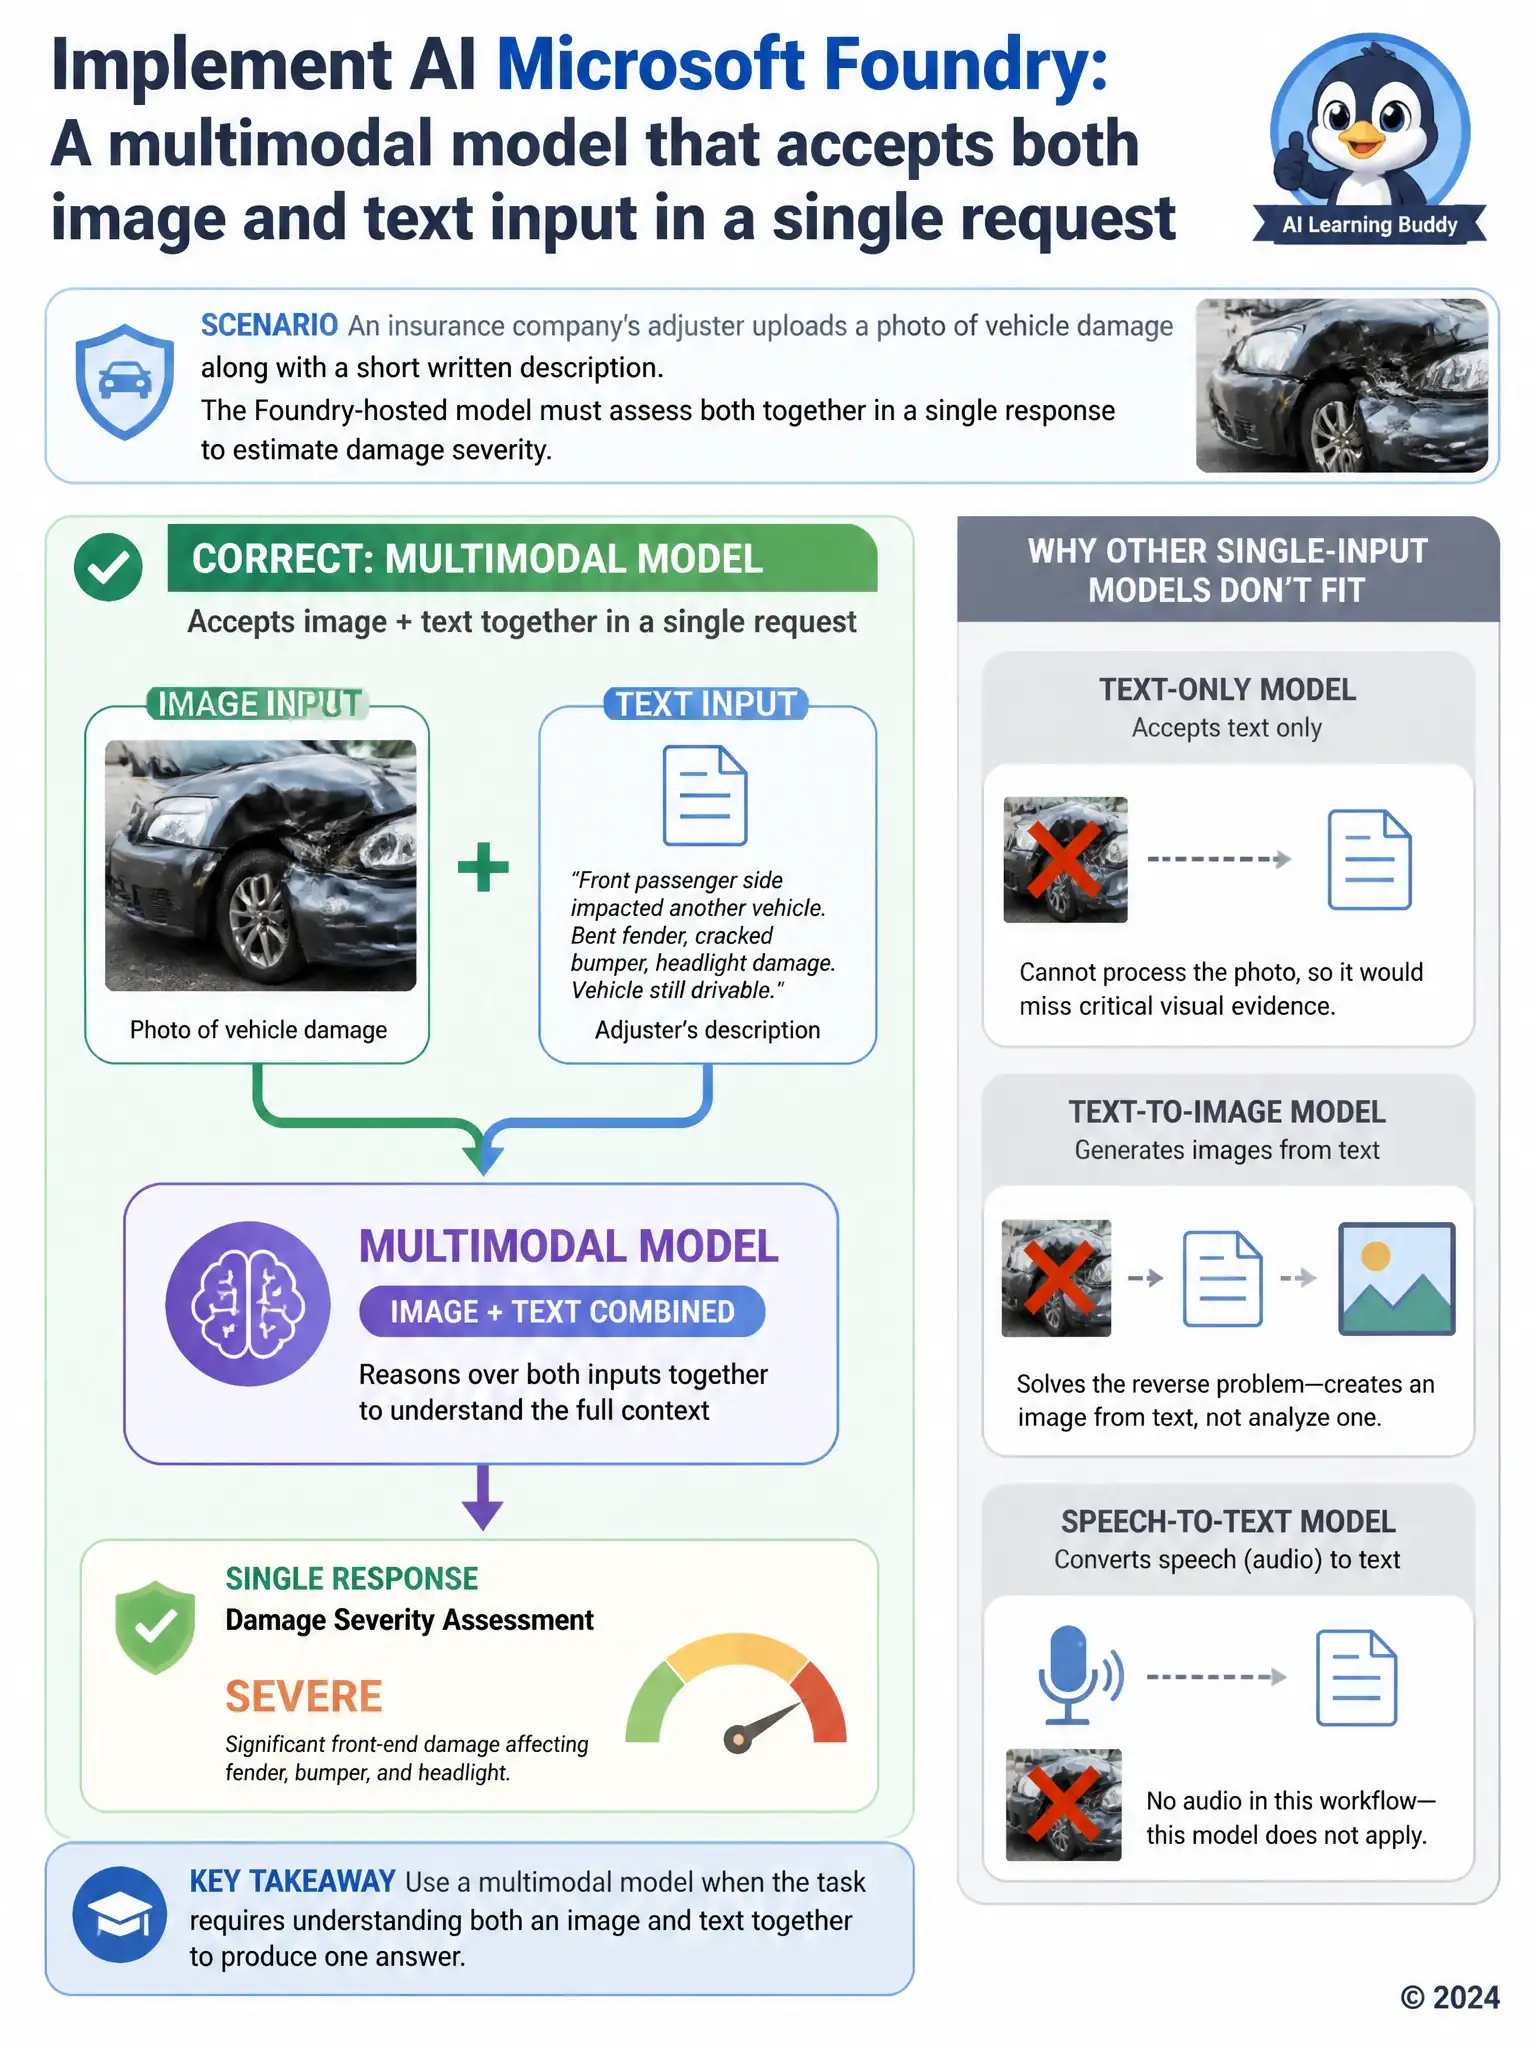
You're feeding the tool both a photo and a description, so you need a model that can take image and text together in one request. Text-only models can't see the photo, image-generation models make new pictures instead of judging one, and speech-to-text models have no audio to work with.
Full Explanation
The correct choice is the multimodal model that accepts both image and text input in a single request. It can process the uploaded photo and the written description together within one request, which is exactly what the claims-intake tool needs to produce a combined severity assessment that accounts for both inputs. The text-only large language model tuned for long-context reasoning is incorrect because a text-only model, no matter how good it is at reasoning over long passages, has no way to interpret the contents of an uploaded photo at all. The text-to-image generation model is incorrect because a text-to-image model generates new images from a prompt; it does not analyze an existing photo, which is the opposite capability from what this task requires. The speech-to-text transcription model is incorrect because a speech-to-text model transcribes spoken audio into text, which is unrelated to either the photo or the written description in this scenario, since there is no audio input involved.