
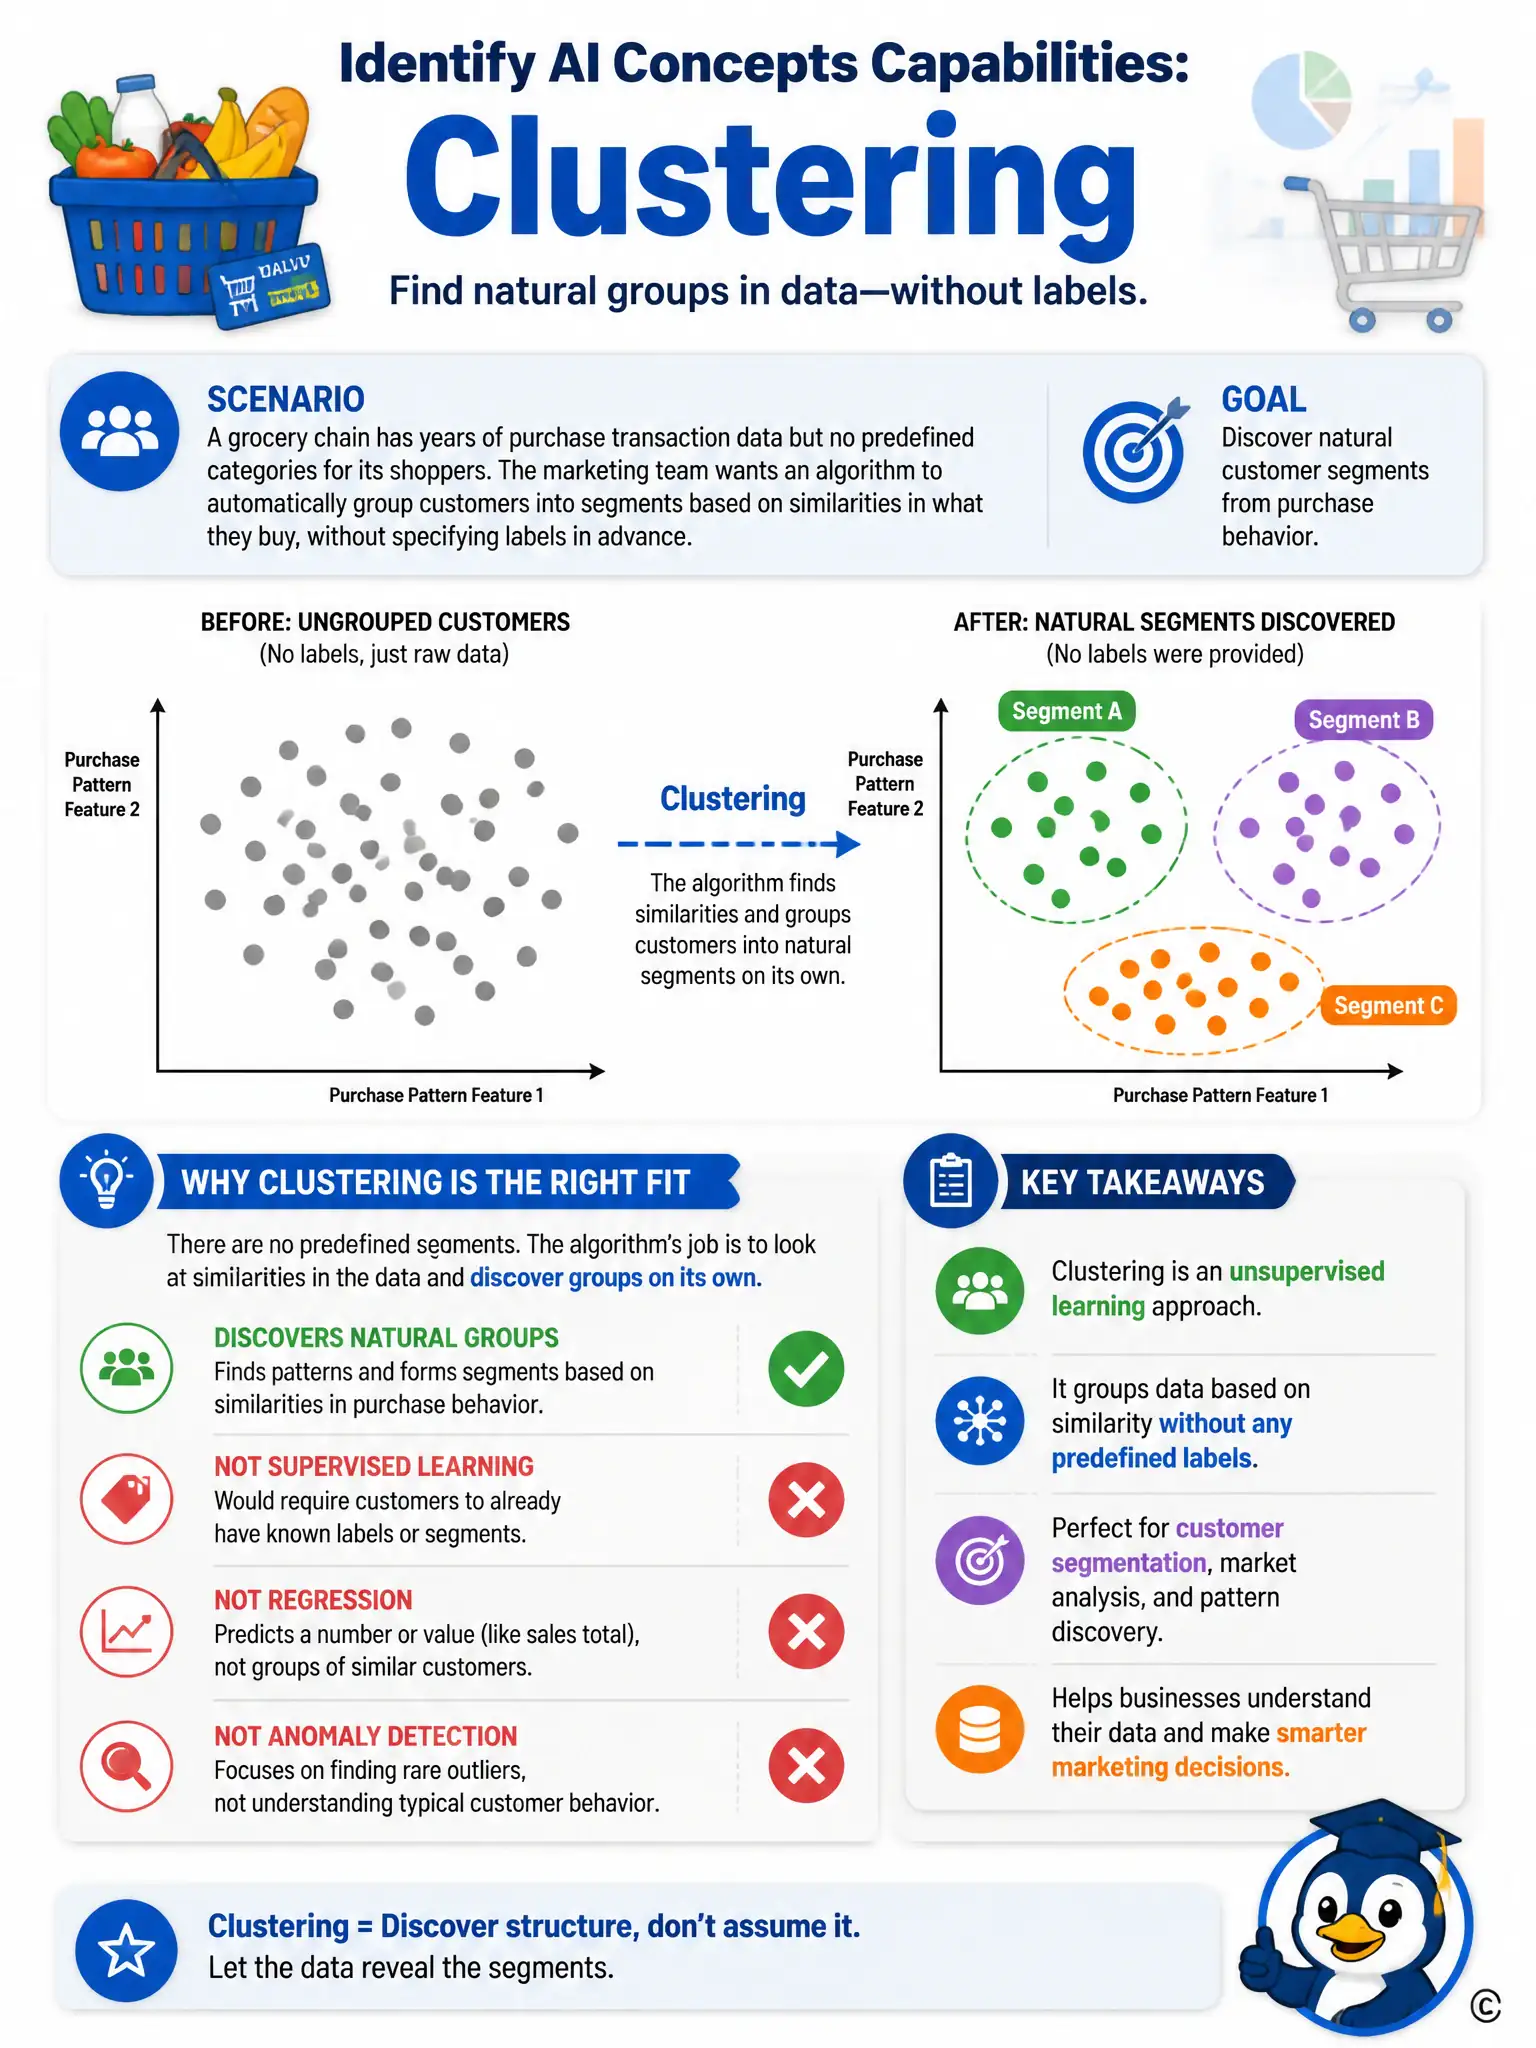
A grocery chain has years of purchase transaction data but no predefined categories for its shoppers. The marketing team wants an algorithm to automatically group customers into segments based on similarities in what they buy, without specifying labels in advance. Which machine learning approach fits this need?
Select an answer to reveal the explanation.
Short Explanation
You've got purchase history but no predefined shopper categories, so you need clustering to find natural groups from similarities on its own. It's not a labeled-category method, a number-predicting method, or an outlier-hunting method.
Full Explanation
Clustering is correct because the marketing team has transaction data but no predefined customer categories, and wants an algorithm to discover natural groupings of shoppers based on purchasing similarity on its own; clustering organizes data points into groups without requiring labeled examples in advance. The classification approach is incorrect because it requires a training dataset where each customer is already labeled with a known category, which the team does not have here since no categories exist yet. The regression approach is incorrect because it predicts a continuous numeric value, such as forecasting a sales figure, rather than organizing customers into groups. The anomaly detection approach is incorrect because it is built to flag unusual outliers that deviate from normal patterns, not to sort the broader customer base into meaningful, typical segments for marketing purposes.