
A support team serving customers across a dozen languages wants to add a model to their Foundry deployment. Before choosing, they need evidence that a candidate model performs well specifically on non-English support conversations, not just on the English benchmarks quoted in marketing material. Where in Foundry should they look to compare candidate models on this basis?
Select an answer to reveal the explanation.
Short Explanation
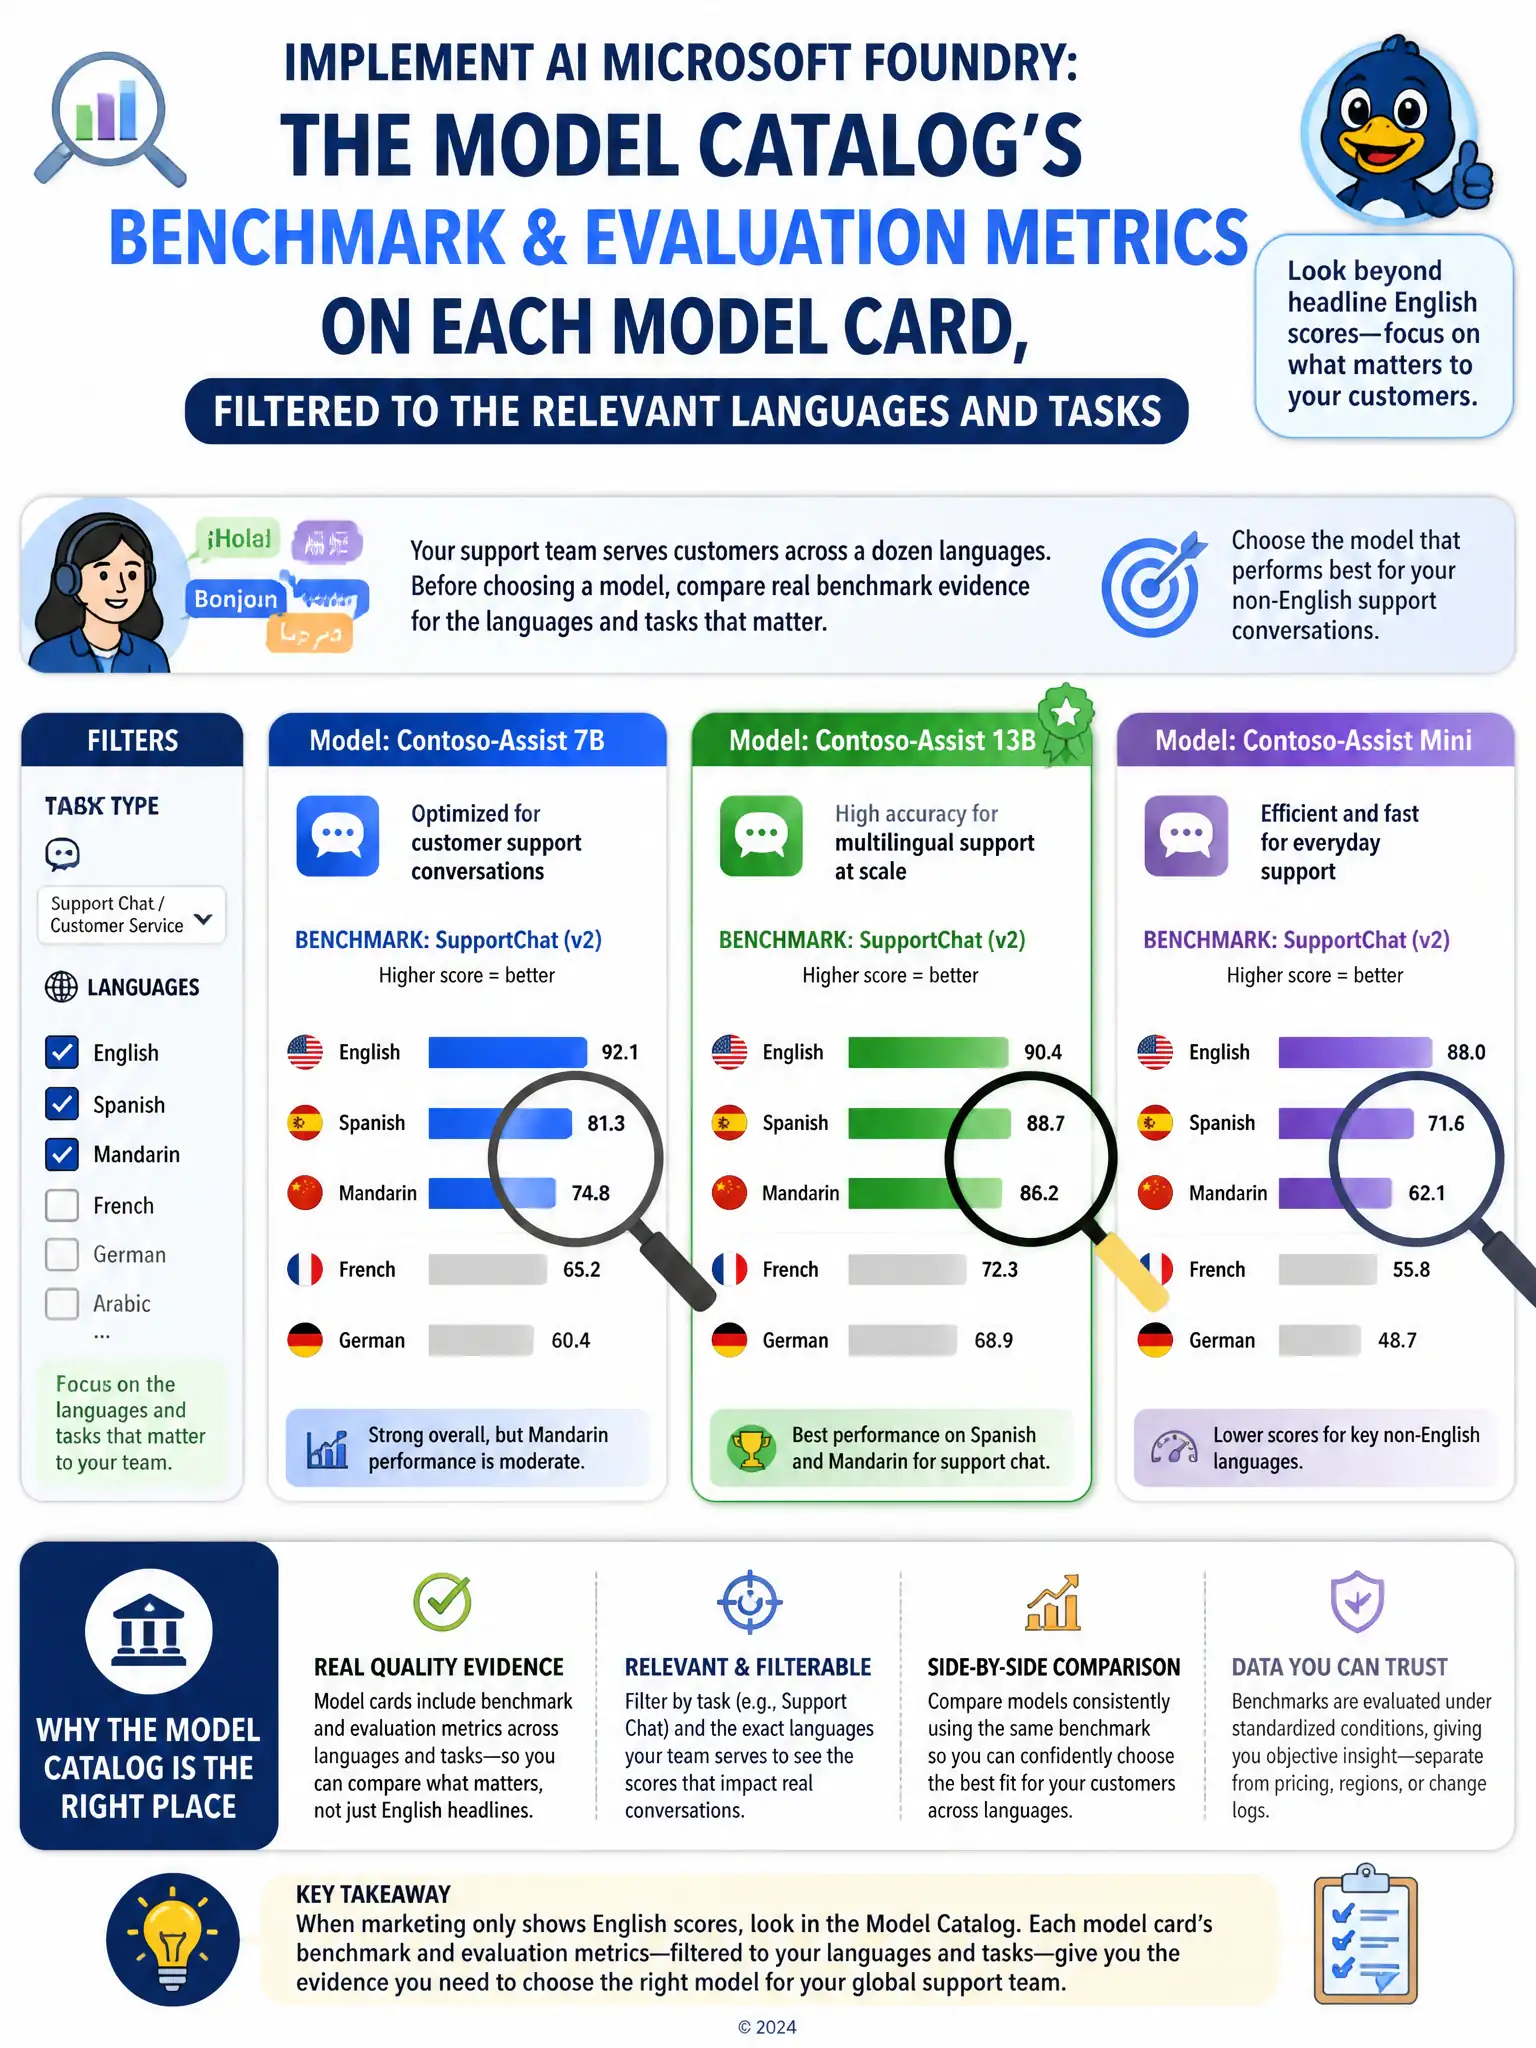
If marketing only brags about English scores, that doesn't tell you how a model handles another language. The model catalog's benchmark and evaluation metrics on each model card, filtered to the relevant languages and tasks, gives you evidence you can compare. Pricing, region availability, and activity logs don't measure multilingual conversation quality.
Full Explanation
The correct answer is the model catalog's benchmark and evaluation metrics on each model card, filtered to the relevant languages and tasks. Each model in the Foundry model catalog has a model card that includes published benchmark and evaluation results, and these can be filtered or reviewed by task and language, giving the team concrete, comparable evidence of how a candidate performs on non-English support-style conversations rather than relying on a vendor's general marketing claims about English performance. The Azure subscription's cost management page, which lists per-model pricing tiers, is incorrect because it shows pricing information, which has no bearing on how well a model handles multilingual conversation quality. The regional availability map showing which Azure regions currently host each model is incorrect because it only indicates where a model can be deployed for latency or compliance reasons, and it says nothing about the model's language capability or accuracy. The resource group's activity log, which records recent deployment and configuration events, is incorrect because it is an operational audit trail of what configuration changes were made and when, not a source of model quality or performance data. Reviewing the catalog's benchmark data filtered to the languages and tasks that matter is the direct way to make an evidence-based model choice instead of assuming general-purpose marketing claims will hold across languages.