
A publisher is deploying a Foundry-hosted generative model to help authors draft fictional dialogue for a mature drama series. The default content filter configuration blocks any violent language, even when it is clearly part of a fictional narrative rather than real instructions to cause harm. The team still wants the deployment to block outputs describing real-world weapon creation or hate speech. What should they do?
Select an answer to reveal the explanation.
Short Explanation
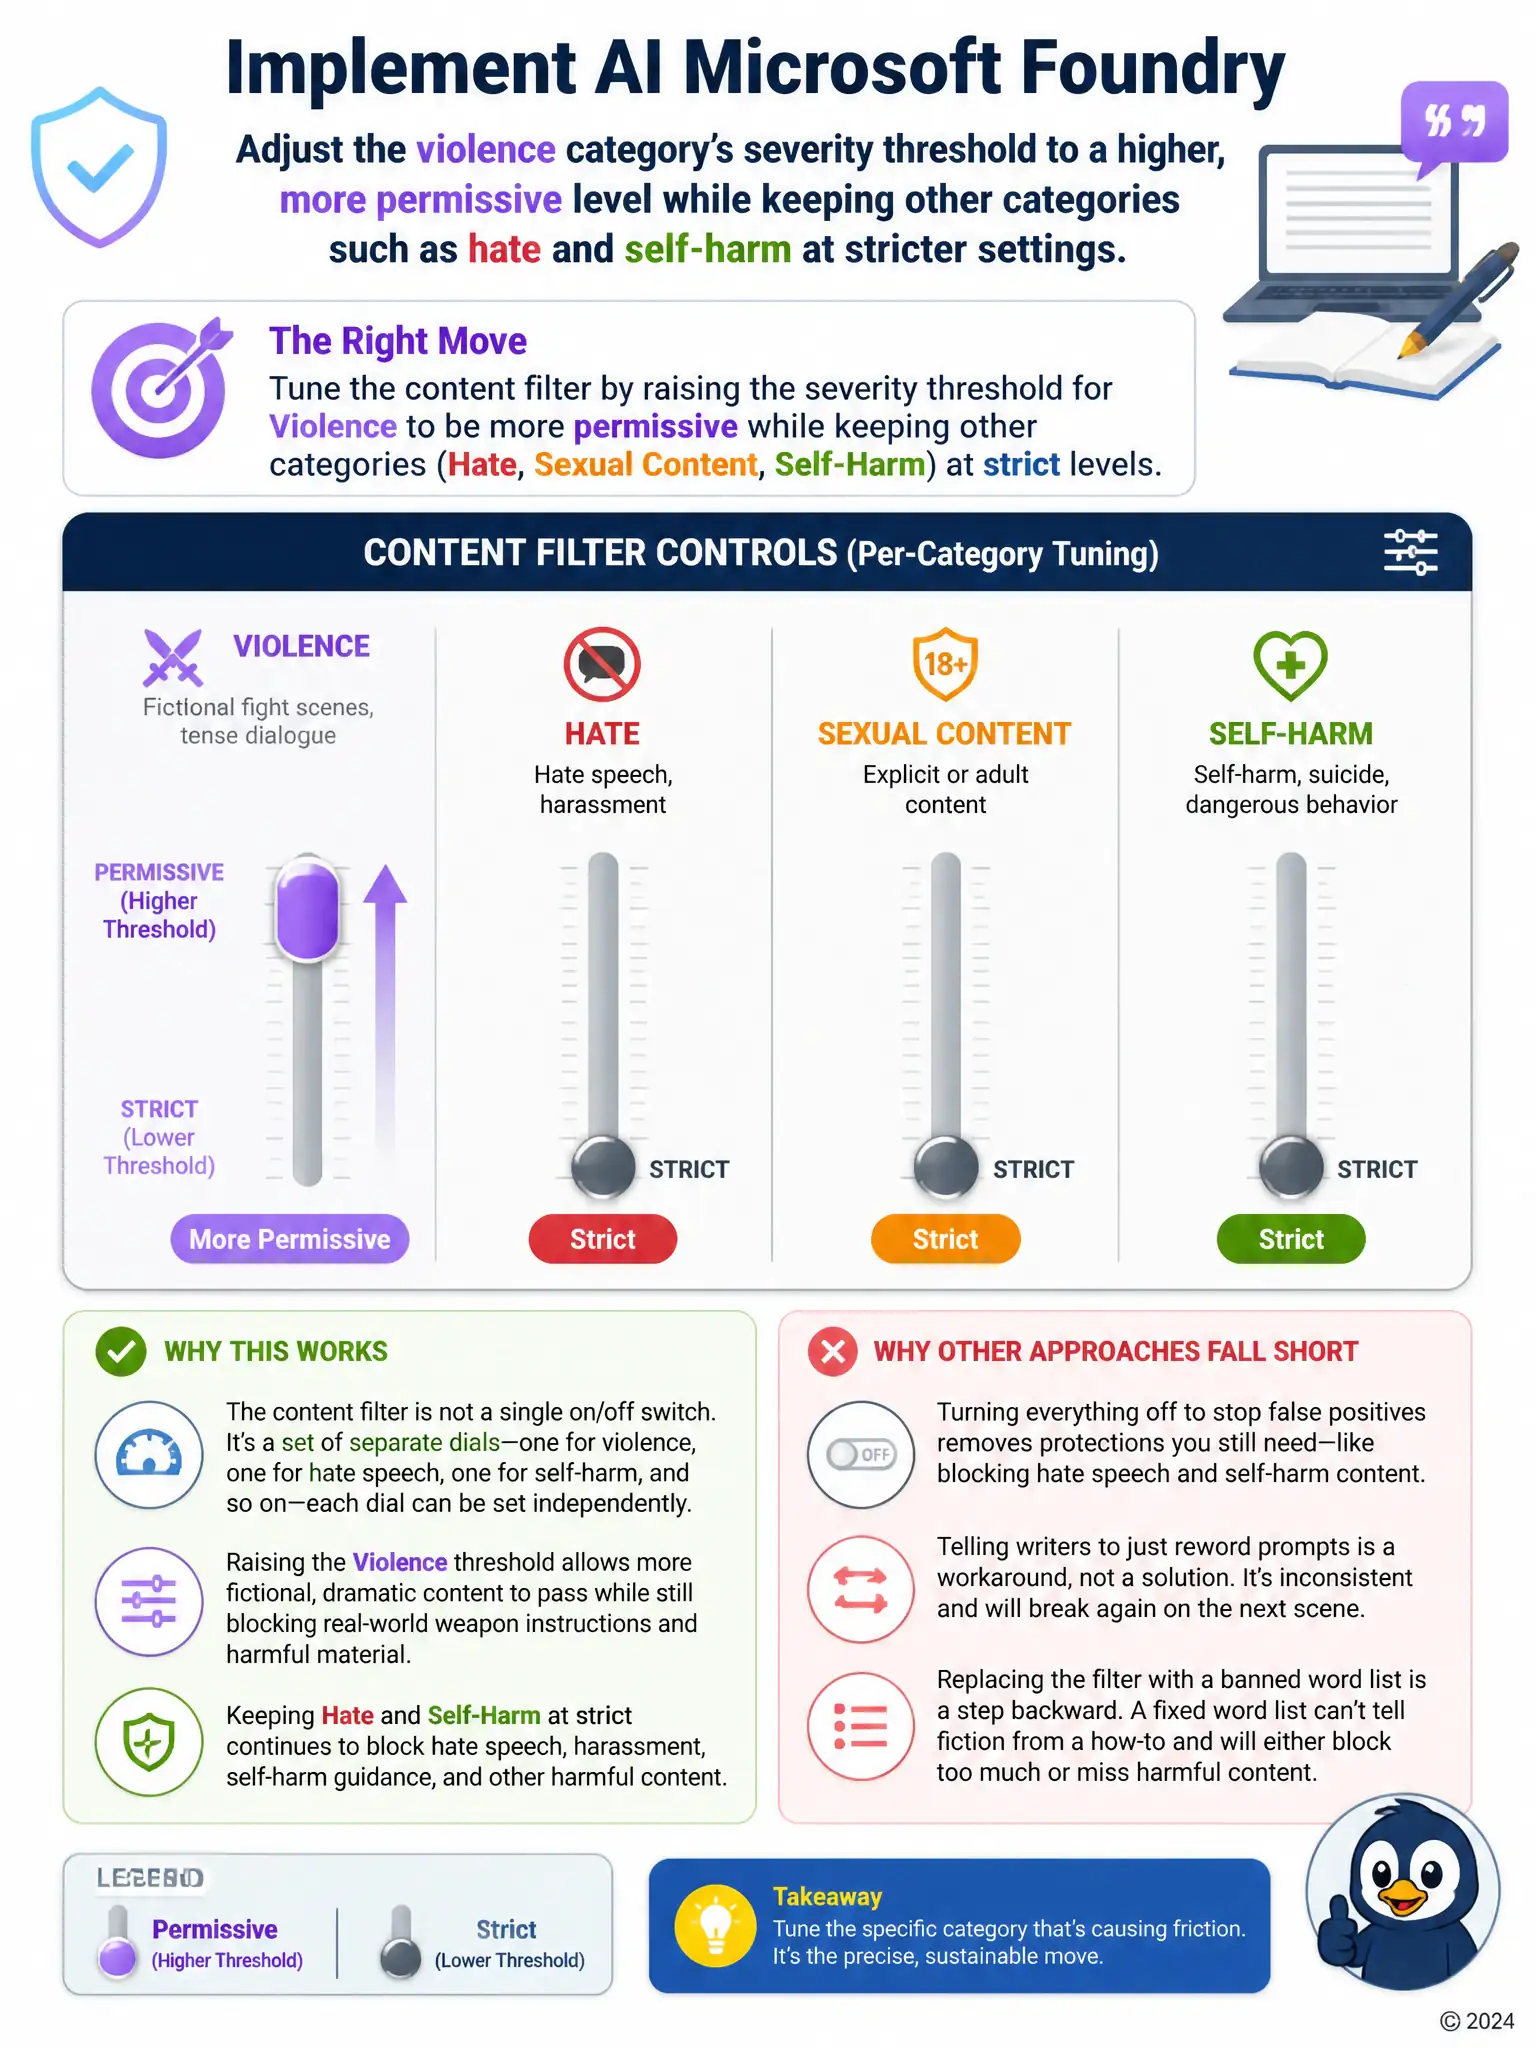
You don't need to rip out the whole filter. Turn the violence threshold up just enough for fictional dialogue, and keep hate and self-harm strict. That fixes the false positives without opening the door to real harm.
Full Explanation
The violence-category severity threshold adjustment is the right move because Foundry's content filtering lets each harm category, including violence, hate, sexual content, and self-harm, be configured with its own severity threshold. Raising the violence threshold to a higher, more permissive level lets you loosen filtering for fictional violent dialogue specifically while leaving hate speech and other categories at their stricter defaults. This targets the actual problem, overly aggressive blocking of narrative content, without removing protection the publisher still wants. The choice to disable content filtering entirely is wrong because it removes protection against hate speech and real-world harmful content too, which the publisher explicitly still wants blocked. The choice to keep the default filter configuration unchanged and instruct authors to rephrase their prompts is wrong because it leaves the underlying problem unsolved; authors rephrasing prompts to dodge an overly strict filter is unreliable, wastes their time, and does not represent a supported or repeatable configuration. The choice to replace content filtering with a custom keyword blocklist is wrong because a keyword blocklist cannot distinguish fictional dialogue from genuine harmful content the way a severity-tuned classifier can, and it will both over-block legitimate dramatic language and under-block harmful phrasing that avoids the listed words. Per-category severity tuning is the mechanism built for exactly this kind of selective adjustment.