
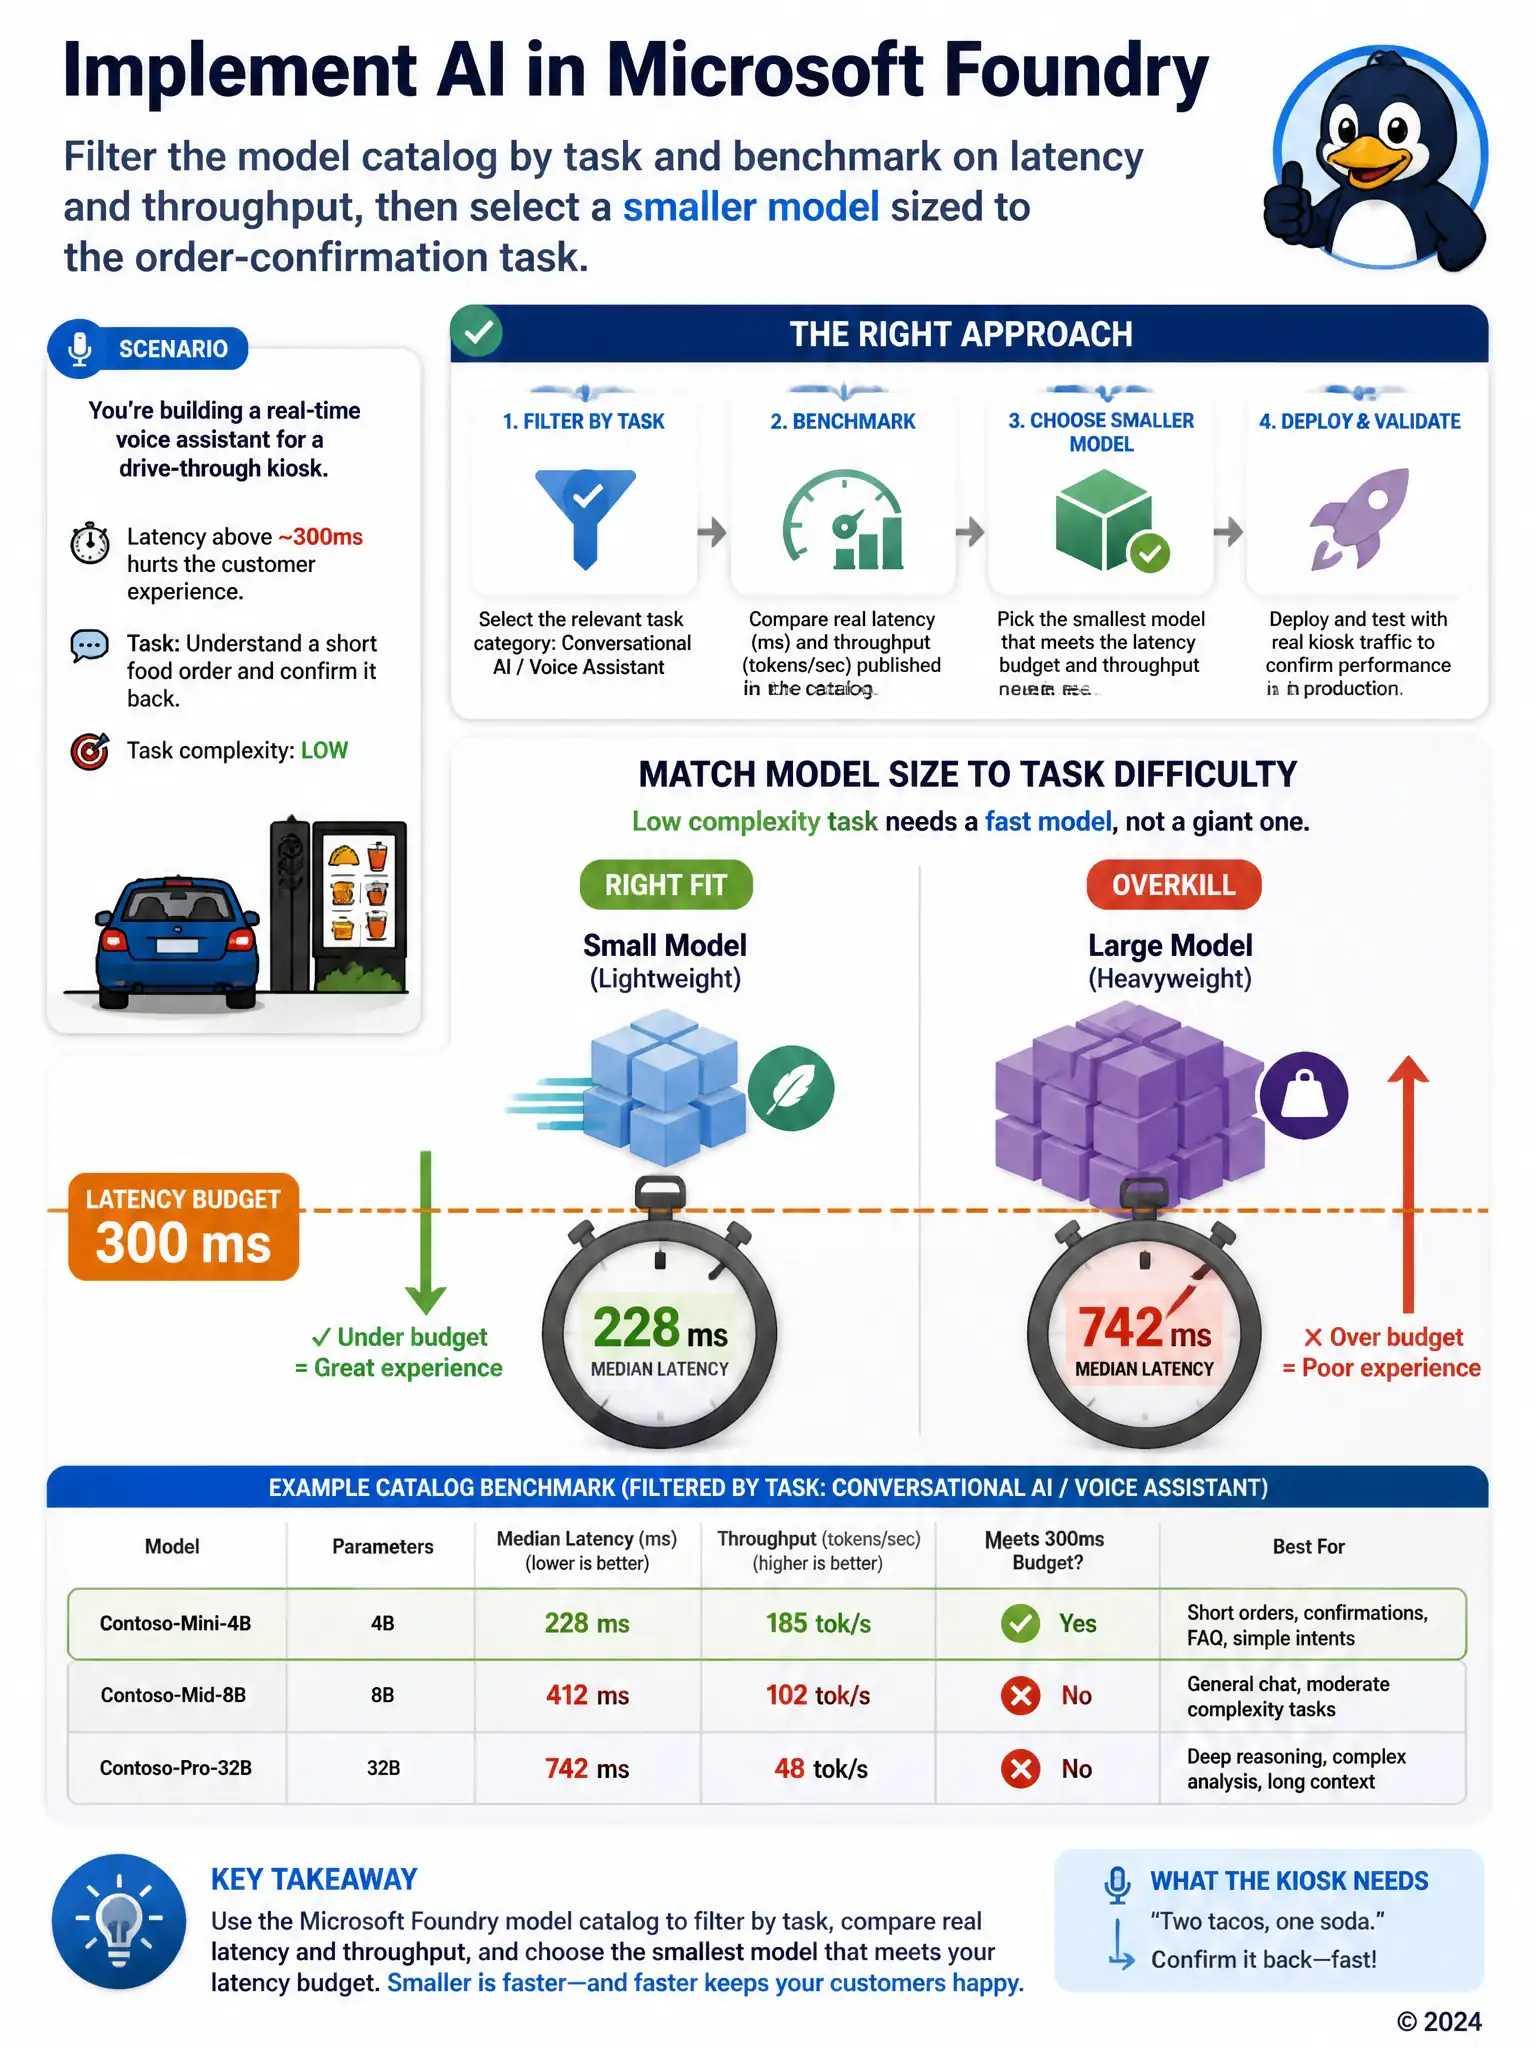
A team is building a real-time voice assistant for a drive-through kiosk using Microsoft Foundry. Response latency above roughly 300 milliseconds noticeably degrades the customer experience, and the assistant's task, understanding a short food order and confirming it back, does not require deep reasoning. Which model-selection approach in the Foundry model catalog best fits this scenario?
Select an answer to reveal the explanation.
Short Explanation
Think about what the kiosk has to do: hear a short order and confirm it fast. You want to filter Foundry's catalog by task and check latency and throughput, then pick a smaller model that fits the order-confirmation job. Bigger models just add wait time, and every extra hundred milliseconds hurts the customer.
Full Explanation
The best approach is to filter the model catalog by task and benchmark on latency and throughput, then select a smaller model sized to the order-confirmation task. The task, confirming a short food order, is narrow and low-complexity, while the binding constraint is latency, not reasoning depth. Foundry's model catalog lets teams filter candidate models by task type and compare published latency and throughput benchmarks, so the team can pick a smaller model that meets the sub-300-millisecond target while still handling order confirmation reliably. Deploying the largest general-purpose model in the catalog is incorrect because model size does not translate directly into fitness for a task; a large model adds inference time and cost without improving accuracy on a simple confirmation task, and may actually push latency past the acceptable threshold. Deploying two separate large models and averaging their outputs is incorrect because it multiplies latency and cost while adding complexity, working against the stated goal of a fast response. Skipping the model catalog and fine-tuning the largest available foundation model on drive-through audio before deployment is incorrect because it is an expensive, slow path that still leaves the team with a large model's inference latency; it addresses accuracy on domain-specific audio, not the speed constraint that is actually driving the decision here. Sizing the model to the task using catalog benchmarks is the direct, low-cost way to meet a hard latency requirement.