
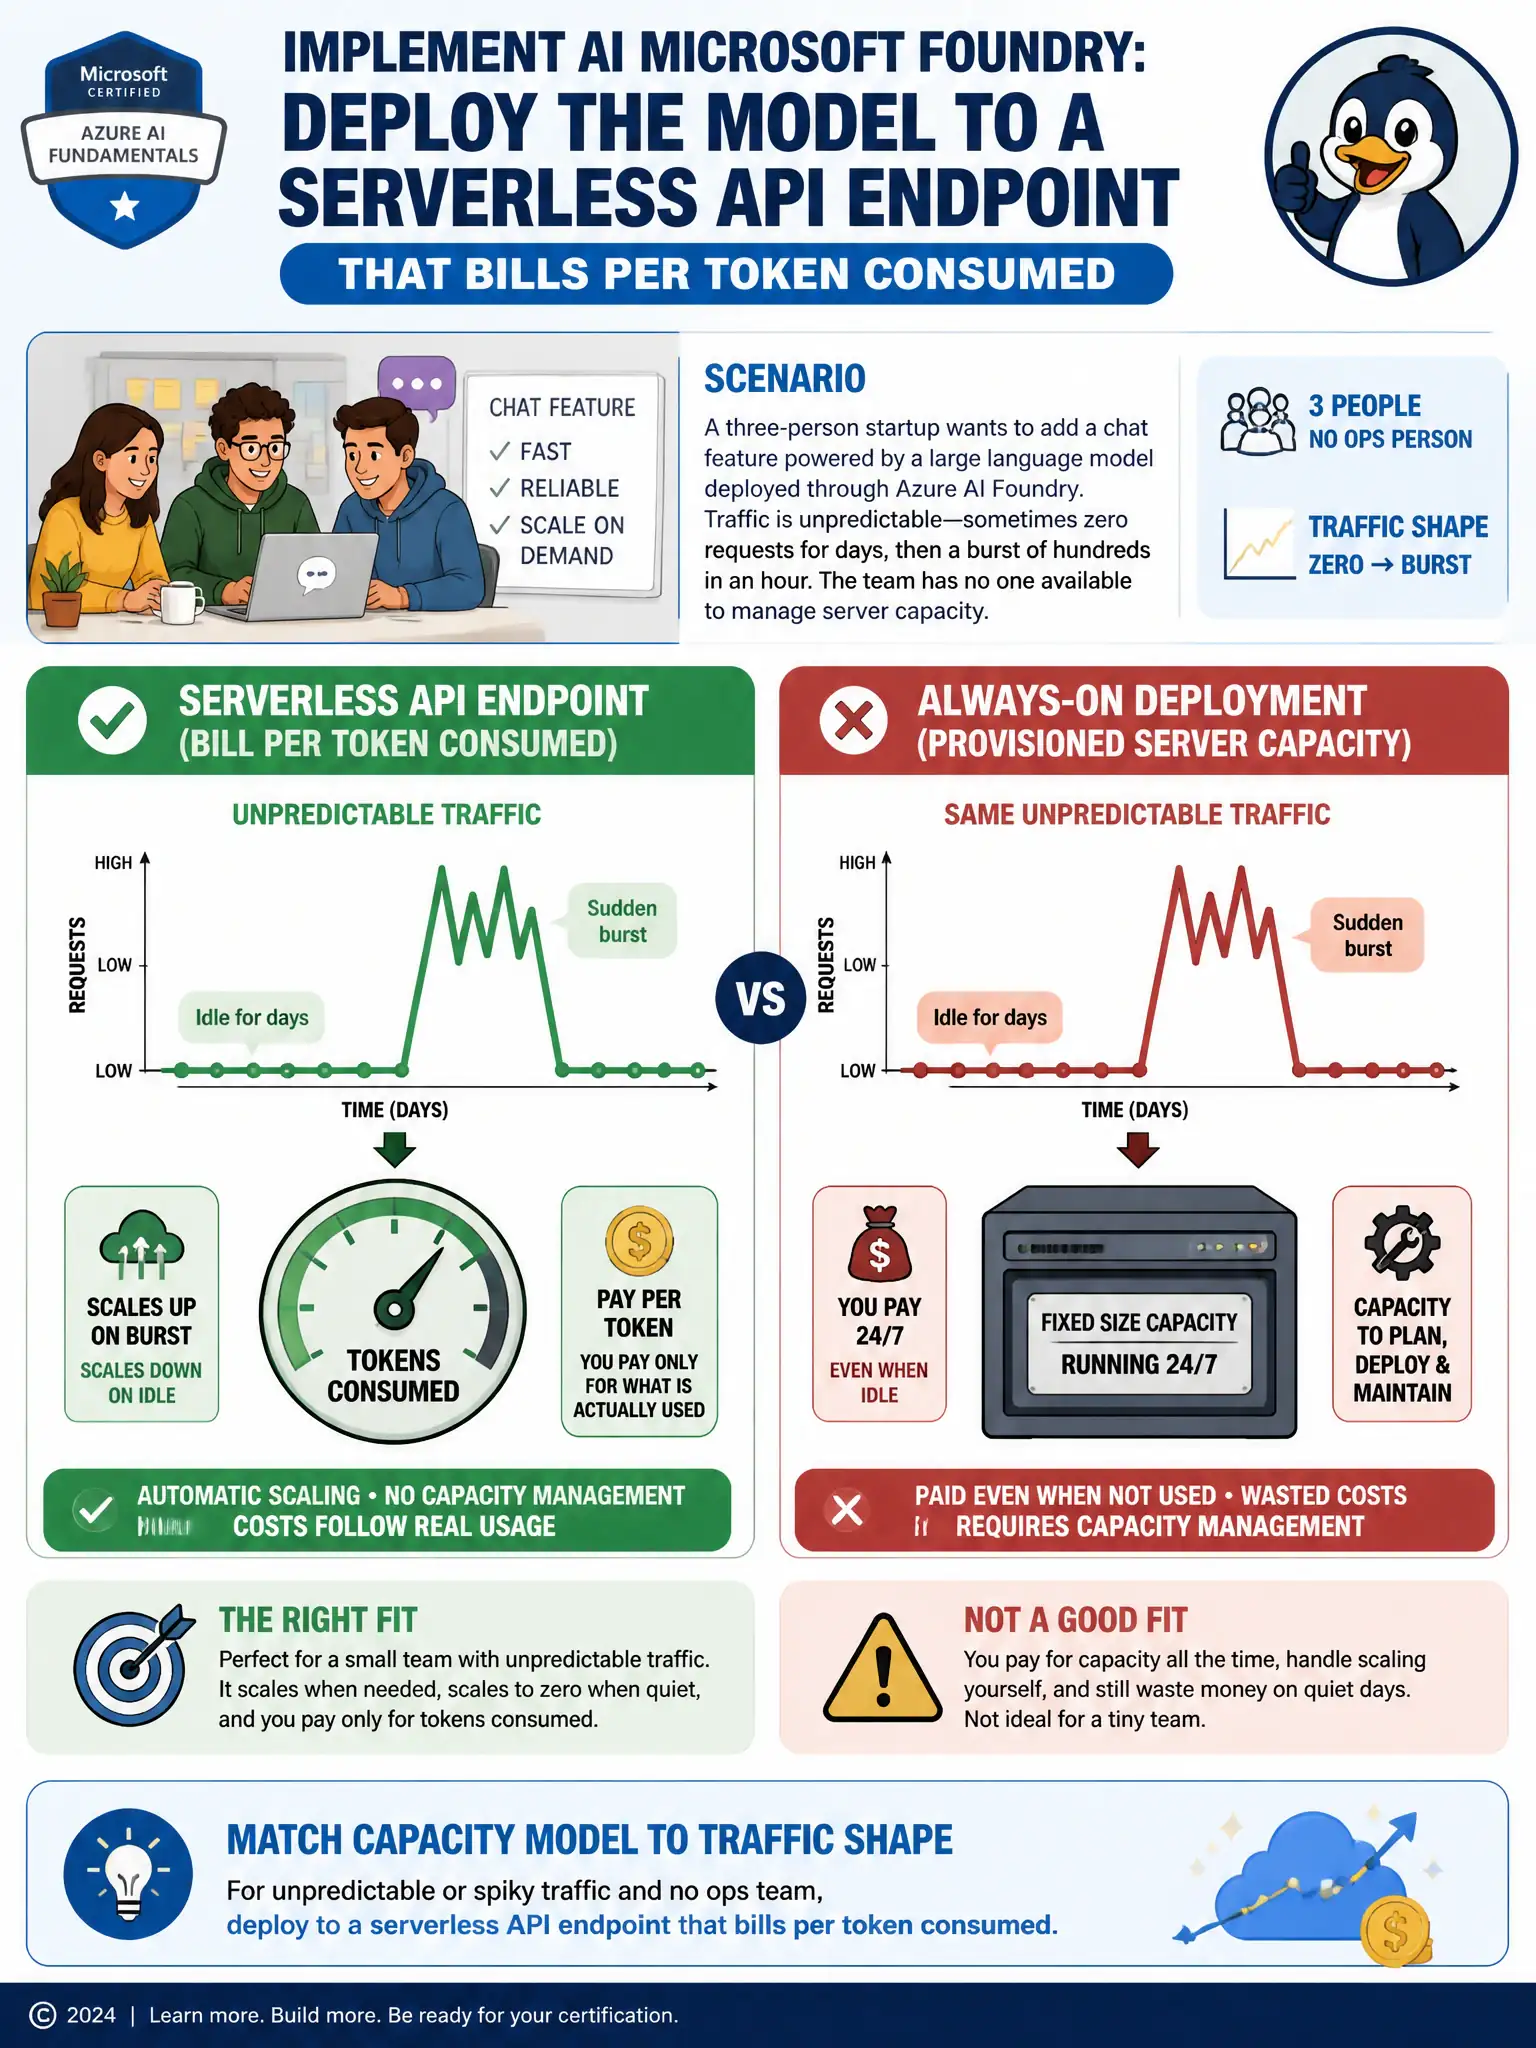
A three-person startup wants to add a chat feature powered by a large language model deployed through Azure AI Foundry. Traffic is unpredictable, sometimes zero requests for days and then a burst of hundreds in an hour, and the team has no one available to manage server capacity. Which deployment option should they choose for the model?
Select an answer to reveal the explanation.
Short Explanation
You need a serverless API endpoint that bills per token consumed because your traffic can go from zero to a flood without warning. It scales itself up during bursts and back down when quiet, so nobody has to babysit capacity. That keeps billing tied to actual usage instead of a guess about how big to build the server ahead of time.
Full Explanation
The correct answer is the serverless API endpoint that bills per token consumed. A serverless API endpoint in Azure AI Foundry bills per token consumed and scales automatically, which fits a workload that swings between idle and bursty without anyone available to plan or manage capacity. The dedicated managed-compute endpoint sized for the peak hourly burst and left running continuously is incorrect because it means paying for idle capacity during the many quiet days, which is wasteful for a three-person team's budget and still requires someone to monitor and resize it over time. Downloading the model weights and hosting them on a self-managed virtual machine scale set is incorrect because it shifts all patching, scaling, and capacity planning onto the team, exactly the operational burden they explicitly cannot take on. Requesting a batch inference job that processes queued requests once per day is incorrect because the once-a-day batch job cannot support a chat feature, which needs responses within seconds of a user typing a message, not a daily processing window. The serverless option removes infrastructure management and aligns cost with actual usage, making it the right fit for this scenario's combination of unpredictable traffic and limited staff.