
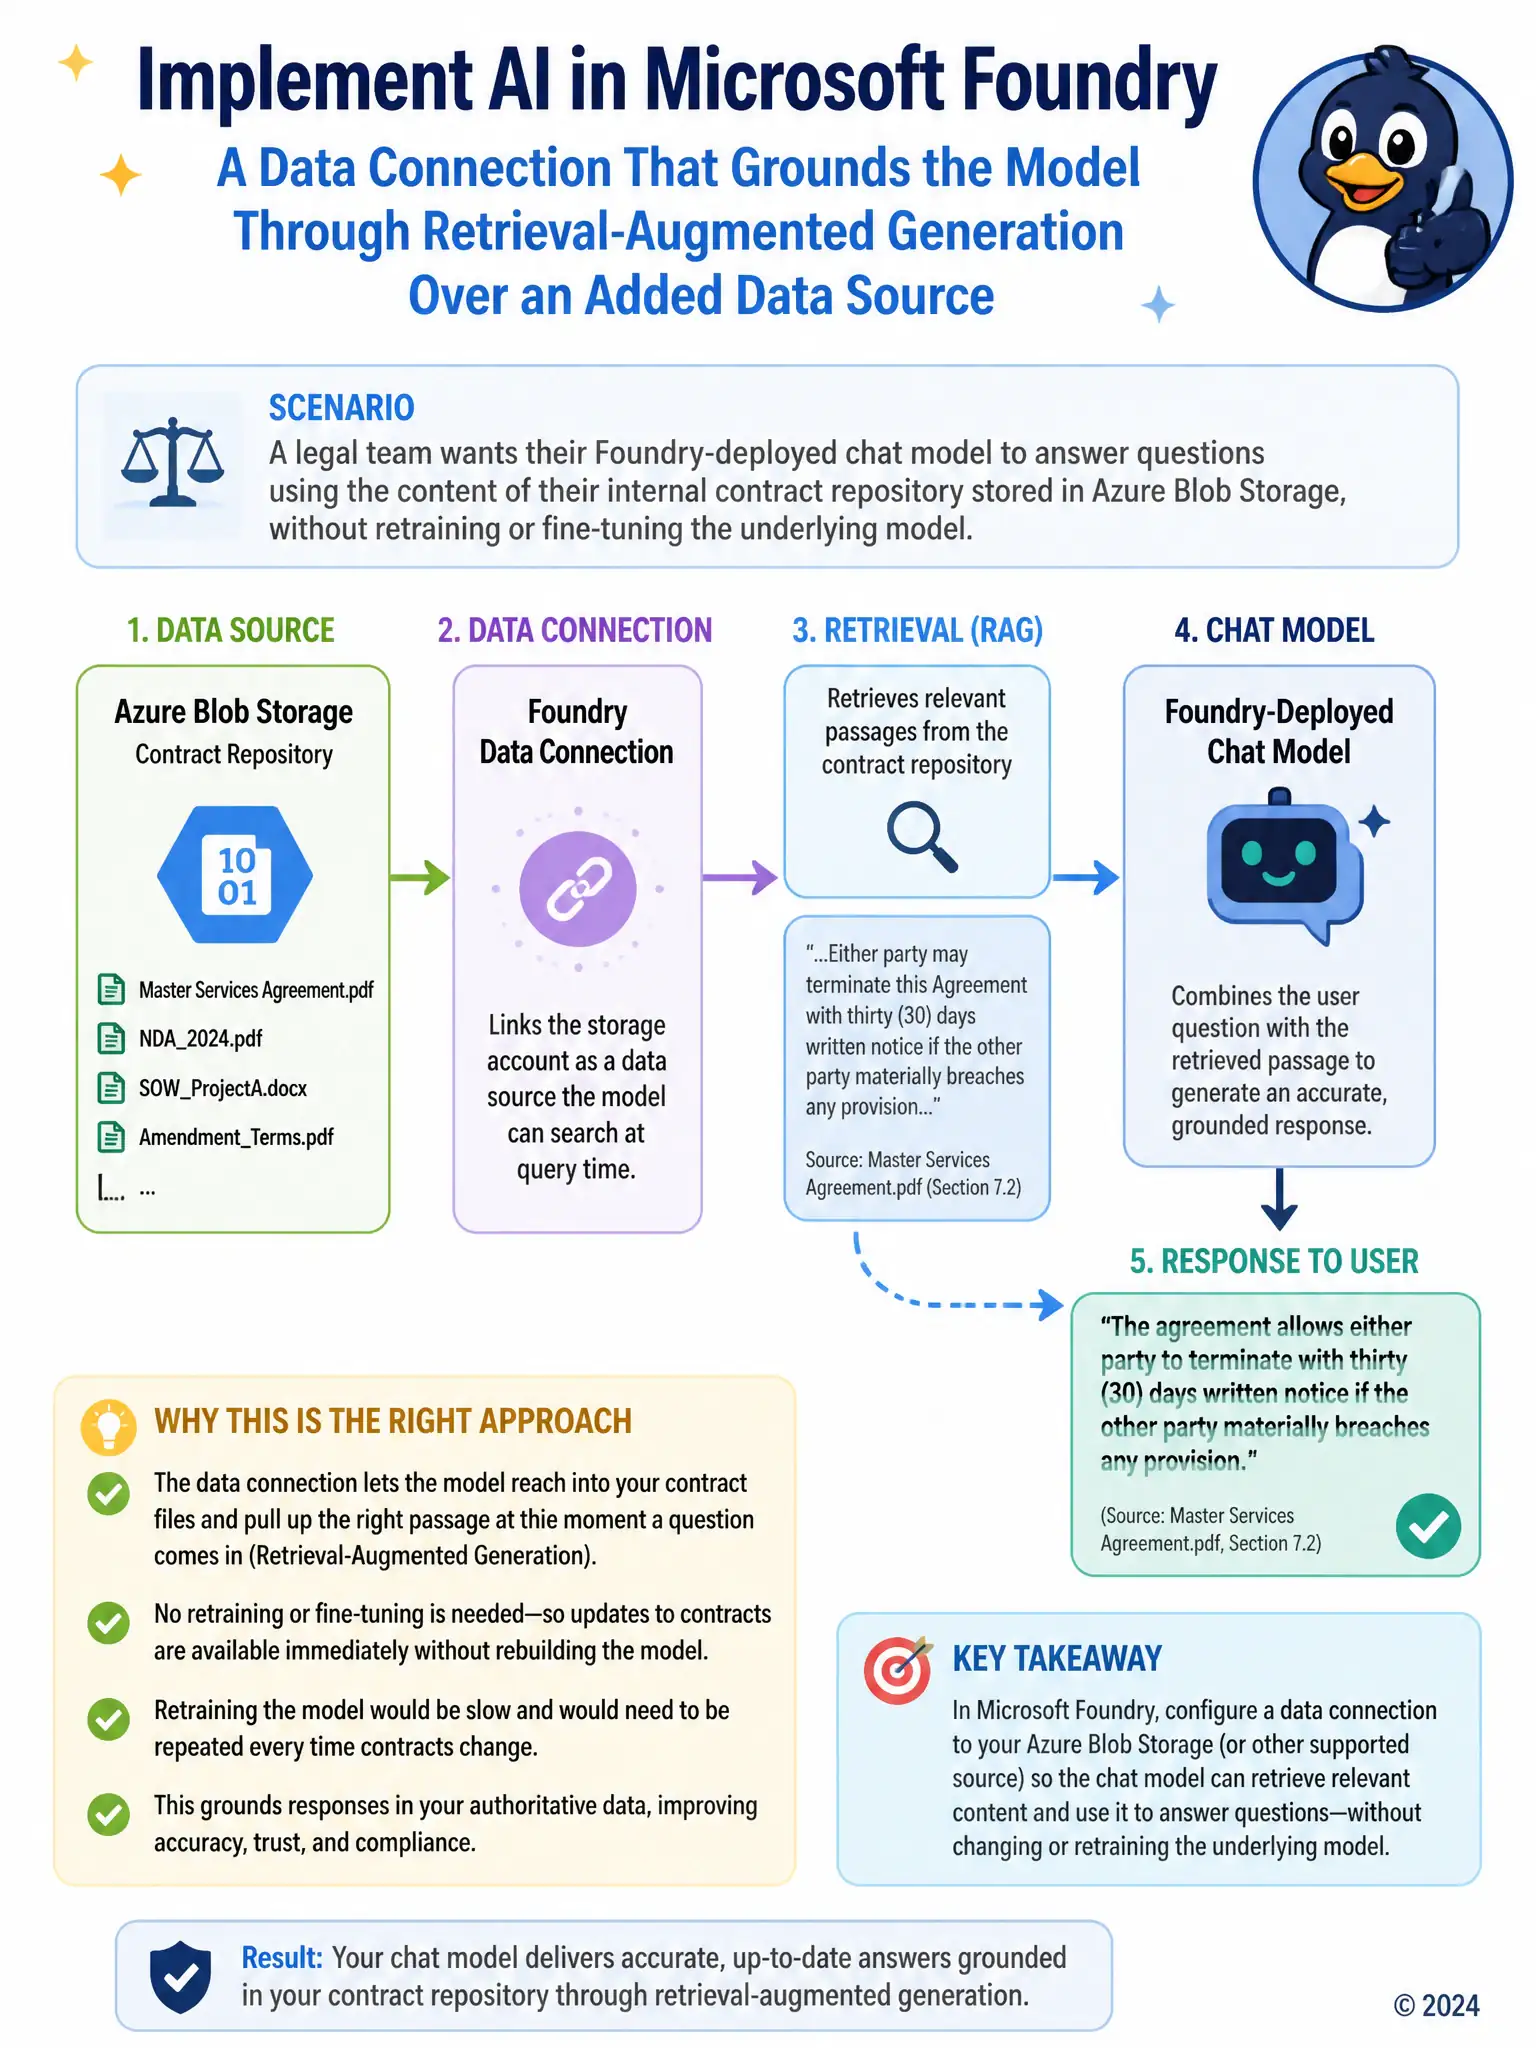
A legal team wants their Foundry-deployed chat model to answer questions using the content of their internal contract repository stored in Azure Blob Storage, without retraining or fine-tuning the underlying model. Which Foundry feature should they configure to link that storage account so retrieved contract text augments the model's responses at query time?
Select an answer to reveal the explanation.
Short Explanation
You want the chat model to reach into contract files and pull the right passage when someone asks questions, without baking that content into the model. Link the storage account as data source so Foundry can search it and ground answers at query time. That's retrieval-augmented generation, not retraining.
Full Explanation
The right choice is the data connection that grounds the model through retrieval-augmented generation over an added data source. It lets Foundry index and retrieve relevant contract text from the linked storage account at query time, grounding the model's responses in that content without altering the model's underlying weights. The fine-tuning choice is wrong because it retrains the model on repository content, which directly contradicts the requirement to avoid retraining, and it is poorly suited to contract repositories that change over time since the model would need retraining after every update. The maximum output token limit choice is wrong because it only controls how long generated responses can be; it has no effect on whether the model can access or retrieve external contract documents. The switching region choice is wrong because matching deployment region to storage account region may reduce network latency, but proximity alone does not connect the storage account as retrievable data source; the model still needs an explicit data connection to know content exists and pull from it. The data connection is the mechanism that ties external content to model responses at query time.