
A mid-size law firm wants an internal chatbot that answers questions strictly from its own contract archive and can point staff to the specific clause it used, rather than relying only on what a general-purpose language model already knows. Which approach in Microsoft Foundry best meets this requirement?
Select an answer to reveal the explanation.
Short Explanation
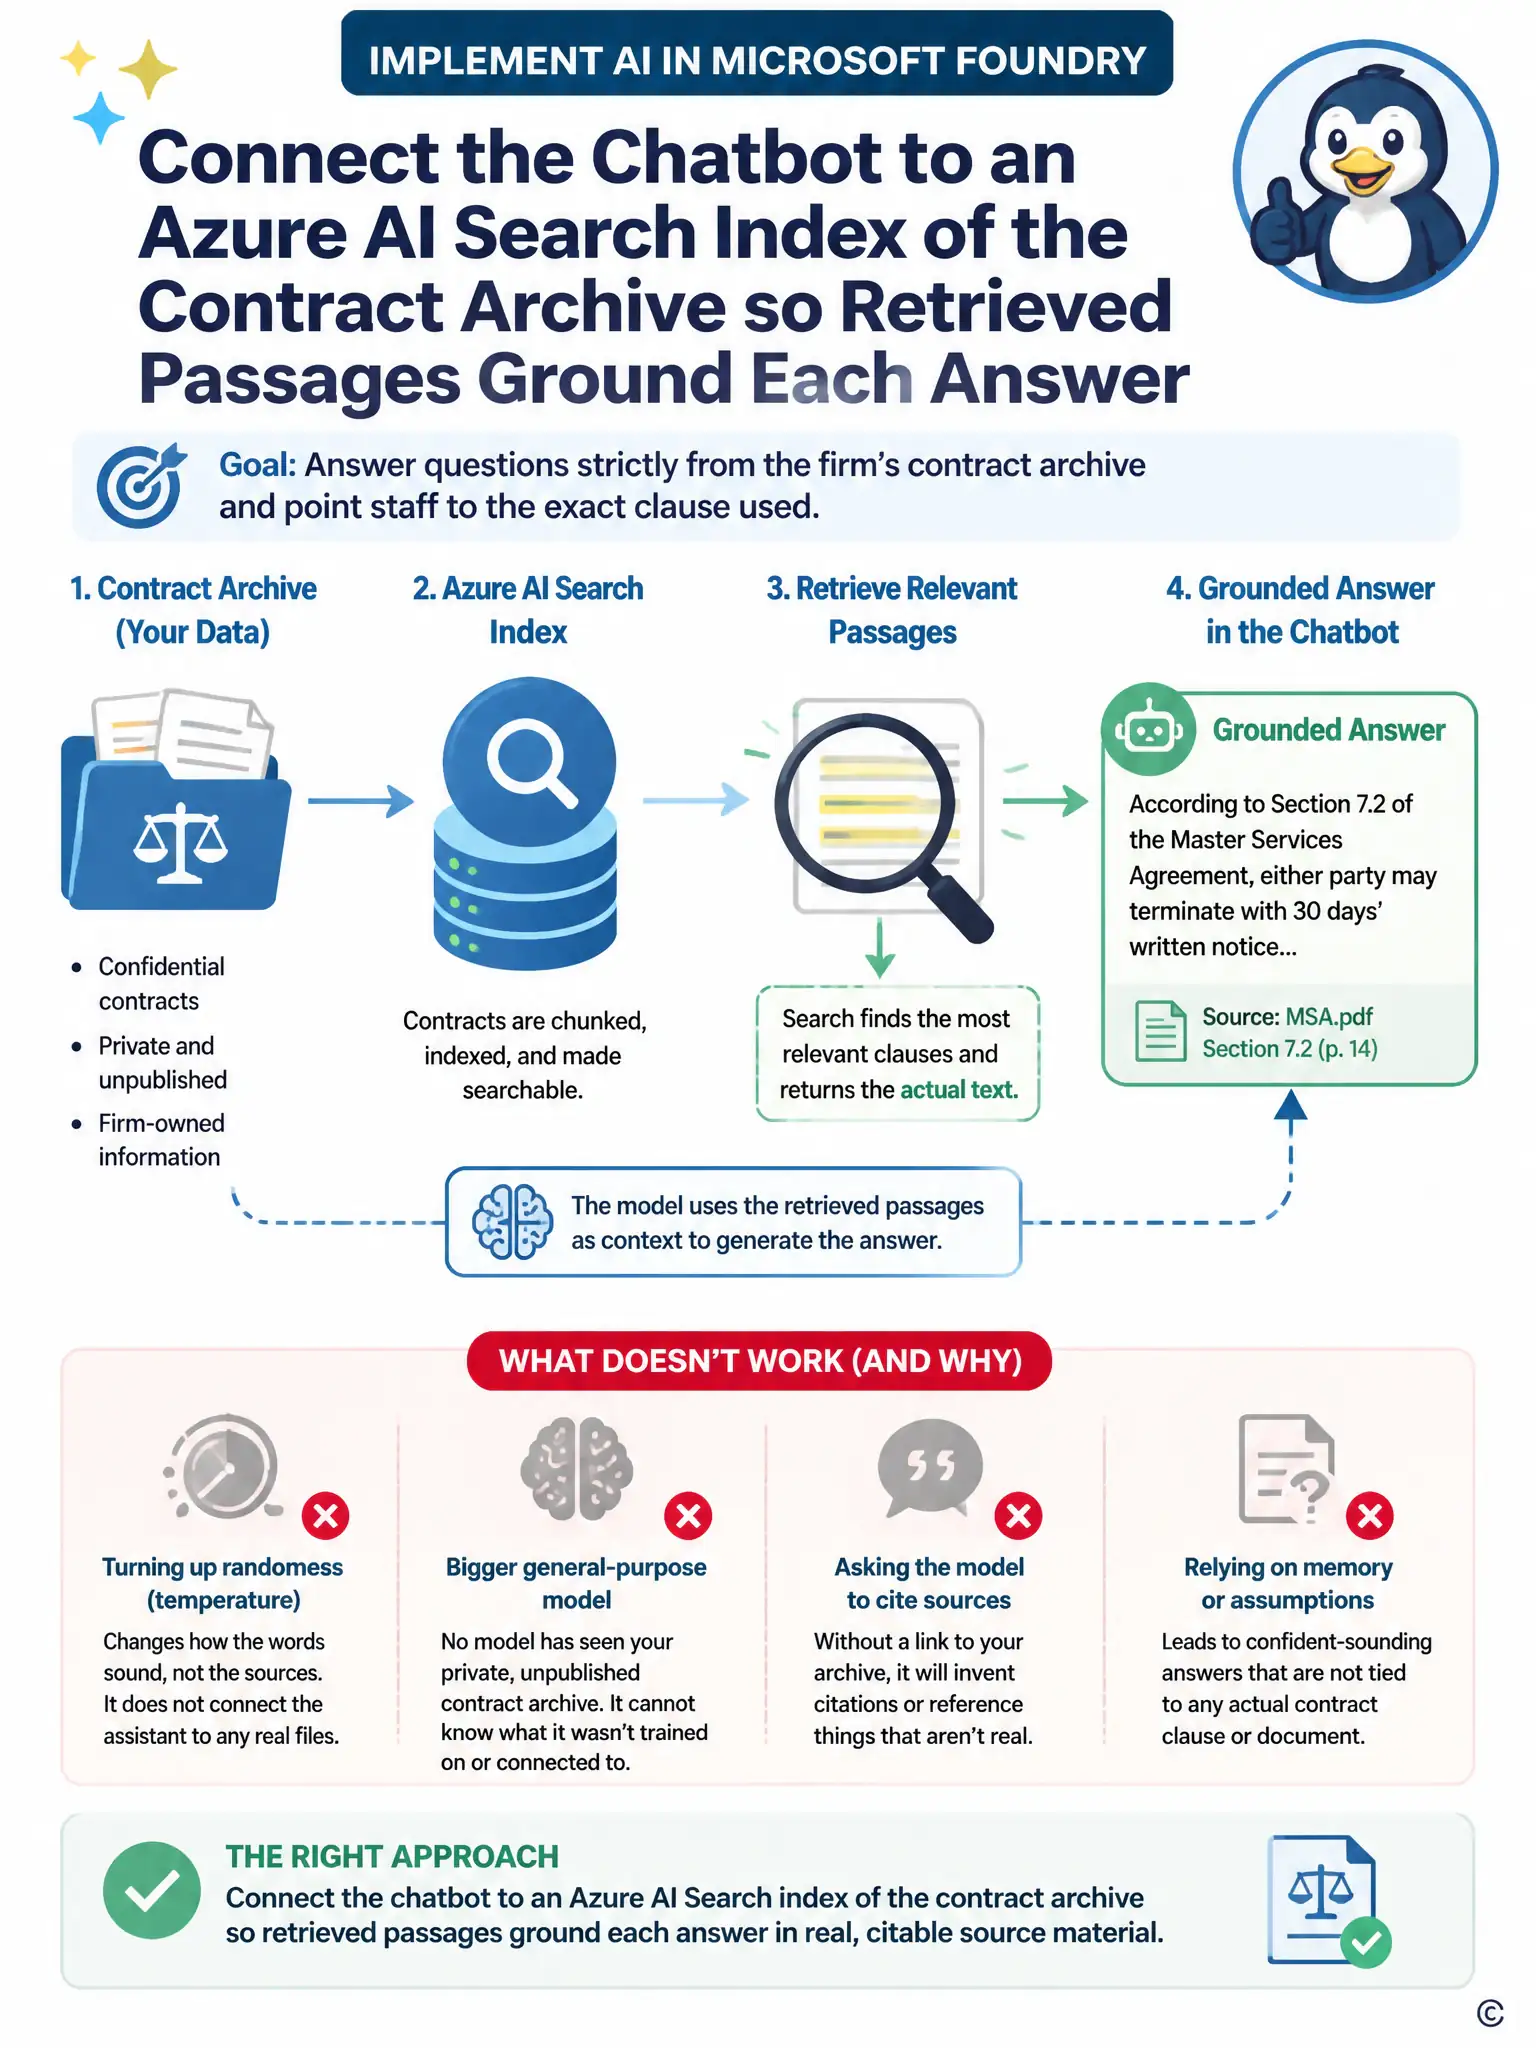
Think of it like giving the assistant a librarian instead of just a good memory. When you connect the chatbot to an Azure AI Search index over the firm's contract archive, it pulls the relevant clause first and builds the answer around that real text, so staff can trace it to an actual document.
Full Explanation
Connecting the chatbot to an Azure AI Search index built from the firm's own contract archive implements the retrieval-augmented generation pattern: relevant passages are retrieved at query time and passed to the model as context, so answers are grounded in the firm's actual documents and can reference the specific clause used. Increasing the model's temperature setting is incorrect because raising temperature only changes how varied or creative the wording of a response is; it does nothing to connect the model to private data or improve factual grounding. Switching to a larger foundation model is incorrect because no foundation model, regardless of size, has been trained on a specific firm's private, unpublished contracts, so a larger model cannot inherently know their contents. Asking the model to cite sources from its general training data without connecting any firm data is incorrect because a model with no connection to the firm's data can only reference its general training sources, which do not include the firm's confidential archive, so any citation it produces would be fabricated or irrelevant. Grounding through a search index over the firm's own content is what allows accurate, traceable answers tied to real clauses rather than plausible-sounding guesses.