
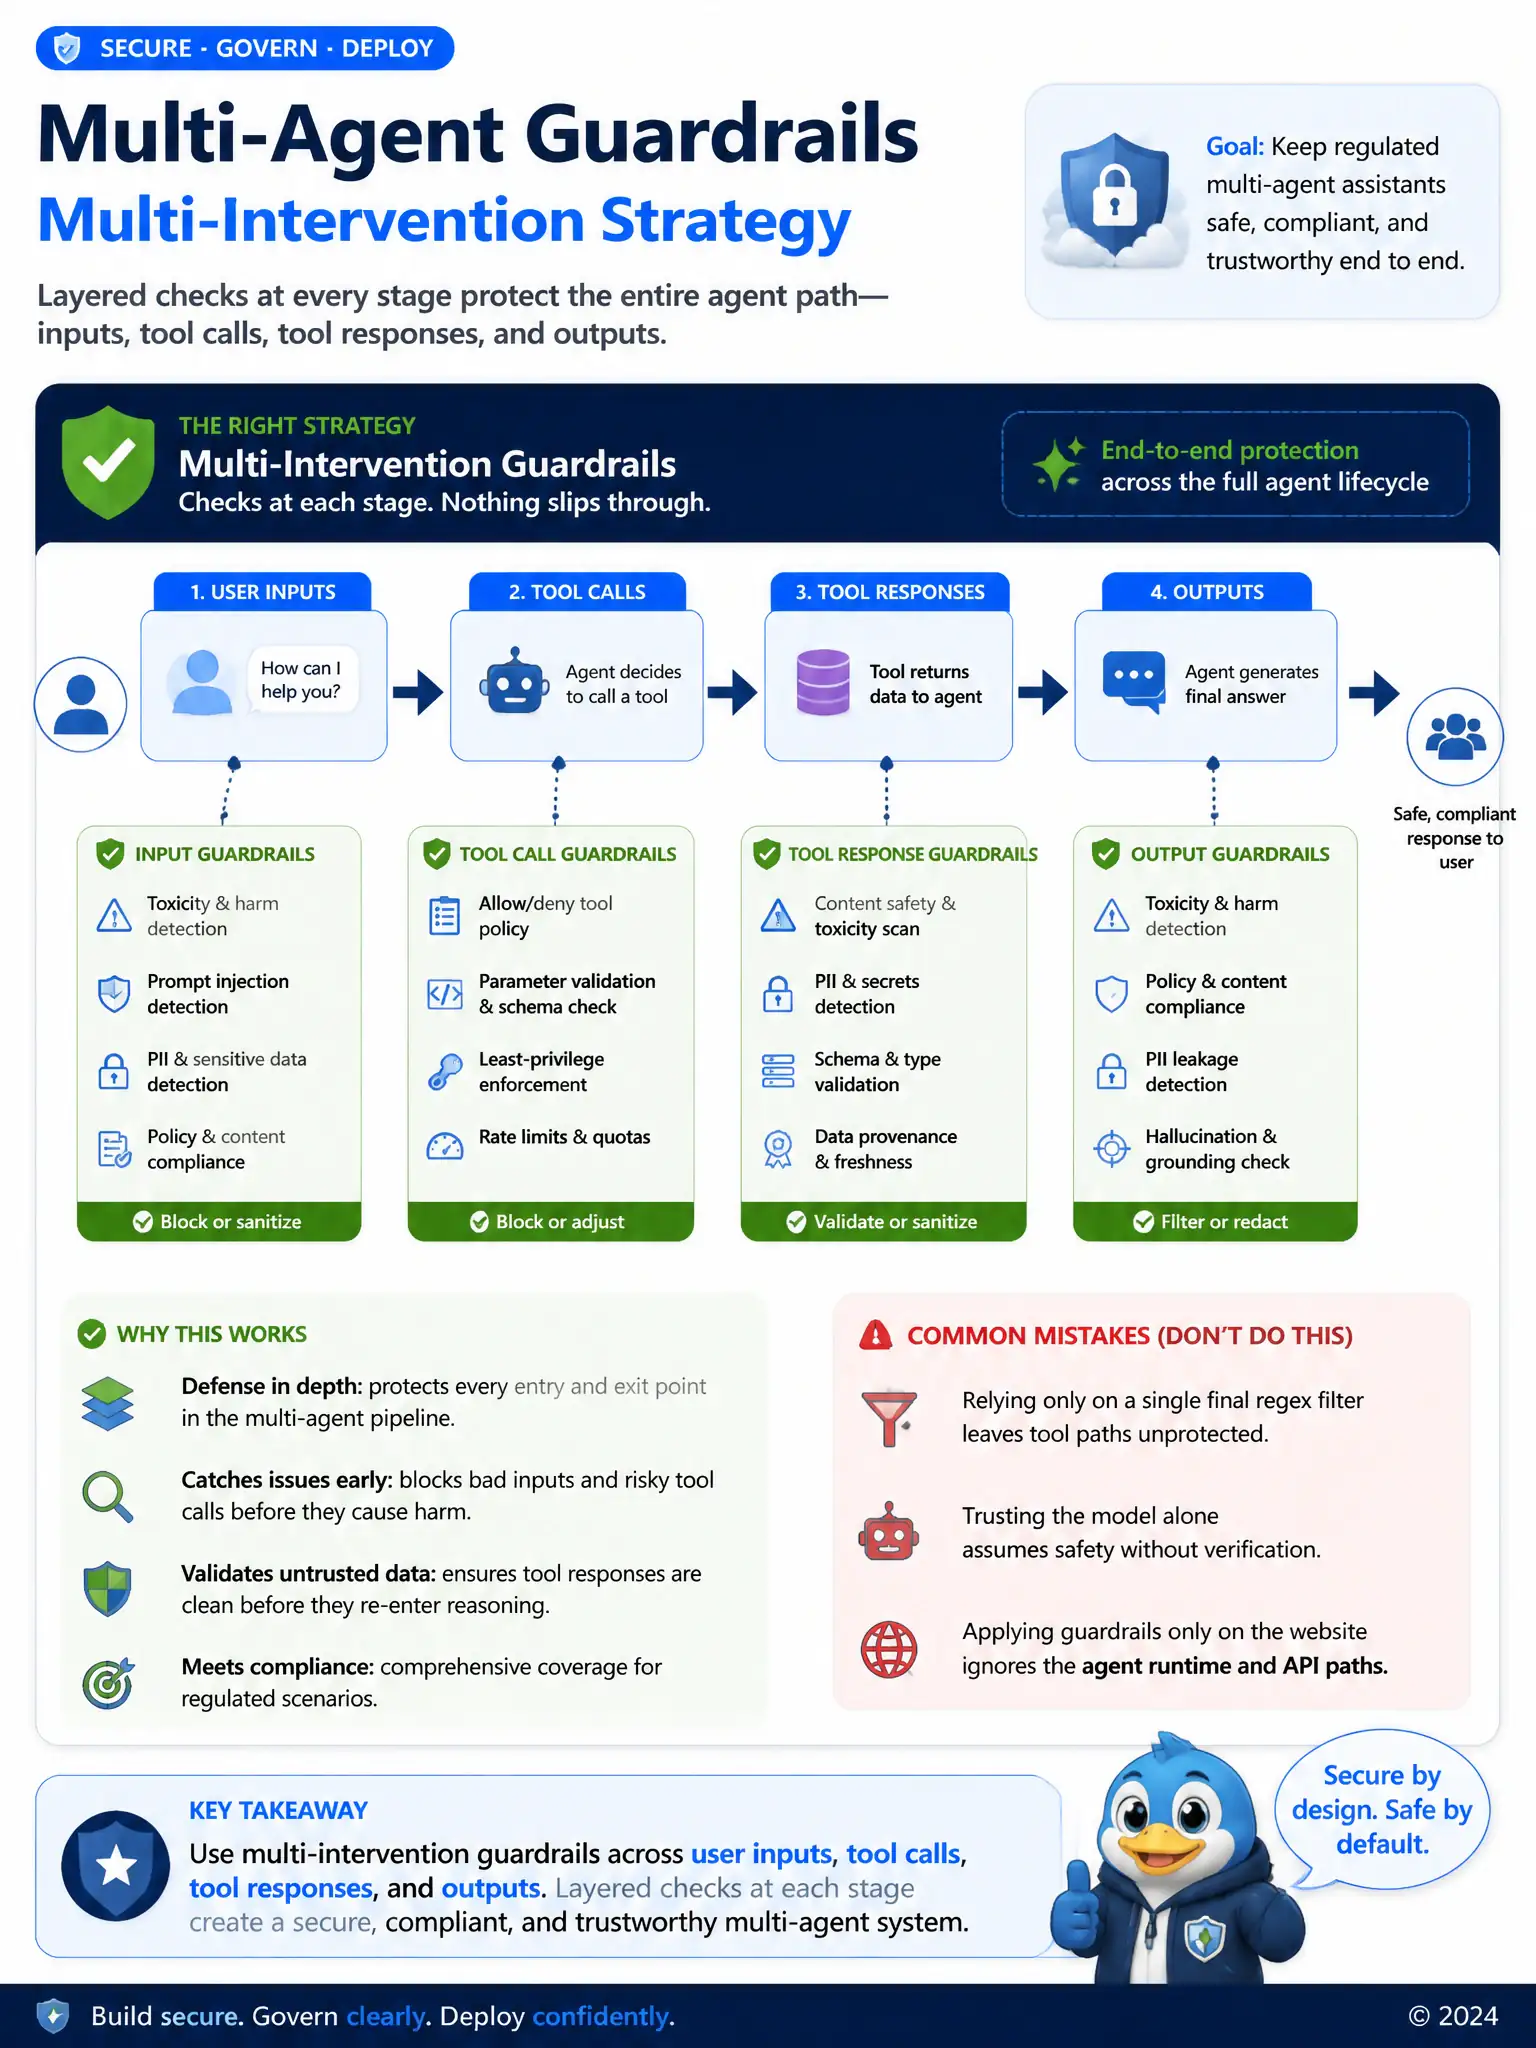
A regulated multi-agent assistant must block toxic user inputs, prevent disallowed tool calls, validate tool responses before they re-enter reasoning, and filter final answers for policy violations. What guardrail strategy matches this requirement?
Select an answer to reveal the explanation.
Short Explanation
You need a multi-intervention guardrail strategy that checks user inputs, tool calls, tool responses, and final answers. Final-only filtering or trusting the base model alone leaves tool paths unprotected. Marketing-copy-only guardrails don't control the agent runtime.
Full Explanation
The correct strategy is multi-intervention guardrails covering user inputs, tool calls, tool responses, and outputs, with layered checks at each stage. Design guardrails so unsafe content cannot enter, unsafe tools cannot run, poisoned tool results cannot steer the agent, and unsafe answers cannot leave. Each stage may use different detectors, such as content safety checks, allowlisted tools, schema validation, and output filters. The single post-processing regex on the final sentence only is incomplete because final-only filtering misses malicious tool invocation and bad tool payloads. Trusting the base model alone with no additional controls is incorrect because base models aren't sufficient policy engines for regulated multi-agent systems. Guardrails only on marketing website copy, not on agents, is incorrect because product marketing pages are outside the agent execution path that needs control. Test guardrails with synthetic adversarial data and measure false positive/negative rates.