
An internal knowledge multi-agent system answers similar HR policy questions thousands of times per day. Token spend is high even though many user phrasings map to the same grounded answer. You need lower latency and cost without serving stale policy after documents change. Which caching strategy is most appropriate?
Select an answer to reveal the explanation.
Short Explanation
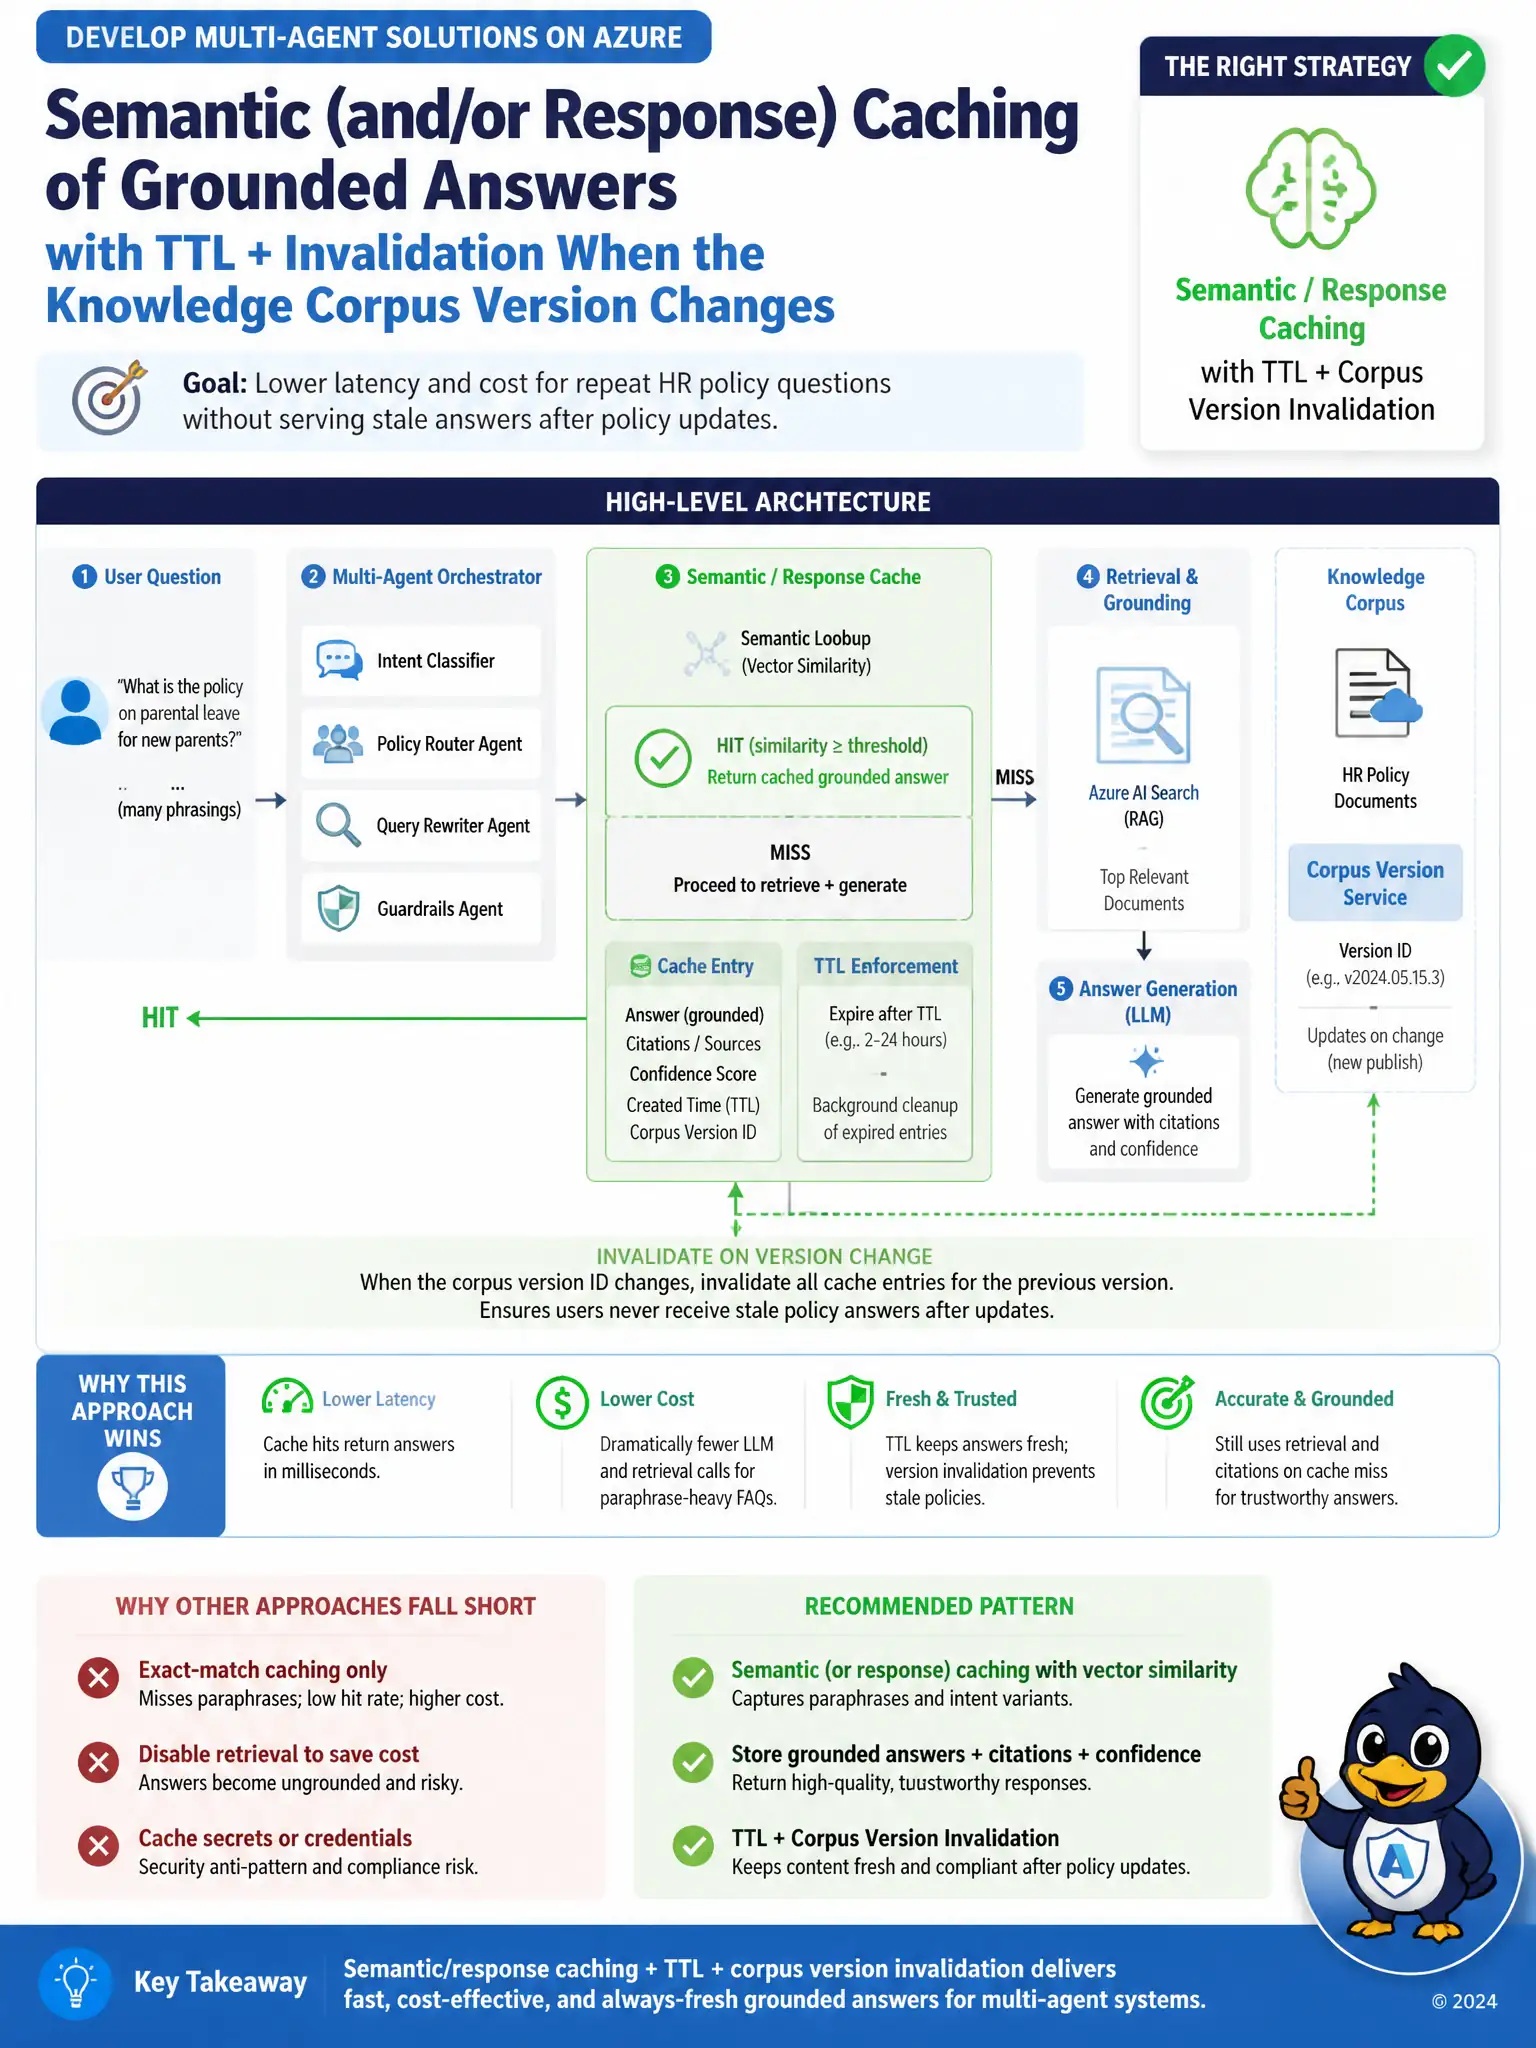
You want semantic or response caching of grounded answers, with TTL and invalidation when the knowledge corpus version changes. It catches paraphrased HR questions, cuts latency and token spend, and avoids serving stale policy.
Full Explanation
The appropriate strategy is semantic and/or response caching of grounded answers, with TTL plus invalidation when the underlying knowledge corpus version changes. Multi-agent solutions should design caching strategies that include prompt caching, semantic caching, and response caching. For repetitive HR Q&A, embed the question or normalized intent, look up a prior grounded answer, and return it when similarity exceeds a threshold—subject to TTL and knowledge-version keys so updates invalidate cache entries. Exact-byte prompt caching with no invalidation is weaker because exact string matching fails on paraphrases that dominate real traffic and never invalidating guarantees stale policy. Disabling retrieval so every answer relies on pure parametric model memory is wrong because it drops RAG grounding required for policy accuracy. Storing user passwords in the agent response cache is wrong and unsafe because secrets must never live in answer caches; use proper identity systems. Also consider per-tenant cache keys to preserve isolation in multi-tenant Foundry deployments.