
A multi-agent workflow calls an external pricing API tool that intermittently returns 503s. You need robust tool error handling and fallback so the orchestration does not crash the user session. What should you implement?
Select an answer to reveal the explanation.
Short Explanation
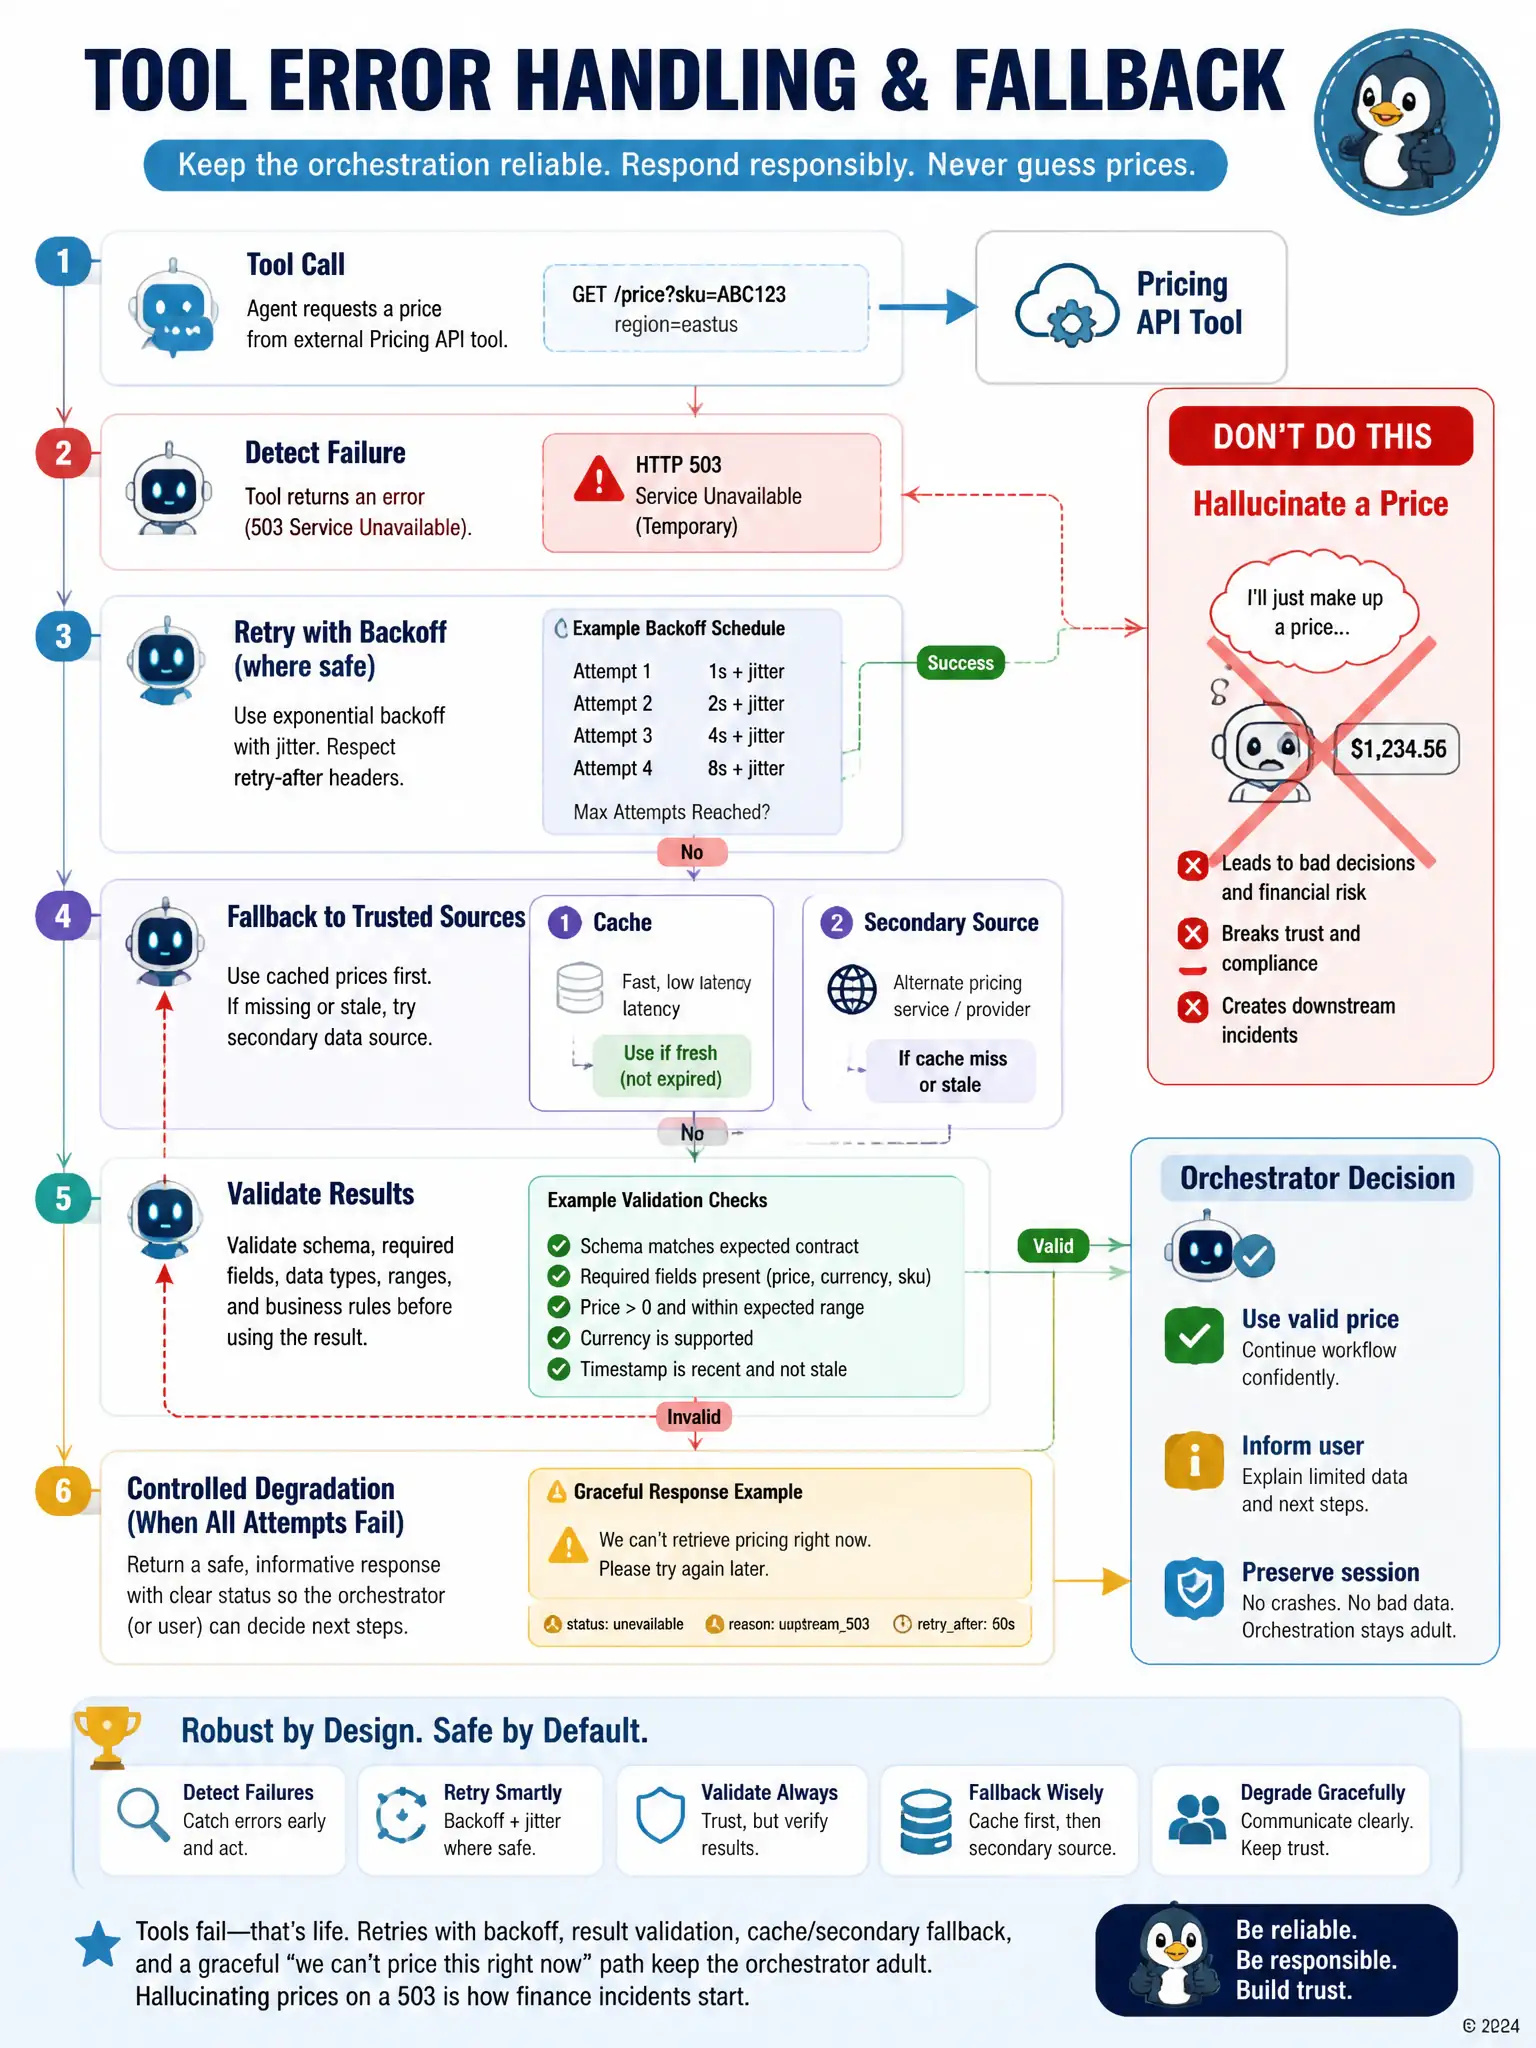
Tools fail—that’s life. You need retries with backoff, result validation, cached or secondary fallbacks, and a controlled degradation path so the orchestrator stays stable. Inventing prices after a 503 is how finance incidents start.
Full Explanation
Tool error handling must detect failures, retry with backoff where safe, validate results, fall back to cached prices or a secondary source, and expose controlled degradation to the orchestrator/user. That is production-grade behavior for flaky tools. Ignoring HTTP errors and inventing prices is unsafe hallucination on failure. Terminating the entire multi-agent application process on the first tool exception is brittle and poor UX/ops practice. Disabling error logging removes observability needed to fix the dependency. Exam tip: correct tool-resilience answers combine retry/validate/fallback/degrade, not silent invention of data.