
A multi-agent release checklist currently only unit-tests Python helpers. Failures in production are often caused by bad tool schemas, weak retrieval, prompt regressions, or memory mis-scoping—not helper functions. What evaluation design should the team add before promotion?
Select an answer to reveal the explanation.
Short Explanation
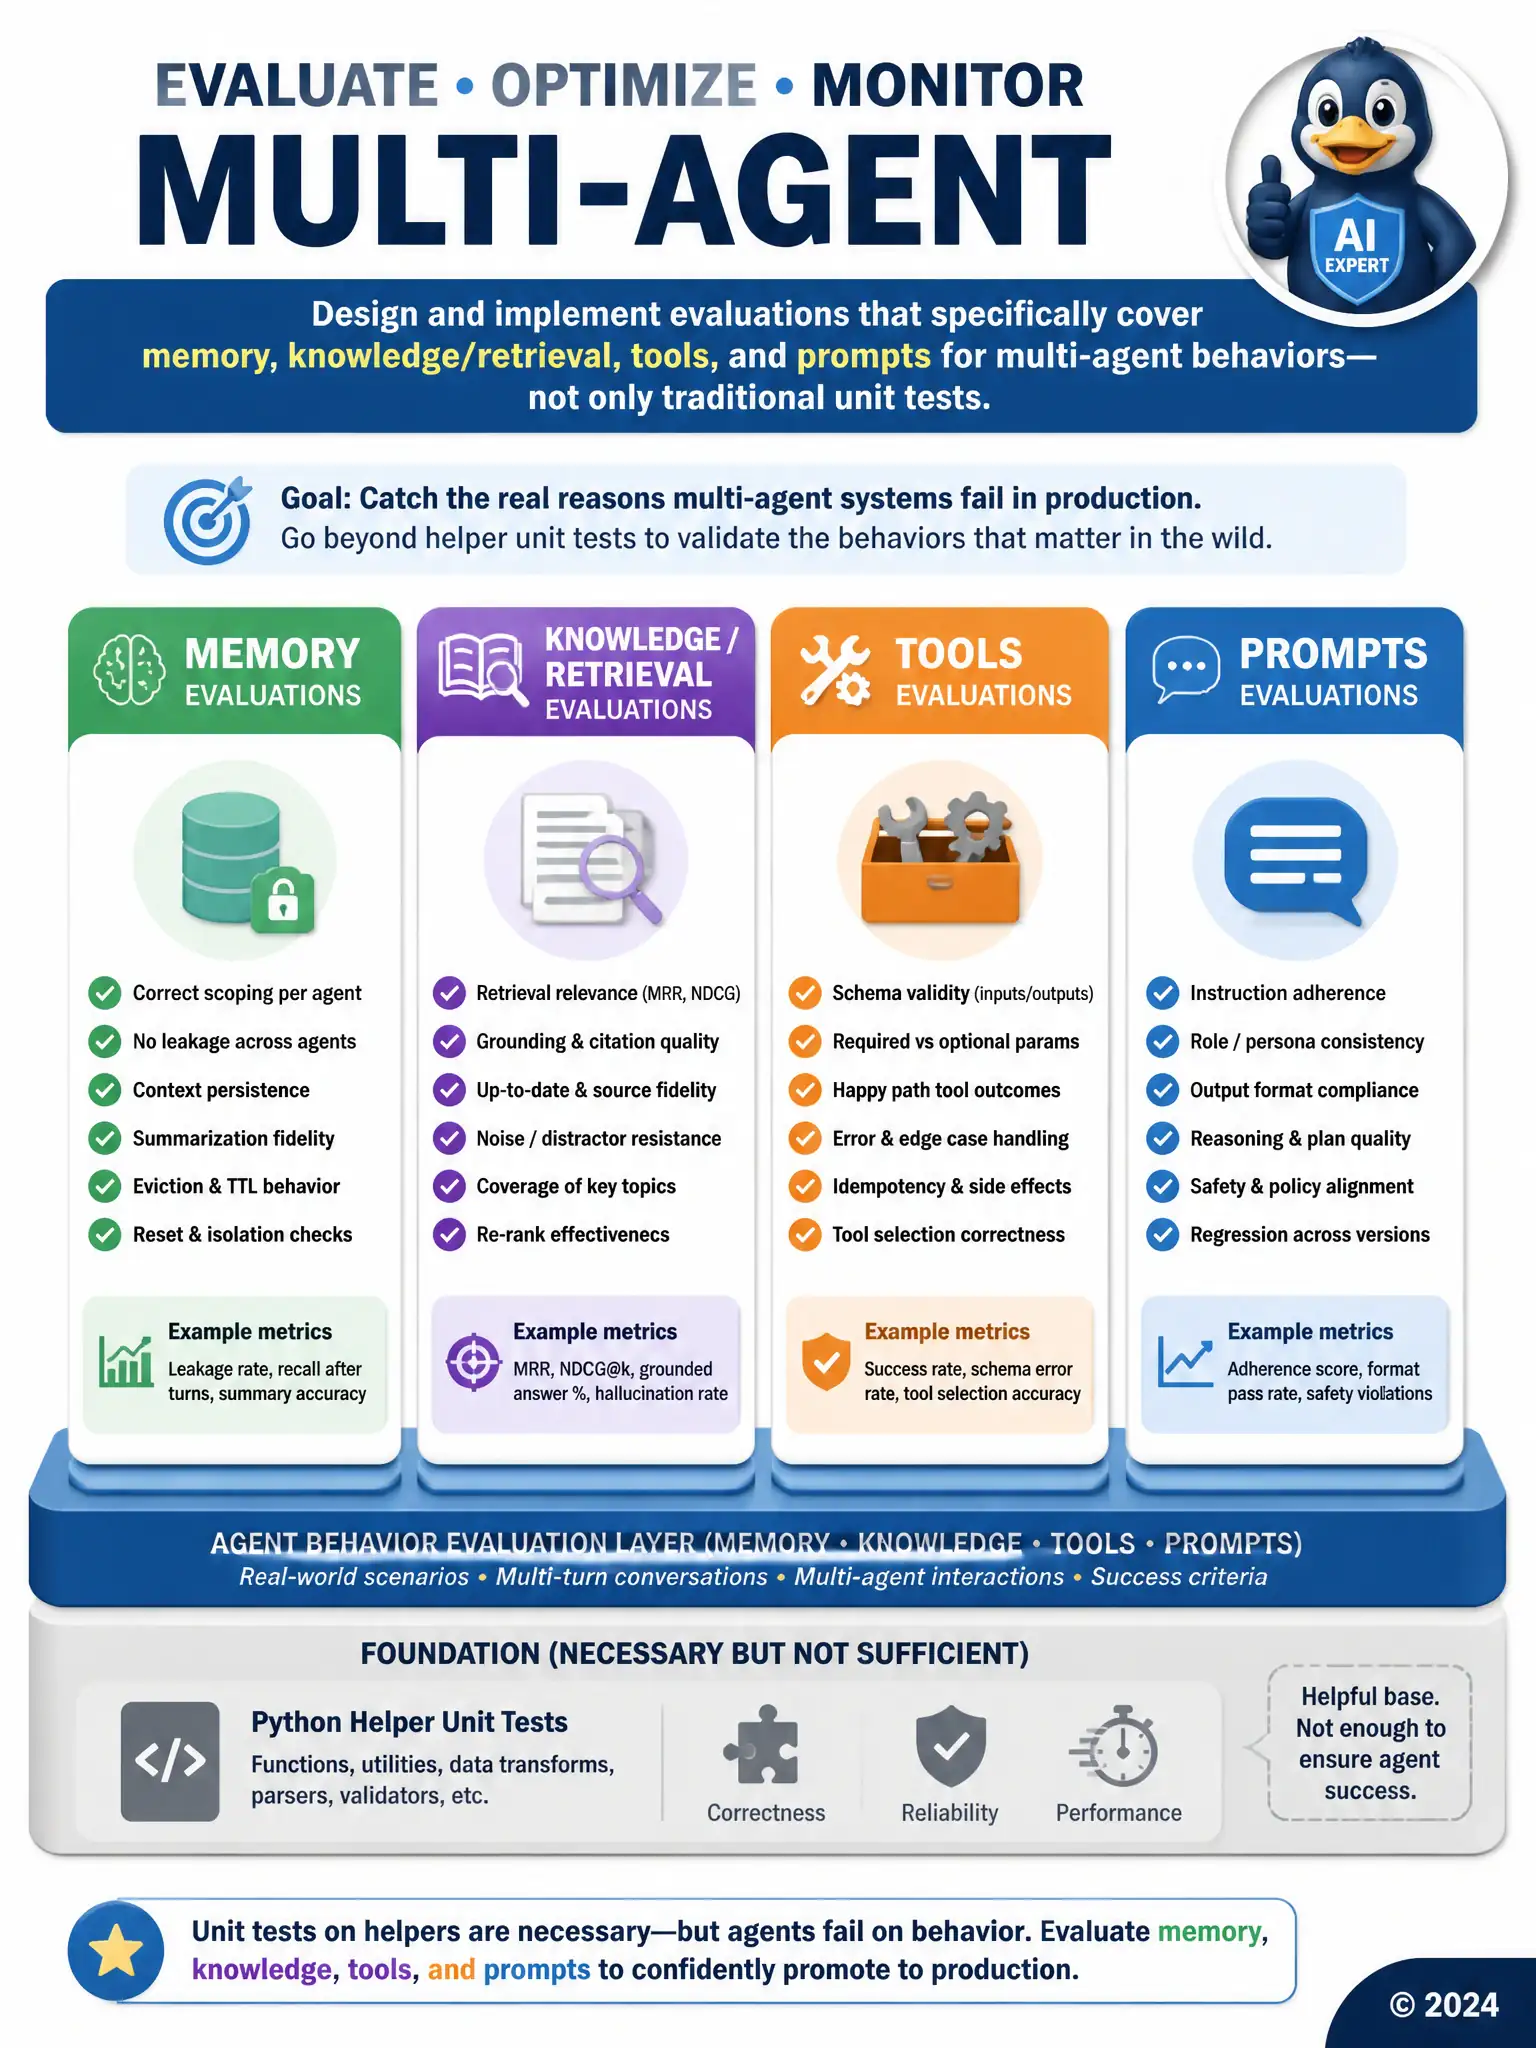
Unit tests on helpers are necessary but nowhere near sufficient for agents. You need evaluations aimed at memory scoping, knowledge/retrieval quality, tool schemas and outcomes, and prompts—the surfaces that actually break multi-agent systems. Management-plane pings and CSS checks do not cover agent behavior.
Full Explanation
Correct design: implement evaluations covering memory, knowledge/retrieval, tools, and prompts for multi-agent behaviors, not only unit tests. Traditional unit tests do not exercise retrieval precision, tool contracts, prompt regressions, or memory isolation/continuity. One Azure management-plane ping is wrong because control-plane liveness is not semantic agent evaluation. CSS color-contrast checks are wrong because UI contrast is orthogonal to agent reasoning quality. Assuming helper unit tests guarantee correct tool and memory behavior is wrong because they do not validate end-to-end multi-agent behaviors. Exam focus: expand eval scope to memory, knowledge, tools, prompts.