
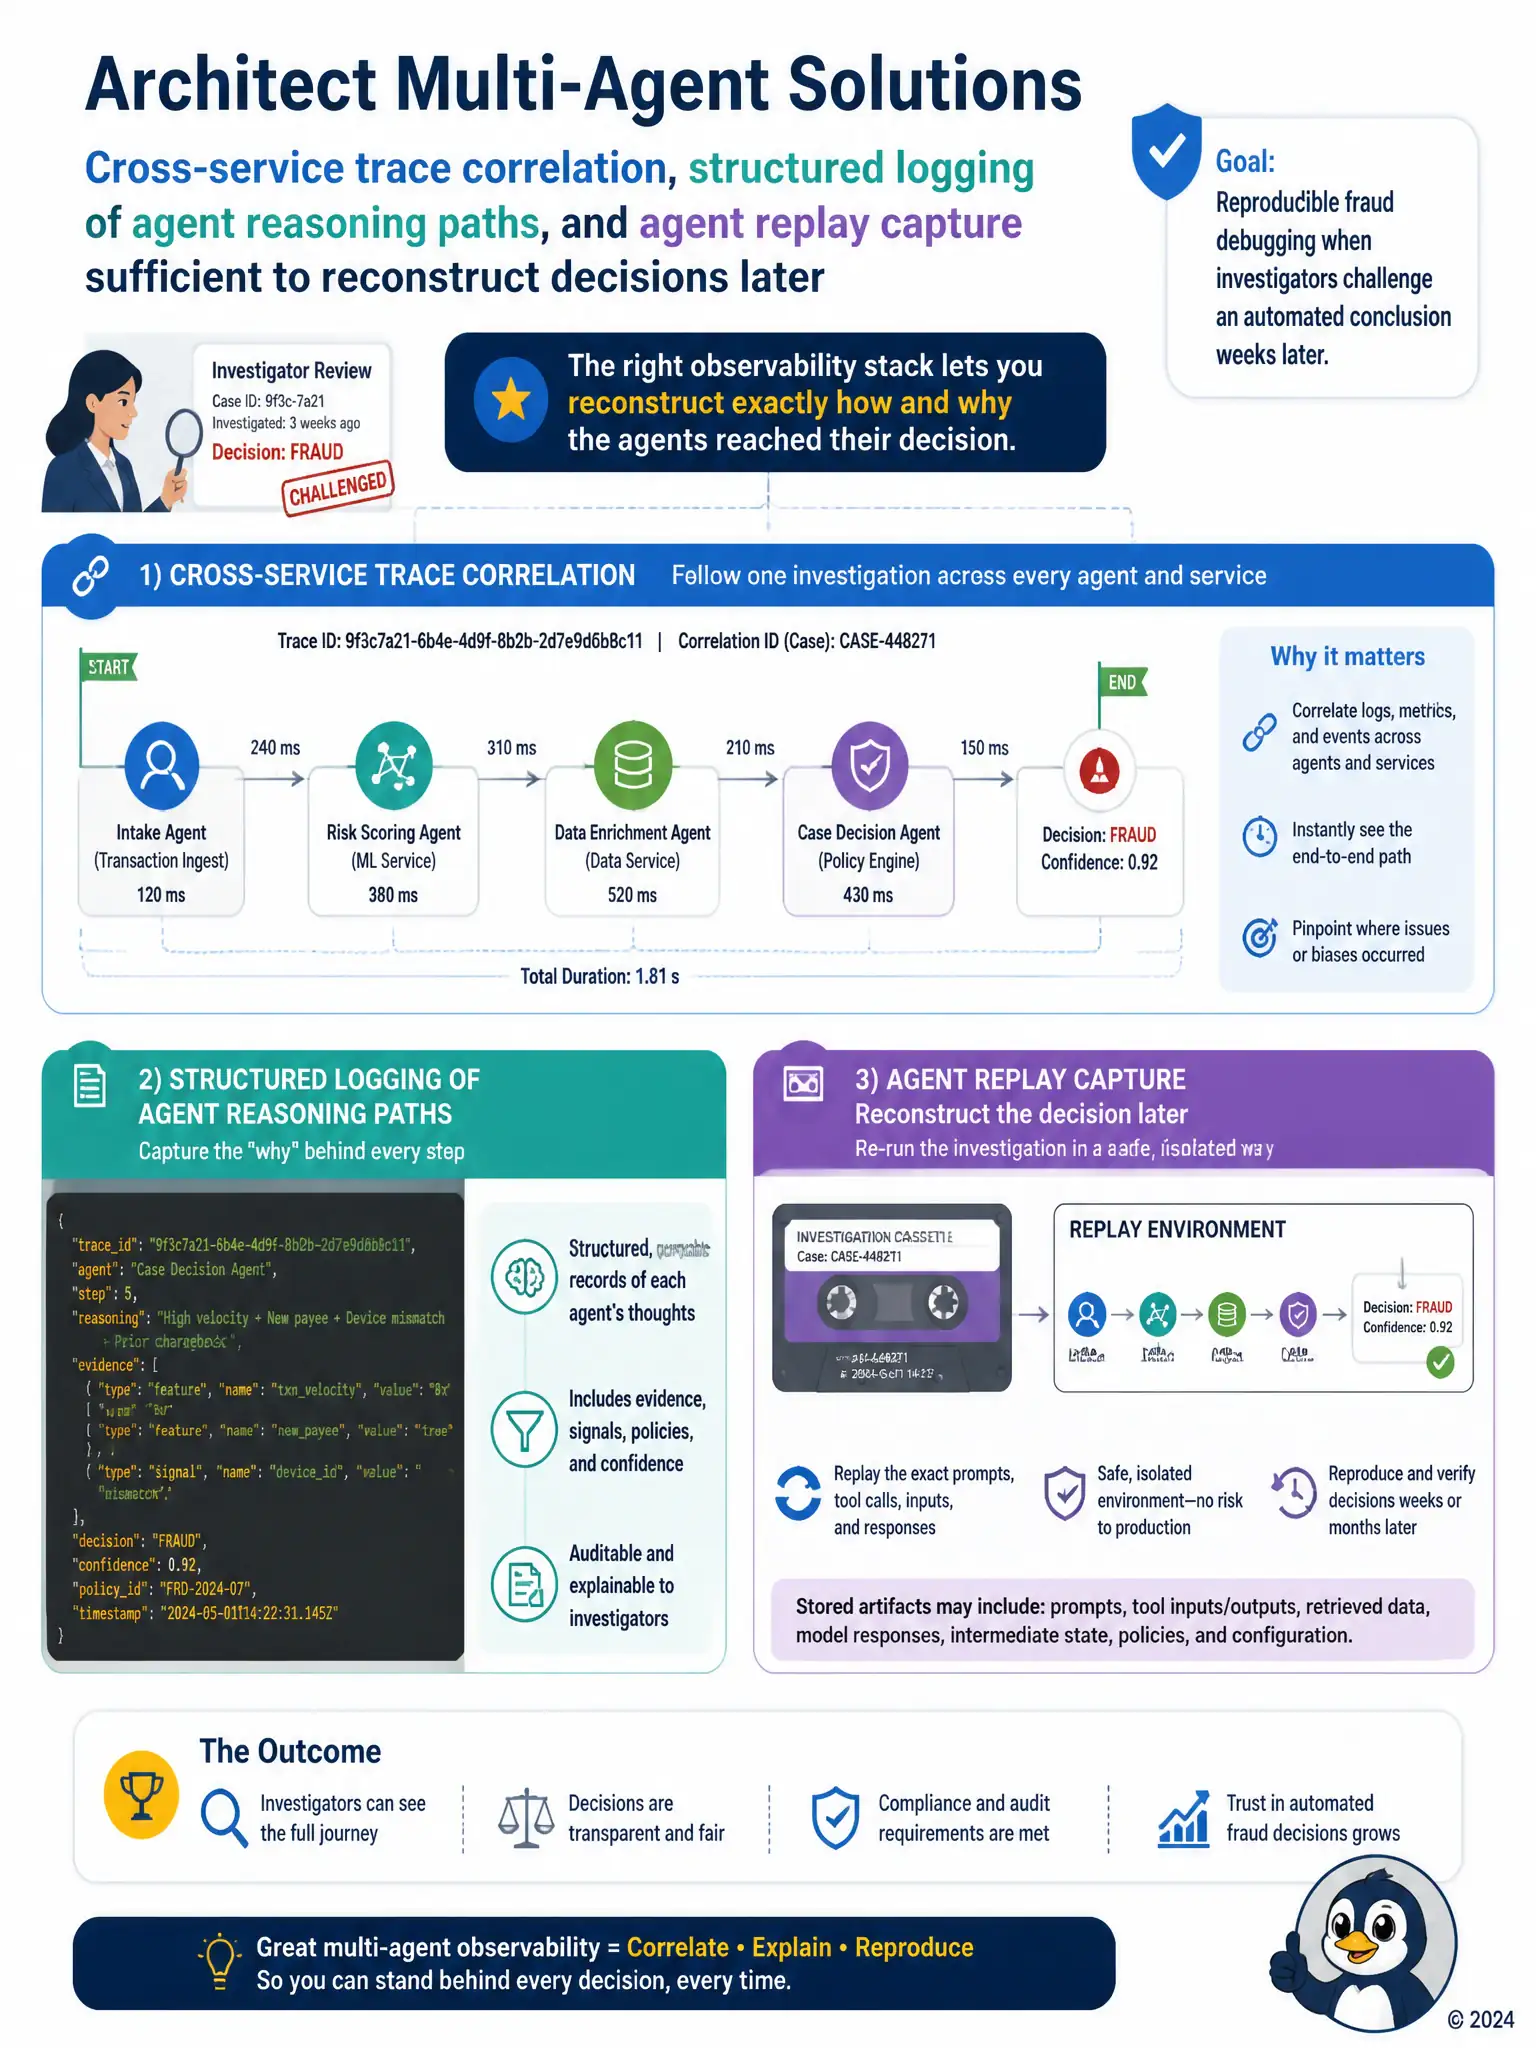
An architect is selecting observability components for a multi-agent fraud-investigation system that must support reproducible debugging when investigators challenge an automated conclusion weeks later. Which capability set should be specified?
Select an answer to reveal the explanation.
Short Explanation
You need cross-service trace correlation, structured logging of agent reasoning paths, and replay capture so you can reconstruct decisions weeks later. Lonely CPU charts, chat-thread memory, or immediate deletion of prompts and tool payloads won't support reproducible fraud debugging.
Full Explanation
The correct capability set is cross-service trace correlation, structured logging of agent reasoning paths, and agent replay capture sufficient to reconstruct decisions later. Architecture skills call for these observability components for reproducible debugging—essential when conclusions may be challenged later in fraud workflows.
The option specifying only CPU percentage on the orchestrator VM with no request context is incorrect because host CPU metrics lack per-investigation causal detail.
The option relying on manual memory of what on-call engineers recall from chat threads is incorrect because human recollection is incomplete and non-auditable for regulated investigations.
The option discarding all prompts and tool payloads immediately to maximize storage savings regardless of audit needs is incorrect because discarding prompts and tool payloads may undermine required reconstructability and audit needs; retention should follow policy, not zero-by-default when replay is required.