
A regulated insurer must approve any change to a multi-agent underwriting assistant before production. Automated Foundry evaluations score the suite green, but risk stakeholders require evidence that humans reviewed edge cases the metrics might miss. Which process design best satisfies both speed and governance?
Select an answer to reveal the explanation.
Short Explanation
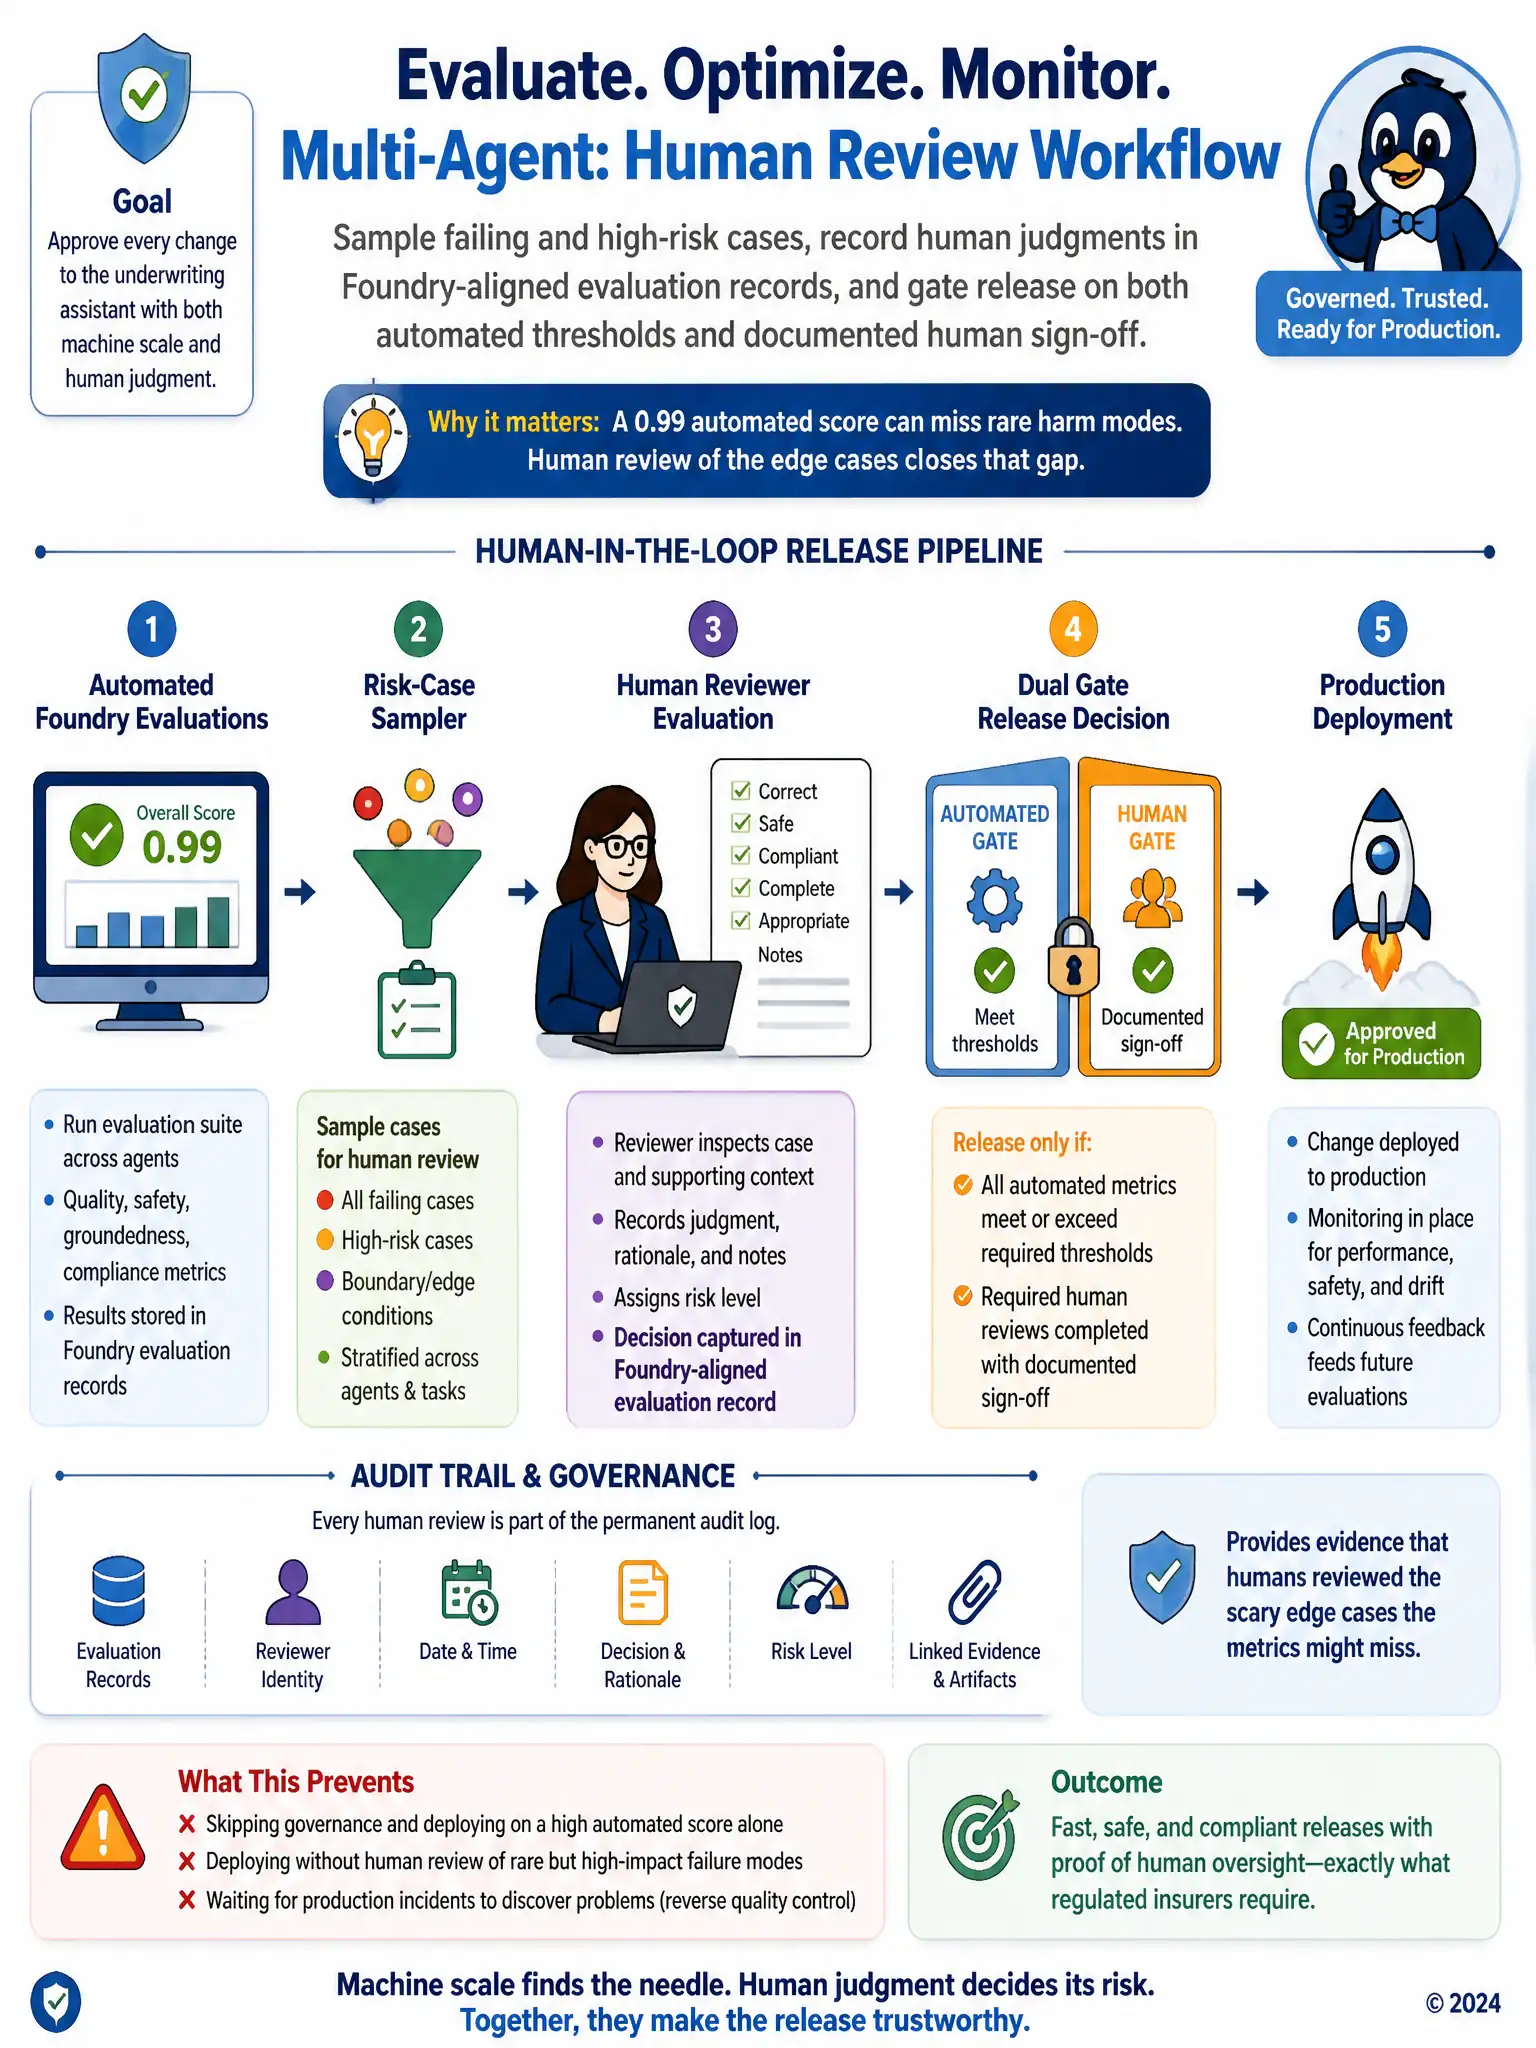
You need a human review workflow that samples failing and high-risk automated evaluation cases, records reviewer judgments in Foundry-aligned evaluation records, and gates release on both automated thresholds and documented human sign-off. High automated scores won't catch rare harm modes, and laptop deploys or post-incident feedback skip governance.
Full Explanation
The workflow that samples failing and high-risk automated evaluation cases, records reviewer judgments in Foundry-aligned evaluation records, and gates release on both automated thresholds and documented human sign-off is correct. AI-500 skills call for designing human review processes to evaluate solutions in Foundry alongside automated evaluations. Sampling high-risk and failing cases, recording human judgments, and dual-gating release balances velocity with governance for regulated domains. Skipping human review when the automated composite score exceeds 0.99 is incorrect because high composite scores do not guarantee coverage of rare, high-impact edge cases that regulators and risk teams care about. Allowing developers to promote agents directly from laptops after local manual chat tests is incorrect because uncontrolled local promotion bypasses evaluation evidence, audit trails, and separation of duties expected in regulated underwriting systems. Publishing agents first and collecting human feedback only from production customers after incidents is incorrect because post-incident customer feedback is lagging and externalizes risk; governance requires pre-production review for underwriting assistants.