
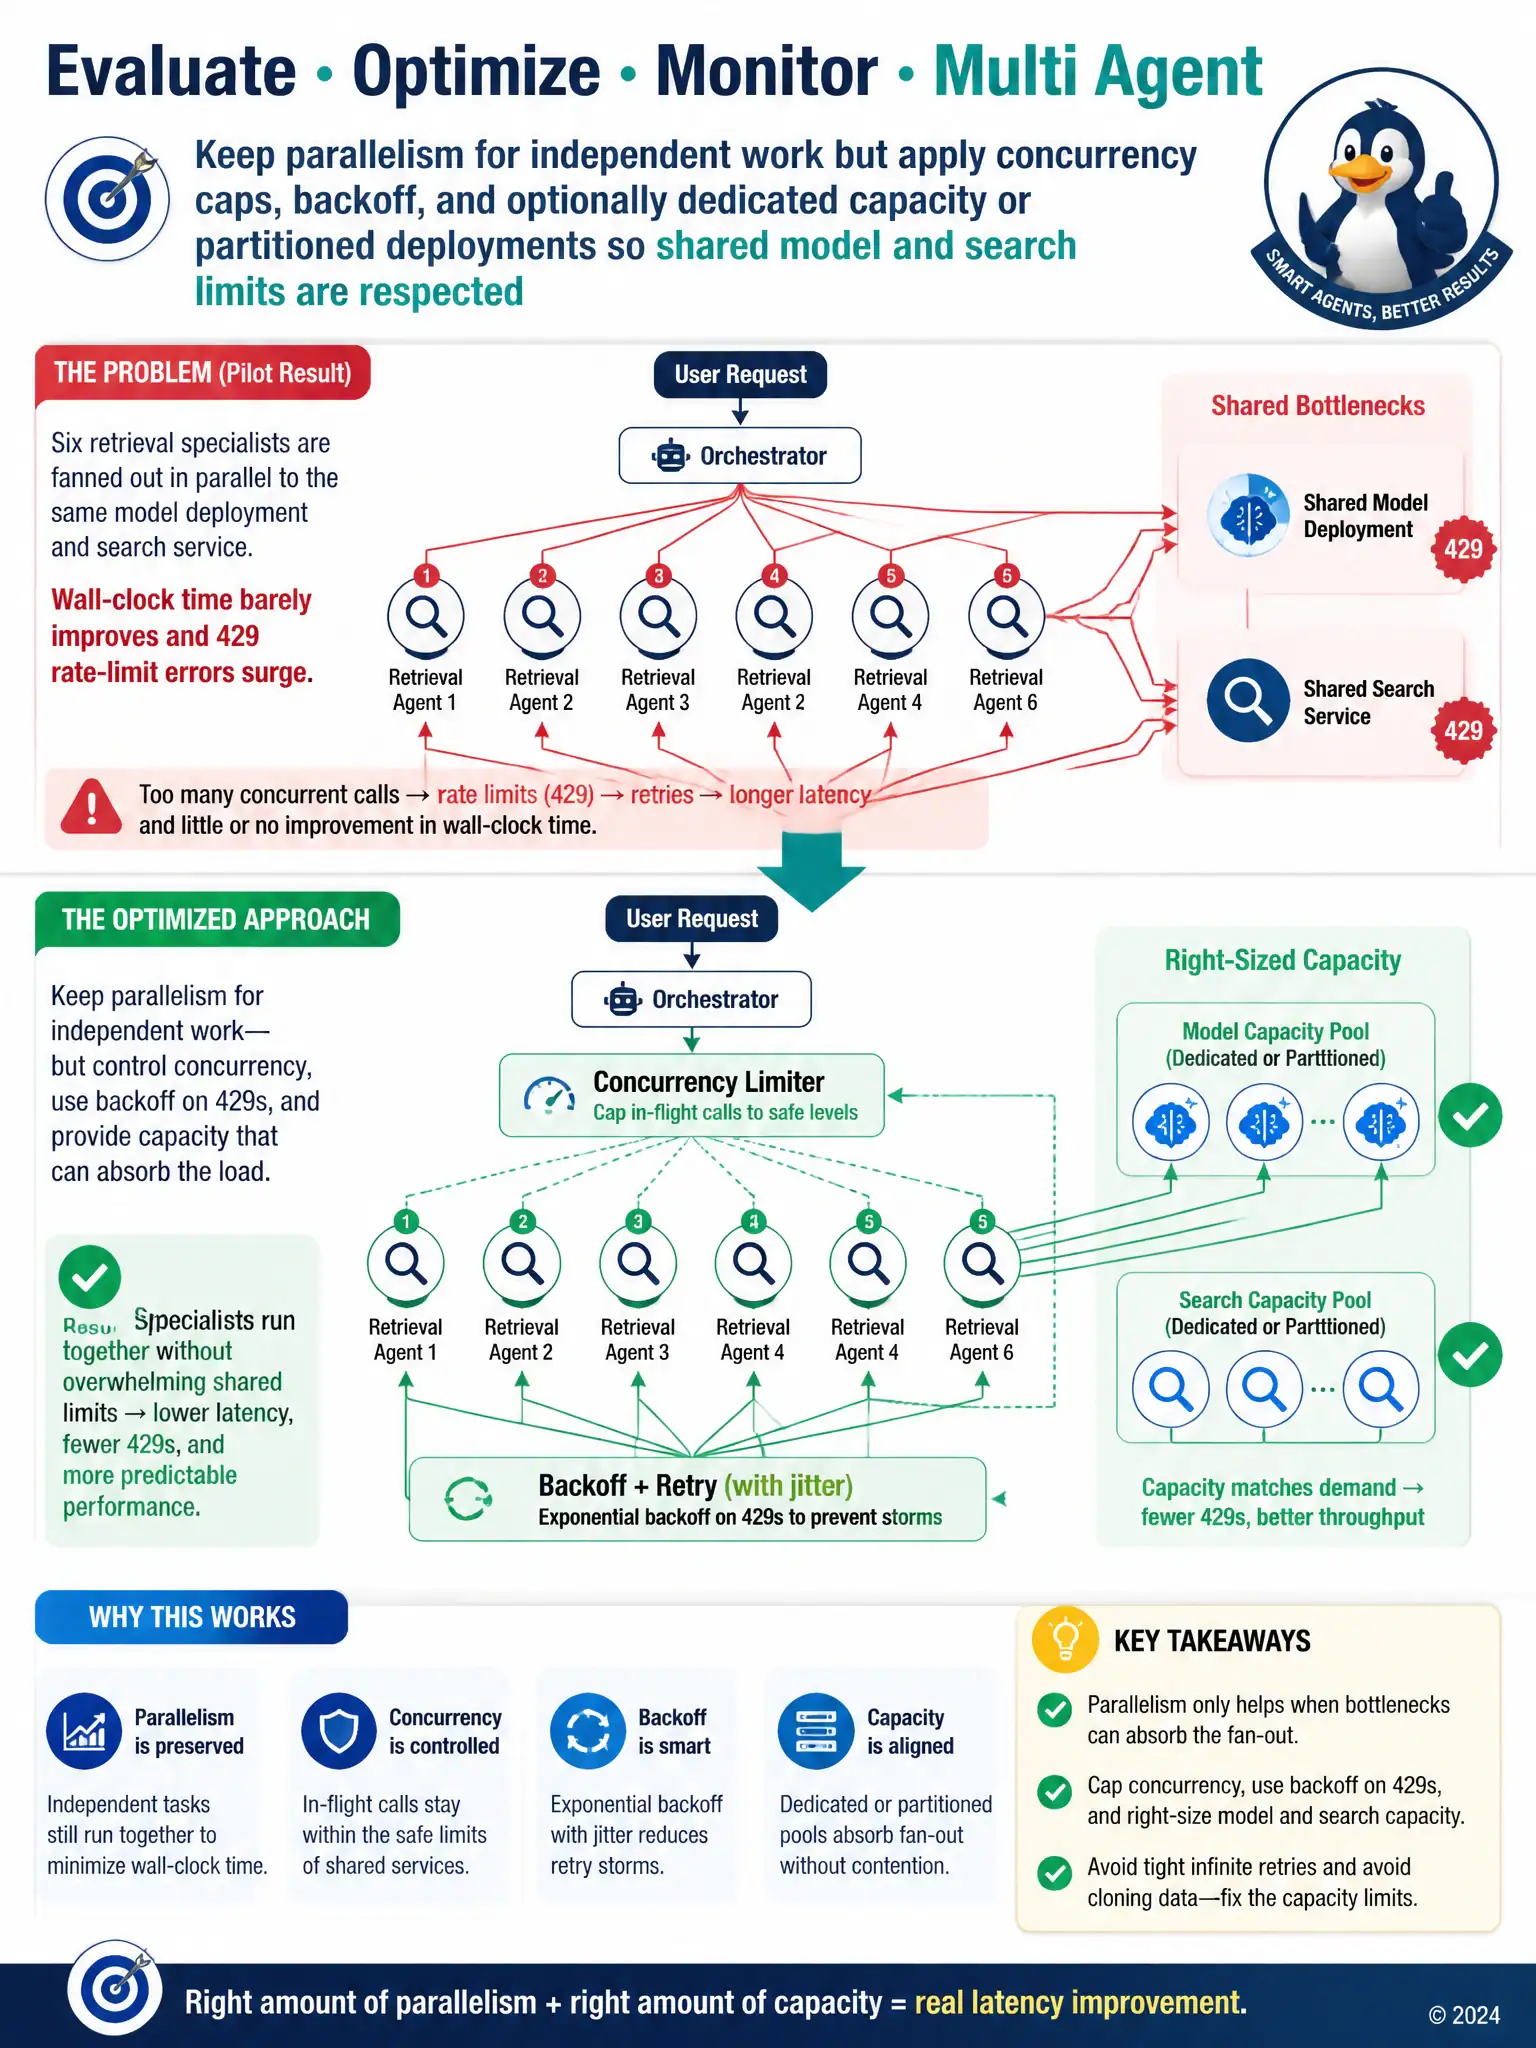
An architect plans to cut median latency of a six-agent research workflow by running independent retrieval specialists in parallel. During a pilot, total wall-clock time barely improves and 429 rate-limit errors surge against a shared Azure OpenAI deployment and a shared search service. What should the team do to optimize task duration realistically?
Select an answer to reveal the explanation.
Short Explanation
Keep parallelism for independent work, but cap concurrency, back off on 429s, and use dedicated or partitioned capacity when needed. That way the specialists run together without stampeding shared model and search limits. Tight retries or giving up on parallelism won't fix the bottleneck.
Full Explanation
Keeping parallelism for independent work while applying concurrency caps, backoff, and optionally dedicated capacity or partitioned deployments is correct. Optimizing multi-agent task duration includes parallelism and rate-limit awareness. Independent specialists can run concurrently, but shared Azure OpenAI and search quotas require concurrency controls, exponential backoff, and sometimes capacity isolation. That combination addresses the pilot's flat latency and 429 spike without abandoning parallelism.
Ignoring rate limits and retrying immediately in a tight loop until every call succeeds is incorrect because aggressive immediate retries amplify rate-limit storms and can lengthen total time while harming other workloads on the same deployment.
Serializing all agents again permanently because parallel orchestration is never beneficial is incorrect because parallel orchestration is often beneficial for independent subtasks; the failure mode here is resource contention, not an inherent flaw of parallelism.
Giving every parallel agent its own full copy of the entire enterprise data lake on local disk is incorrect because wholesale local copies of enterprise data are operationally unrealistic, create security and freshness problems, and do not resolve model inference rate limits.