
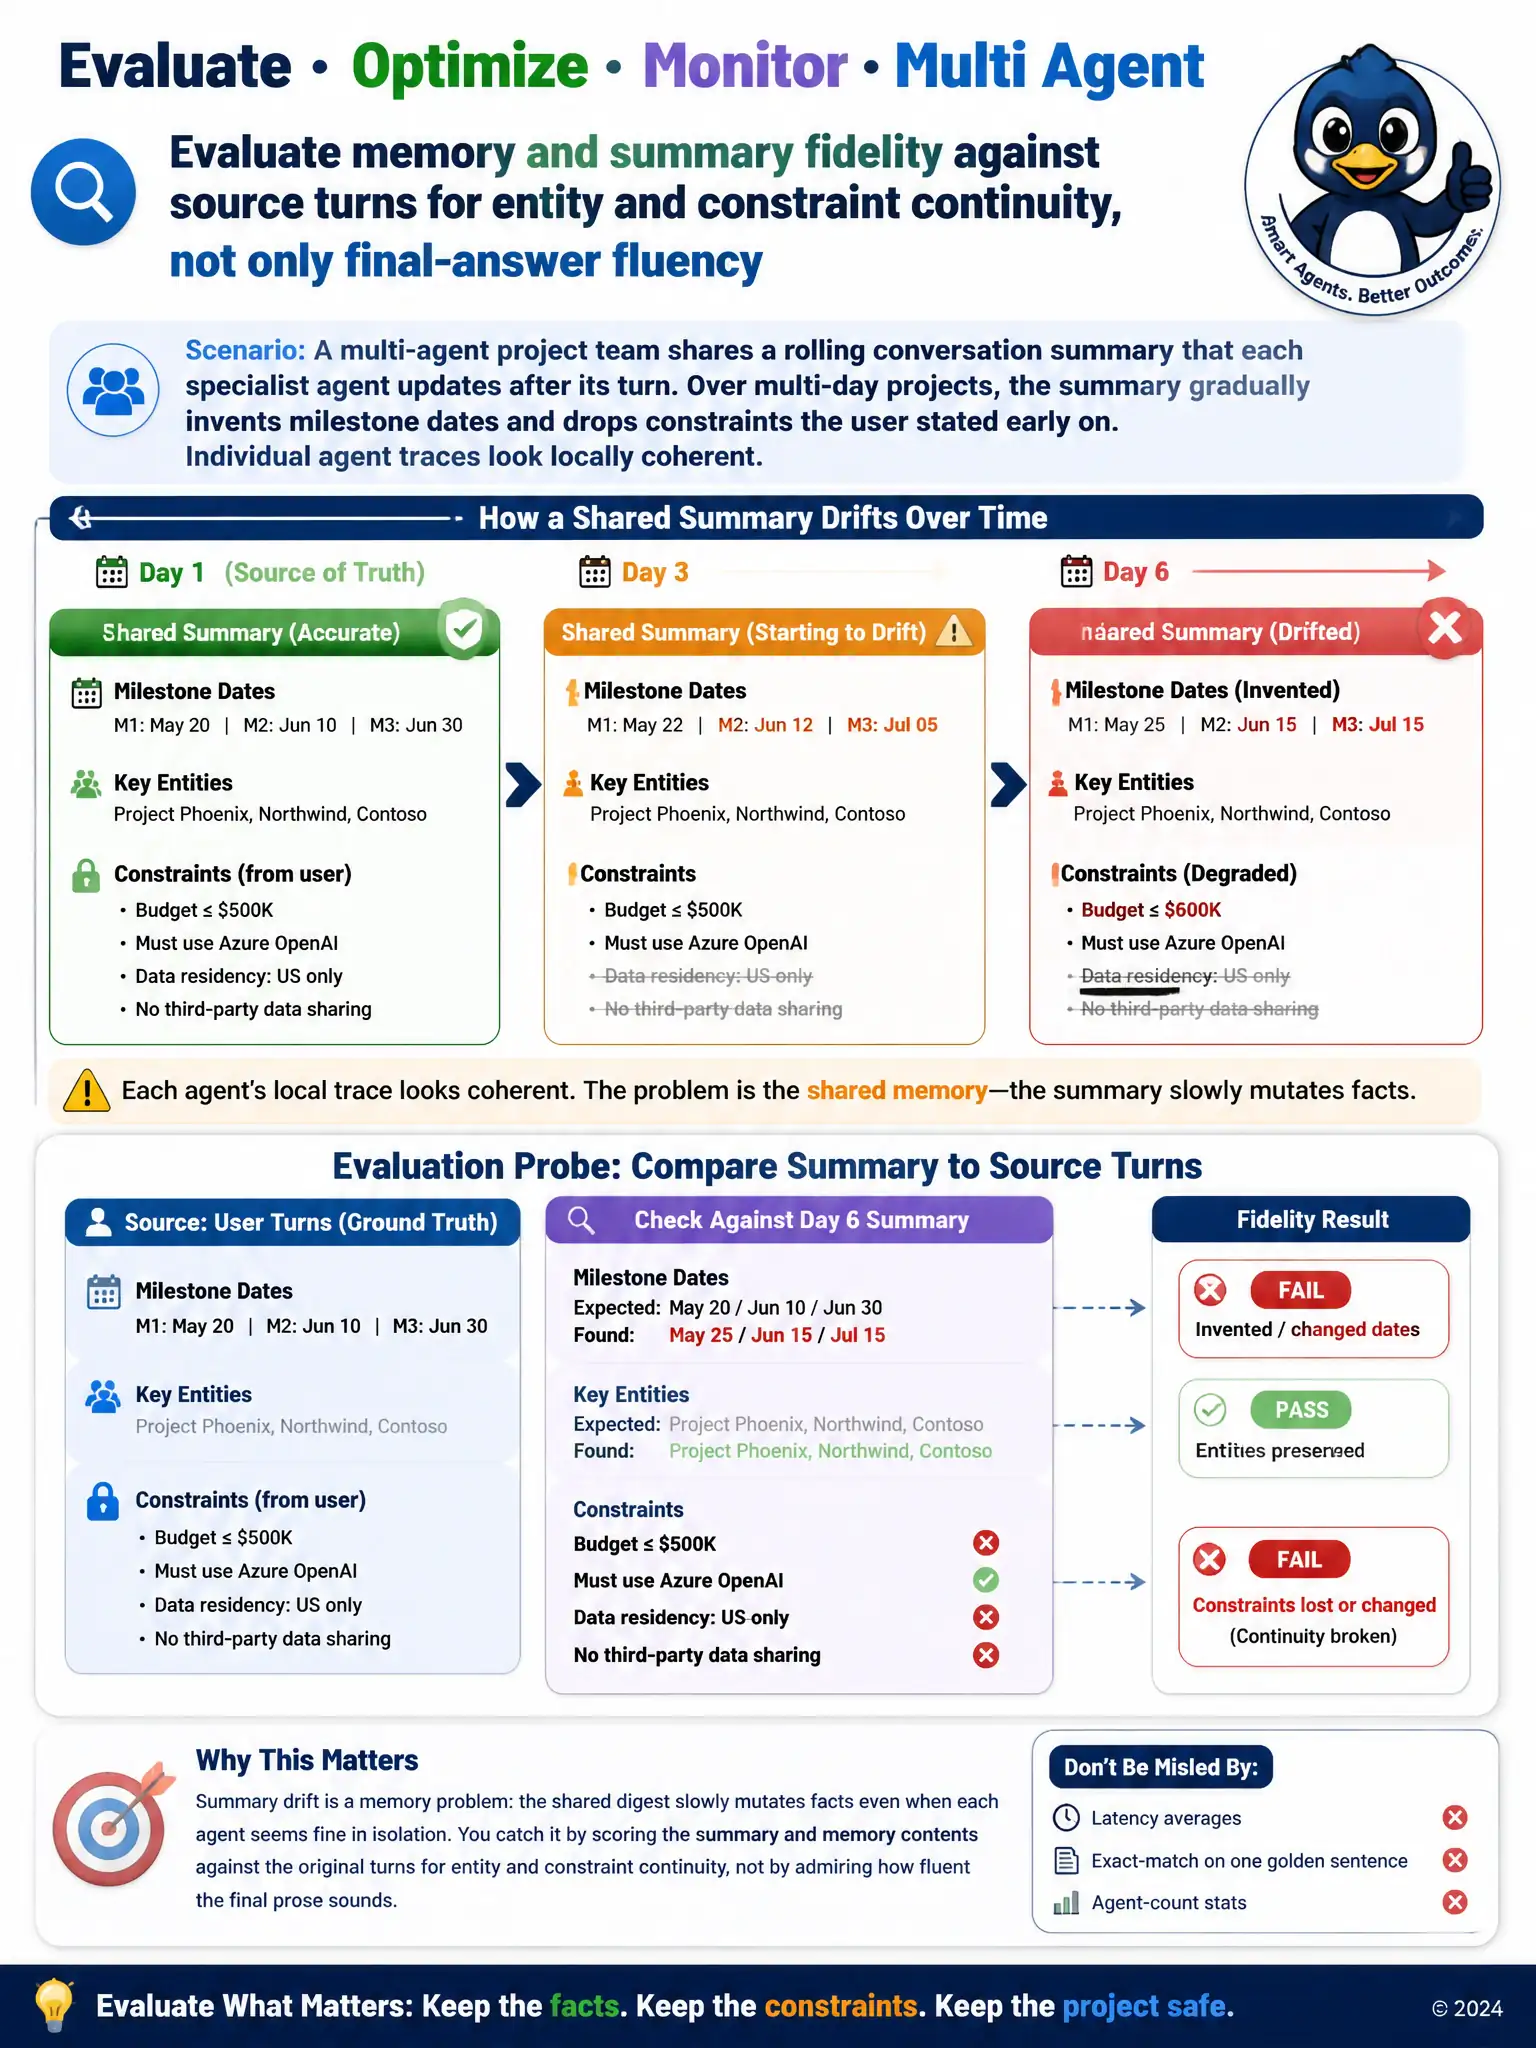
A multi-agent project team shares a rolling conversation summary that each specialist agent updates after its turn. Over multi-day projects, the summary gradually invents milestone dates and drops constraints the user stated early on. Individual agent traces look locally coherent. Which evaluation focus best detects this class of failure?
Select an answer to reveal the explanation.
Short Explanation
You're dealing with summary drift, so you need to score the rolling summary and memory against the original turns for entity and constraint continuity. Fluent final answers can still rest on a quietly corrupted shared digest. Latency averages, one-sentence exact-match scoring, and agent-count stats won't catch that.
Full Explanation
The best evaluation focus is evaluating memory and summary fidelity against source turns for entity and constraint continuity, not only final-answer fluency. Multi-agent evaluation must cover memory and knowledge pathways. When specialists rewrite a shared rolling summary, gradual summary drift and lost constraints are common. Dedicated checks for entity continuity and constraint retention against source turns surface failures that final-answer fluency metrics miss. The latency-only option is incorrect because latency characterizes performance, not whether shared memory still reflects user-stated facts. The exact-match-only option is incorrect because exact-match against one reference sentence fails for open-ended multi-day work products and does not inspect intermediate memory state where drift accumulates. The agent-count option is incorrect because invocation counts describe orchestration shape, not factual integrity of shared summaries.