
Contoso runs three business units on a shared multi-agent Foundry platform. Finance complains that monthly Azure OpenAI spend is opaque: one unit's research swarm appears to consume most tokens, but chargebacks are still split evenly. Platform engineering must improve cost accountability without redesigning every agent. What should they implement first?
Select an answer to reveal the explanation.
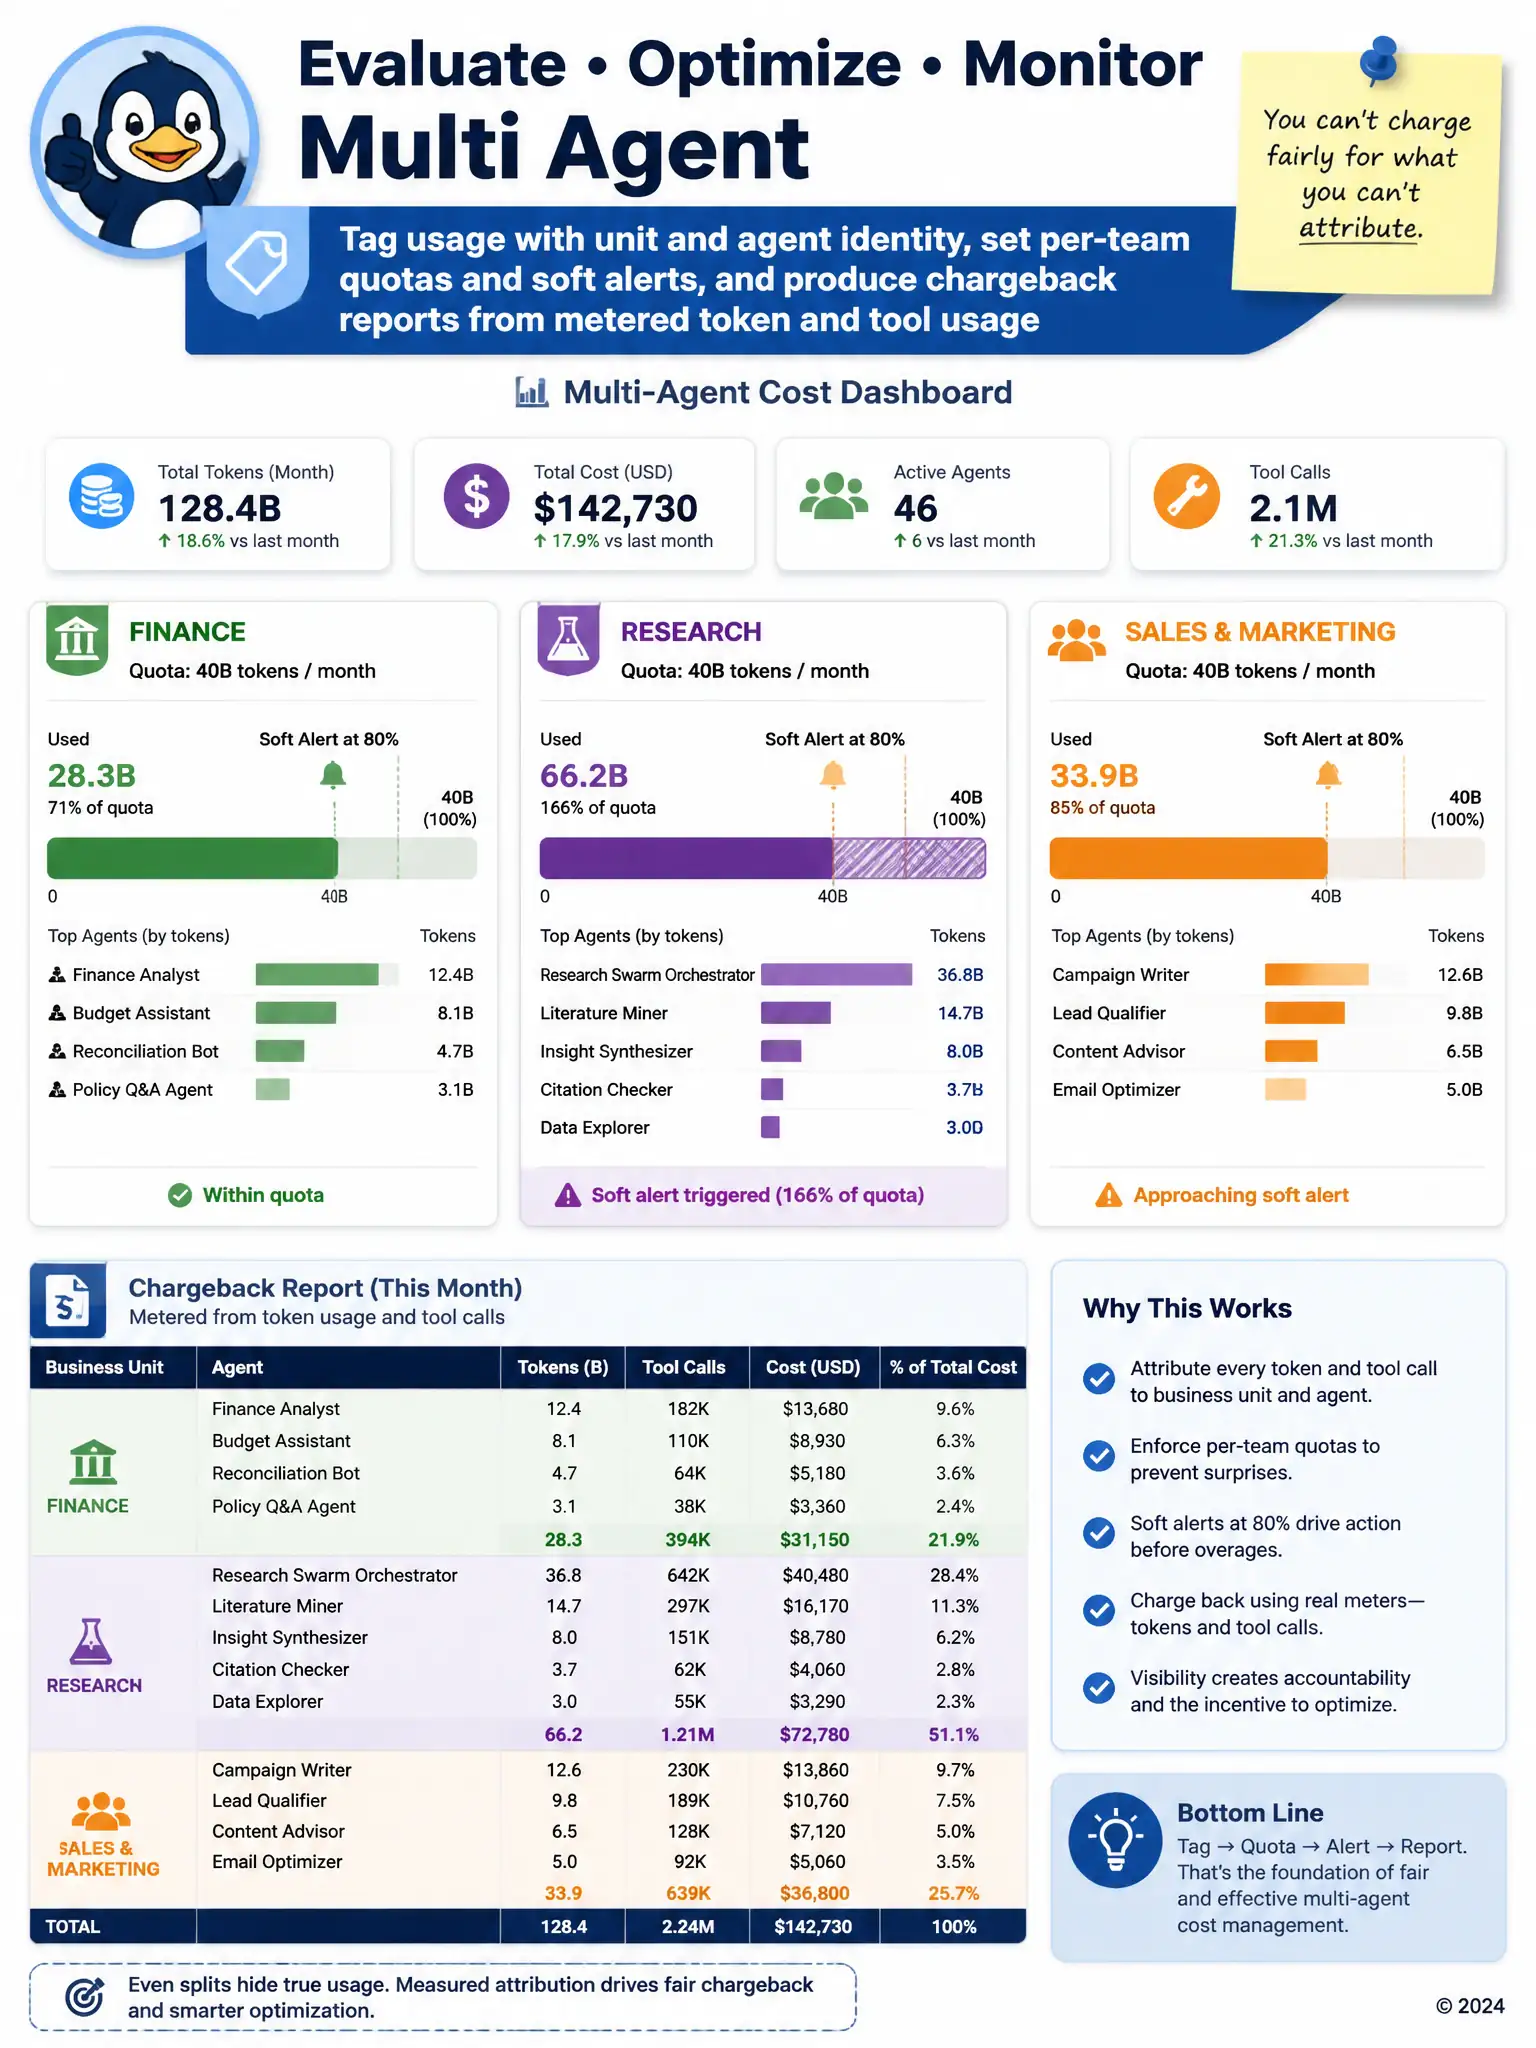
Short Explanation
You can't charge fairly for what you can't attribute. Tag traffic with business unit and agent identity, apply per-team quotas with soft alerts, and report from real token and tool meters. That's the foundation of multi-agent cost management.
Full Explanation
The correct approach is to tag usage with unit and agent identity, set per-team quotas and soft alerts, and produce chargeback reports from metered token and tool usage. Cost management for multi-agent solutions requires usage attribution through tags or dimensions for team and agent, quotas or allocations, alerting before hard failures, and chargeback reporting driven by metered token and tool consumption. That directly answers finance's opacity problem without a full rewrite of agent logic. Even splits hide the research swarm's consumption and remove any incentive to optimize.
Disabling tracing and logging is incorrect because telemetry overhead is typically minor compared with model and tool spend, and disabling tracing removes the observability needed to investigate cost drivers. It saves almost nothing relative to model tokens and blinds operations.
Forcing every agent to use the same small model regardless of task complexity is incorrect because mandating a single small model is a blunt quality and cost tradeoff, not an accountability mechanism. It can degrade critical workloads while still leaving spend unattributed if tagging is missing.
Deleting historical conversation state weekly is incorrect because memory storage cost is separate from inference token chargebacks, and weekly deletion may violate product or compliance needs without explaining which unit burned tokens. It is a data lifecycle choice, not a usage attribution fix.