
A product team runs a multi-agent research-and-draft pipeline in Microsoft Foundry. They want a continuous improvement loop that scores draft quality on faithfulness and structure at scale, then feeds weak cases into prompt and tool refinements. Human labels exist only for a small golden set. Which approach best meets these goals?
Select an answer to reveal the explanation.
Short Explanation
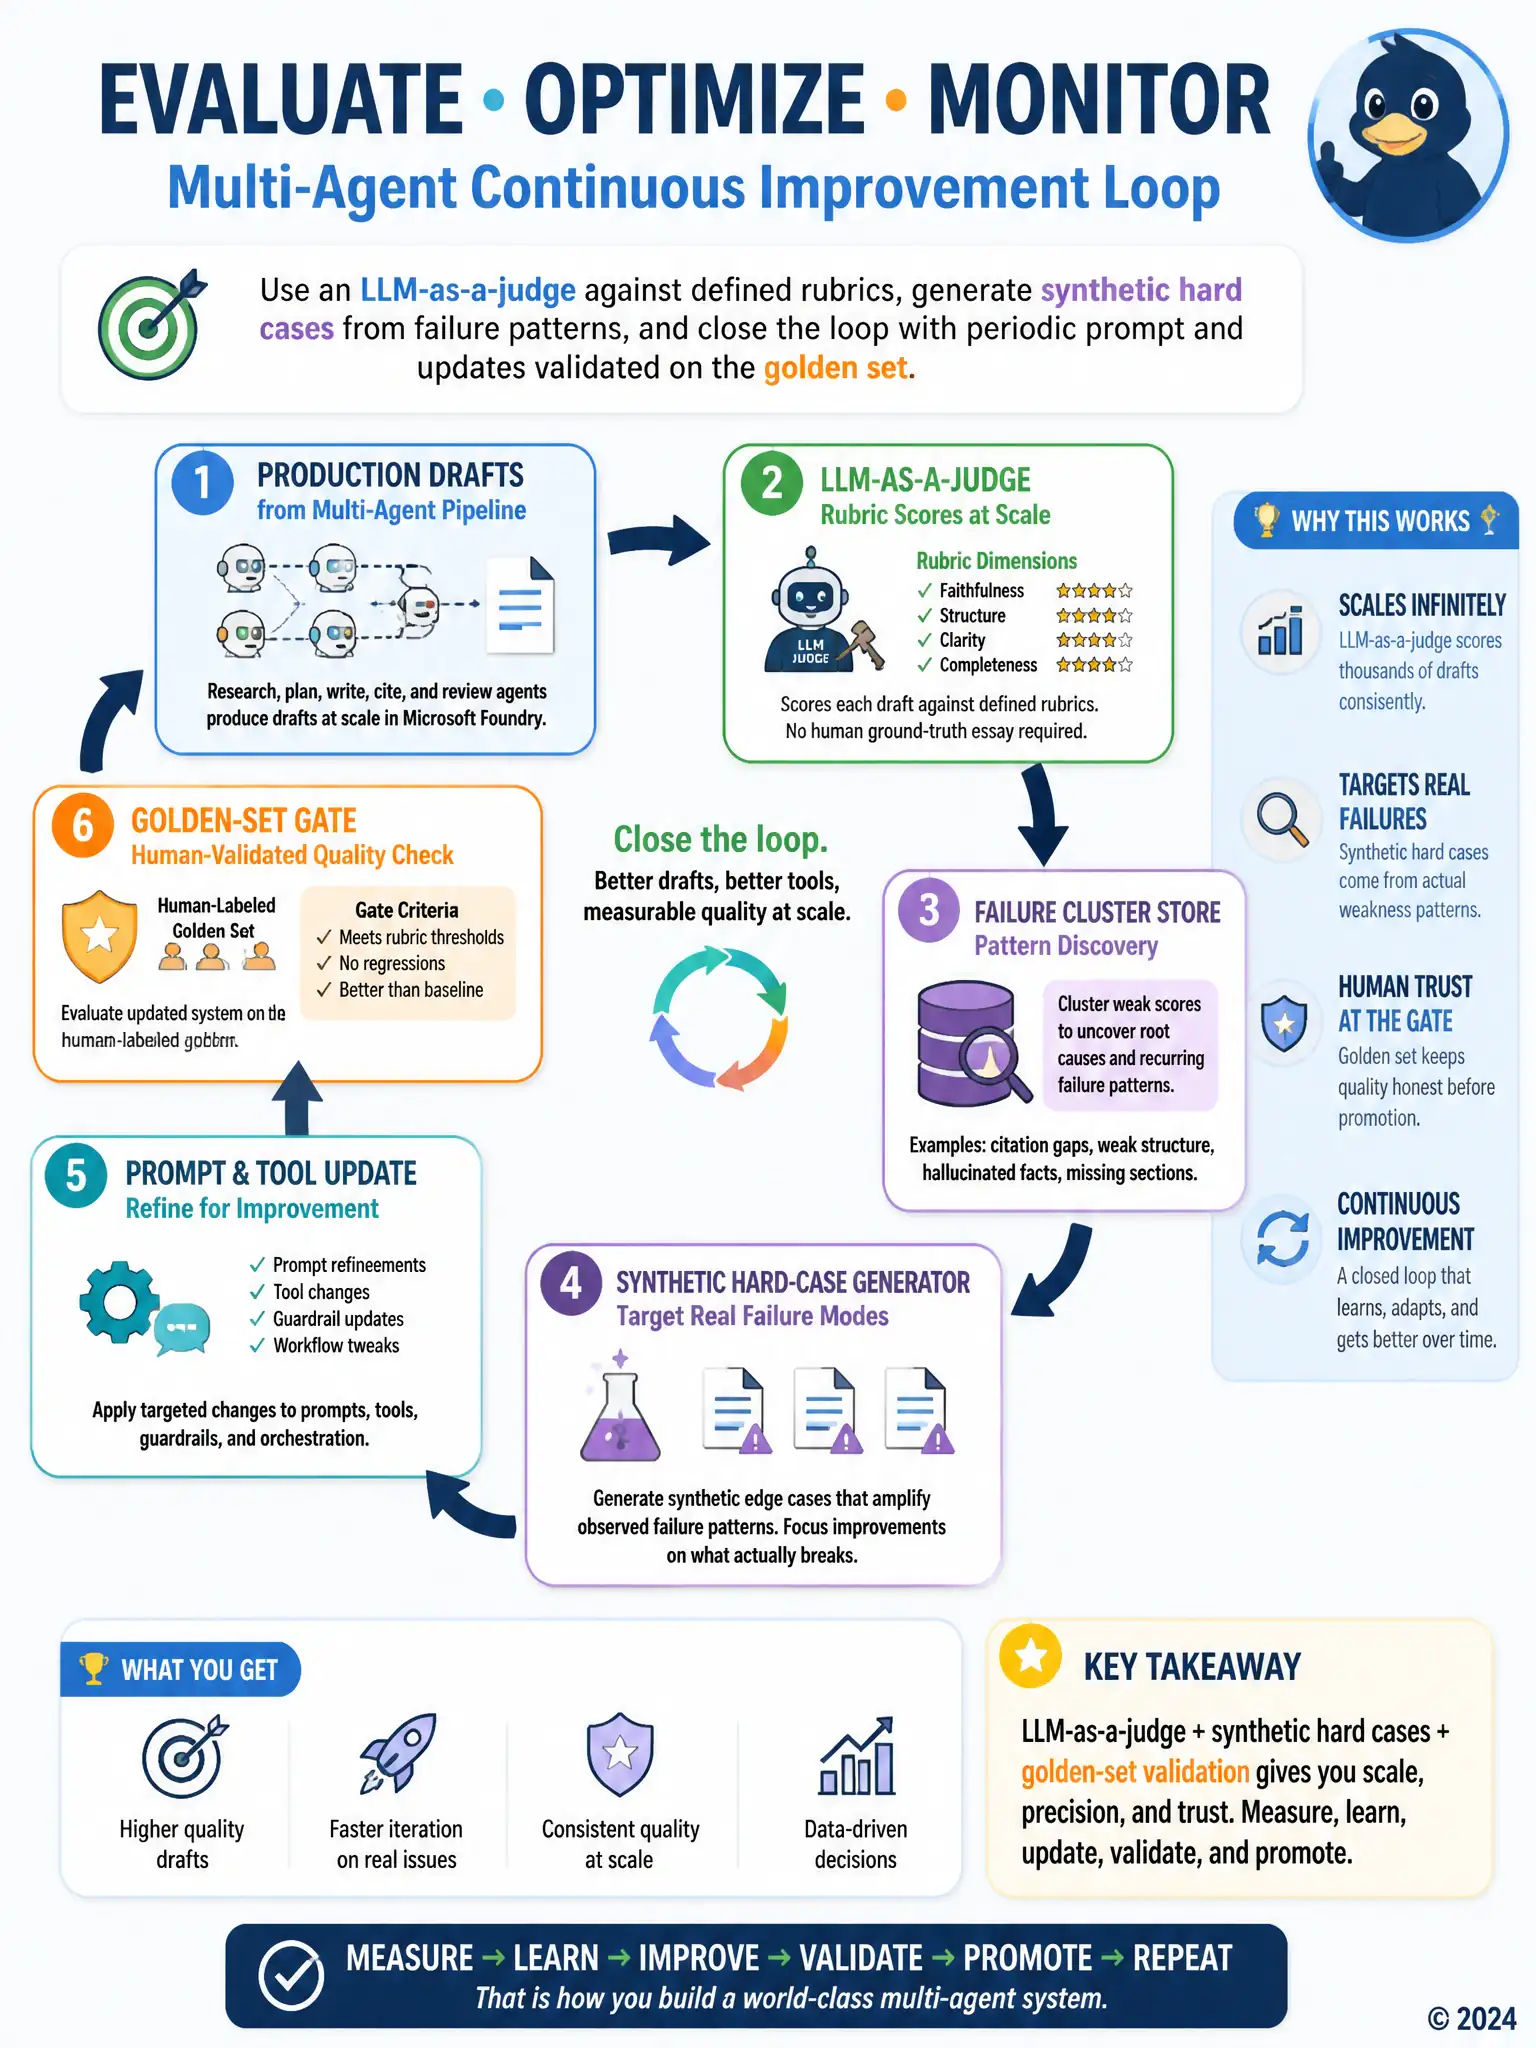
You need scale plus a feedback loop, and that's exactly what the LLM-as-a-judge framework with rubrics, synthetic hard cases, and golden-set validation gives you. The judge scores faithfulness and structure across many drafts, weak-score patterns seed targeted edge cases, and the small golden set stays the human-trusted gate before you promote changes. The monthly review, biggest-model swap, and tool-disabling approaches don't give you continuous, production-relevant improvement.
Full Explanation
The approach that uses an LLM-as-a-judge framework against defined rubrics, generates synthetic hard cases from failure patterns, and closes the loop with periodic prompt and tool updates validated on the golden set is correct. Continuous improvement for multi-agent systems typically combines automated evaluation (LLM-as-a-judge against rubrics for attributes such as faithfulness and structure), synthetic data generation from observed failure modes, and controlled promotion against a small human-labeled golden set. That design scales beyond scarce human labels while still anchoring releases to trusted ground truth. The approach that relies solely on monthly human review of ten random production transcripts with no automated scoring is incorrect because a monthly sample of ten transcripts cannot provide timely or statistically meaningful coverage for production multi-agent quality, and it provides no systematic mechanism to generate targeted hard cases or validate prompt/tool changes. The approach that replaces all specialist models with the largest available foundation model so scoring becomes unnecessary is incorrect because model size is not a substitute for evaluation. Larger models can still produce unfaithful or poorly structured drafts, and without measurement the team cannot detect regressions or know whether improvements worked. The approach that disables tool calling so evaluation only measures pure language generation quality is incorrect because the production system uses tools; evaluating pure generation alone ignores tool-result faithfulness and tool-error paths that dominate multi-agent quality risk. Removing tools also invalidates the evaluation relative to the deployed architecture.