
You need a repeatable way for domain experts to score multi-agent runs in Microsoft Foundry before promoting a new orchestrator version. Automated metrics exist but miss subtle policy tone issues. What should you design?
Select an answer to reveal the explanation.
Short Explanation
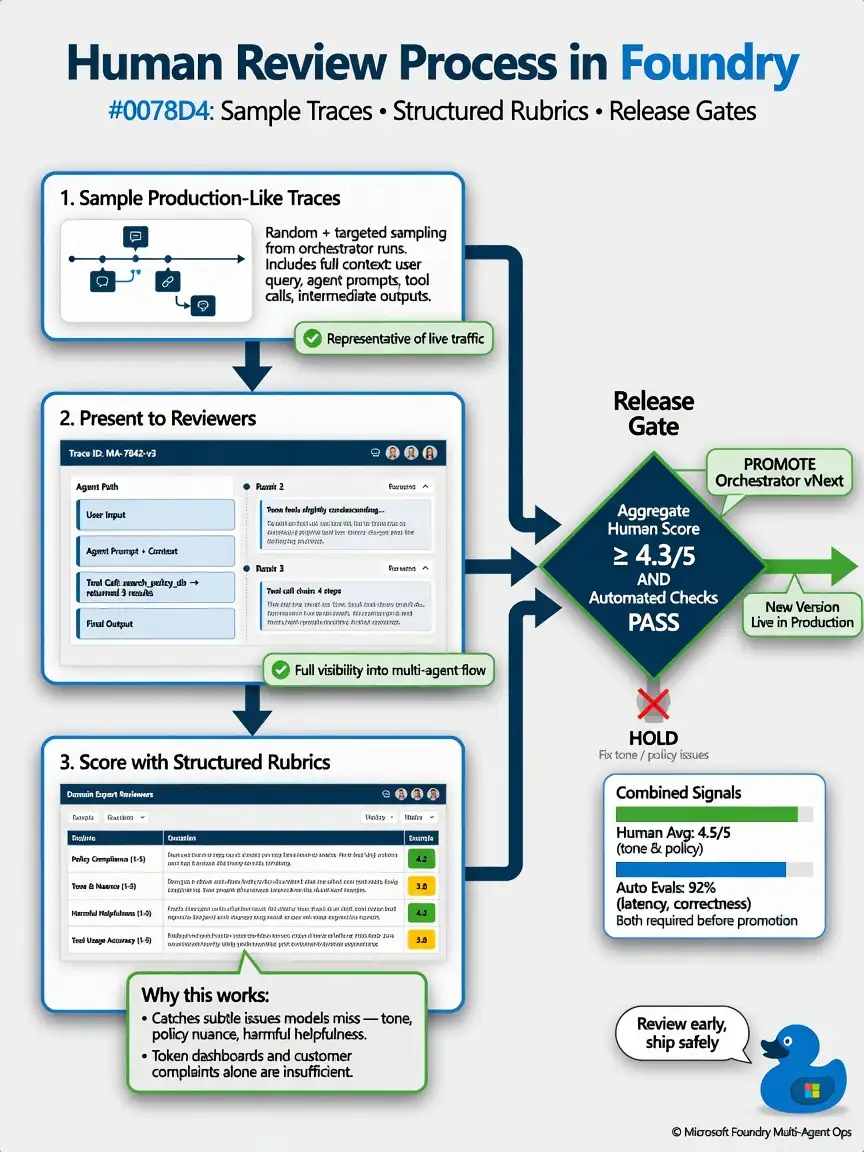
You want a human review loop in Foundry that samples production-like traces, shows reviewers the full agent path, scores it with rubrics, and gates promotion on human plus automated checks. Token dashboards alone aren't quality, complaints are too late, and disabling tracing blinds you.
Full Explanation
Correct design: implement a human review process in Foundry that samples production-like traces, shows reviewers agent inputs/outputs and tool calls, scores them with structured rubrics, and gates release on aggregate human scores plus automated checks. This catches tone and policy issues metrics miss. Token-count dashboards are efficiency metrics, not quality or policy evaluation. Promoting every change to production and relying only on customer complaints is slow, customer-harming, and uncontrolled. Disabling tracing to reduce cost blinds both human review and automated diagnosis. Exam tip: human review + rubrics + automated checks = promotion gate in Foundry.