
Three agents share a knowledge base: policy lookup, exception handling, and customer explanation. Retrieval often returns irrelevant partial tables, so the exception agent applies the wrong rule. How should you improve the multi-agent RAG architecture?
Select an answer to reveal the explanation.
Short Explanation
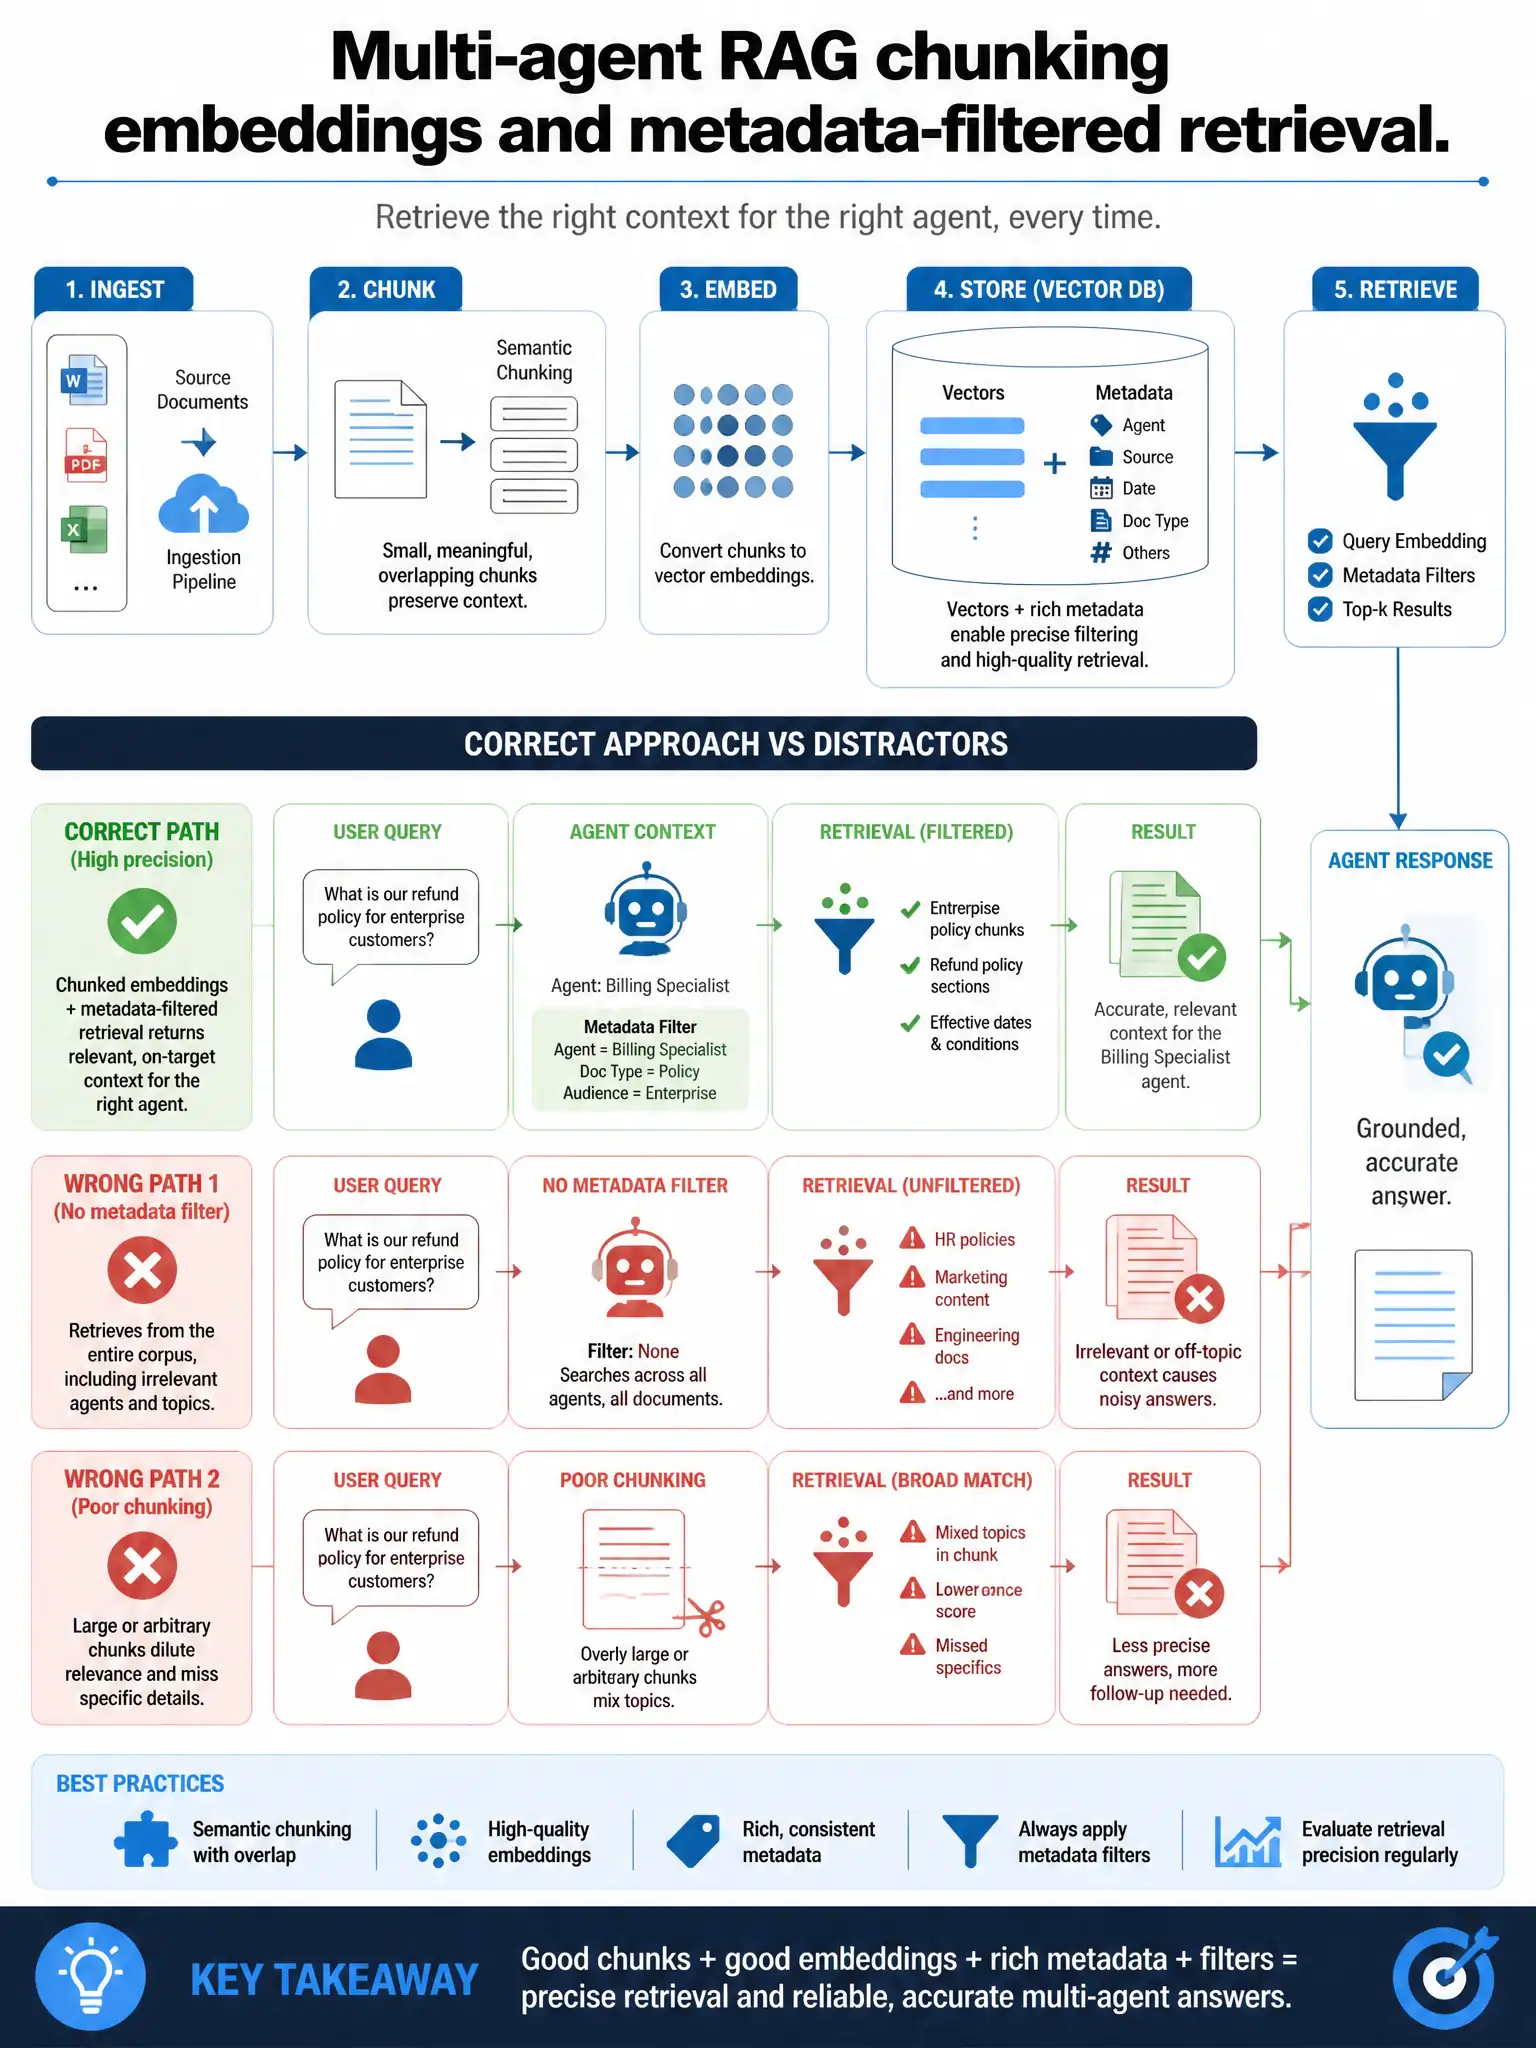
You don't need bigger prompts; you need better retrieval. Tune chunks around tables and procedures, sharpen embeddings for domain terms, and scope each agent's queries with metadata filters. That keeps the exception agent from grabbing the wrong rule.
Full Explanation
Correct answer — retune table and procedure chunk boundaries, improve domain-term embeddings, and use metadata filters so each agent queries with role-appropriate scopes
Multi-agent RAG needs chunking strategy, embedding quality, and retrieval precision. Role-scoped metadata filters prevent specialists from consuming irrelevant passages; table-aware chunking reduces partial-table errors. Bad table chunks and weak embeddings tank precision, so the exception agent can apply the wrong rule.
Why the single-document embedding approach is wrong: Oversized single-document chunks degrade embedding fidelity and ranking.
Why the full-corpus prompt approach is wrong: Full-corpus prompt injection is impractical and expensive at scale.
Why the parametric-memory-only approach is wrong: Parametric-only answers increase hallucination and skip enterprise knowledge.
Exam caveat: Wrong-rule symptoms often mean retrieval precision, not only prompt tone.