
During architecture design, the ops team insists the multi-agent system must support reproducible debugging of agent reasoning and cross-service traces after incidents. Which components should you specify up front?
Select an answer to reveal the explanation.
Short Explanation
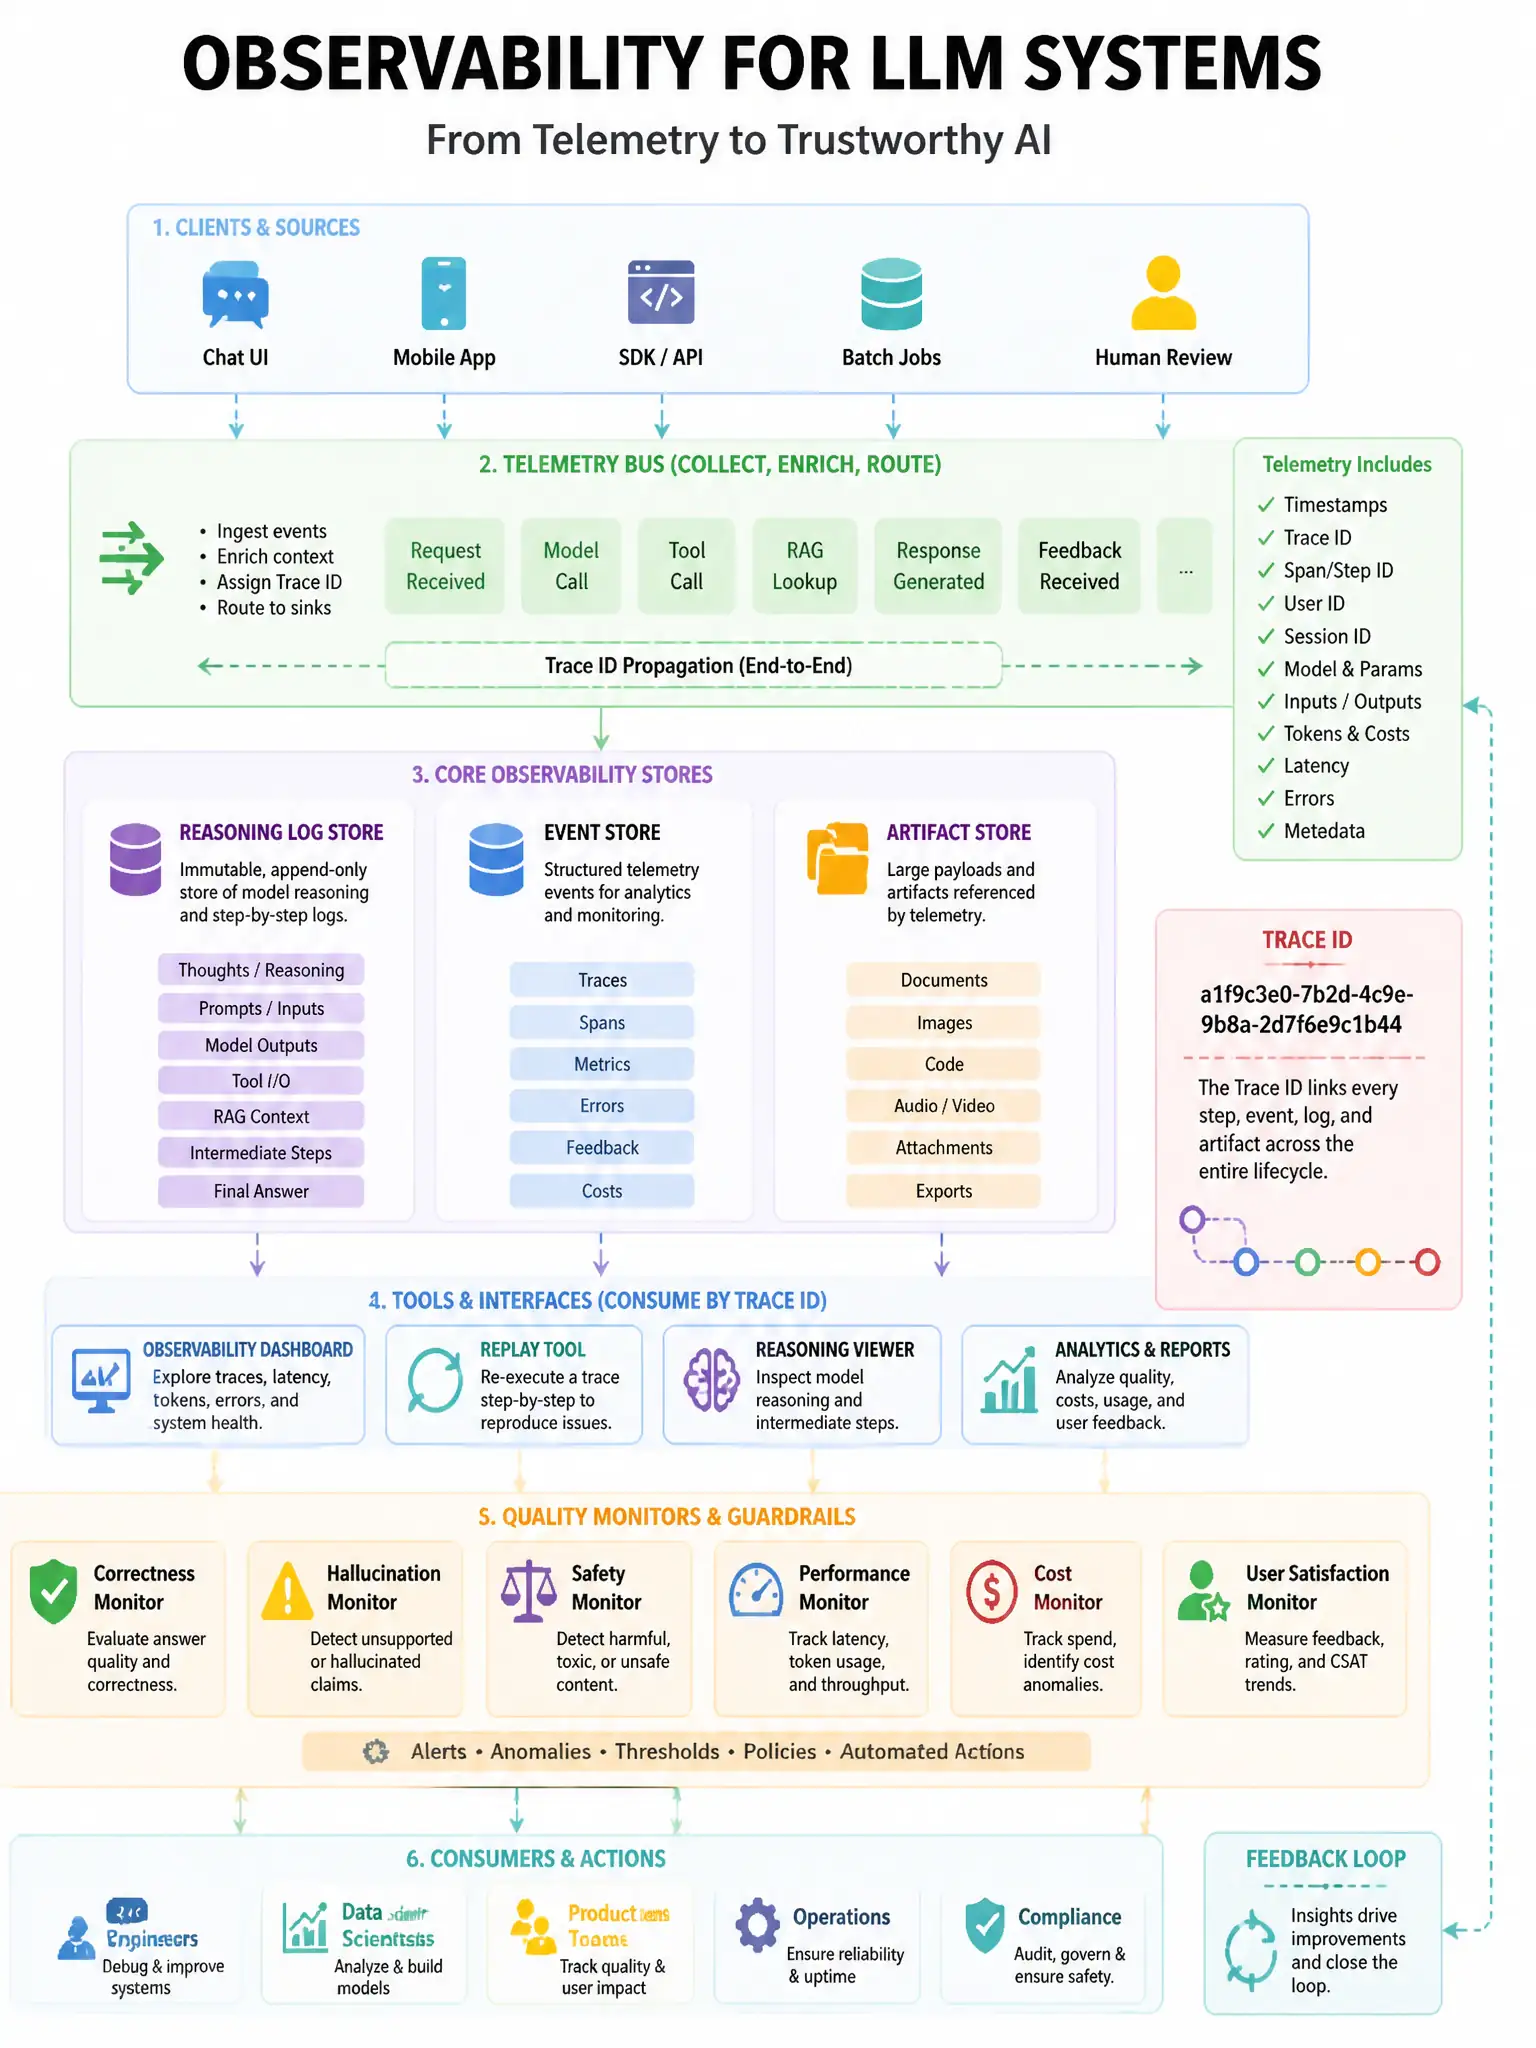
You need observability baked into the design: cross-service trace correlation, structured reasoning logs, replay capture, and monitors for coordination failures and quality regression. Pretty dashboards, emailed CPU PDFs, and disabling logs won't let you replay incidents.
Full Explanation
Specifying observability and monitoring is part of multi-agent architecture: trace correlation, structured reasoning logs, replay, coordination tracking, drift/quality detection, and remediation. The option with cross-service trace correlation, structured reasoning logs, replay capture, and coordination/quality monitoring is correct. Only decorative dashboard colors with no telemetry schema, monthly CPU PDFs emailed to leadership, and disabling production logging for latency omit actionable correlated telemetry. Define retention, prompt PII redaction, and attributes like agent id, tool name, correlation id, and token counts.