
You are implementing multi-agent RAG for a legal research suite. A retrieval agent fetches passages; a drafting agent writes memos; a cite-check agent validates sources. Lawyers report fluent memos that miss controlling authority. Which RAG implementation focus best improves multi-agent consumption quality?
Select an answer to reveal the explanation.
Short Explanation
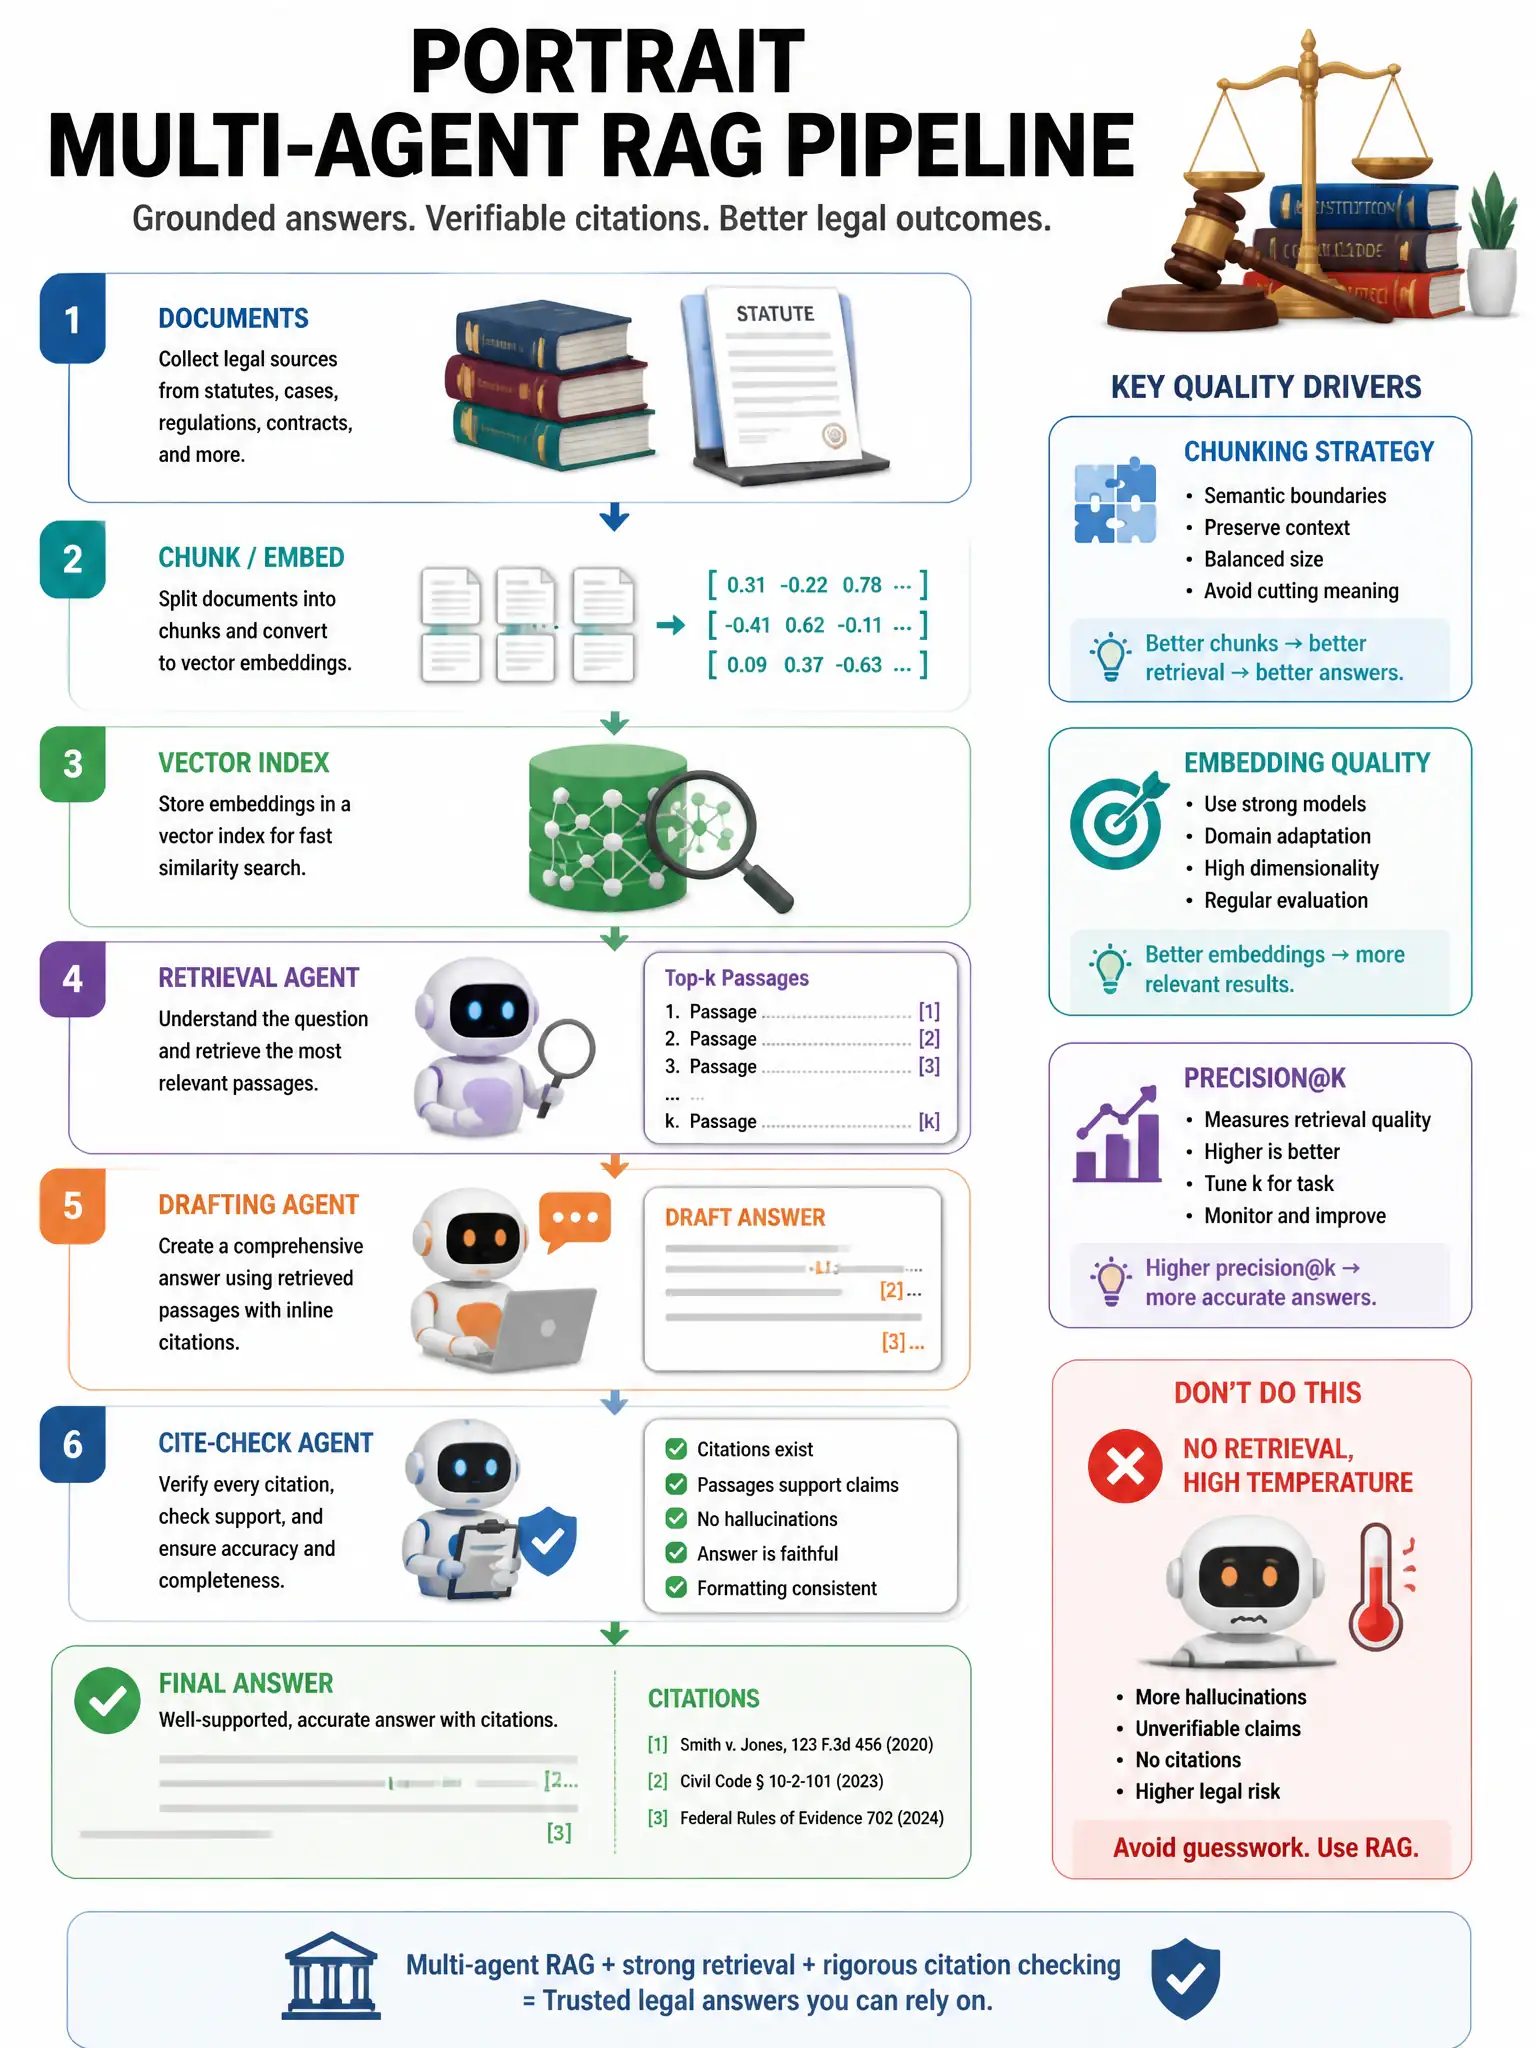
You need to fix retrieval, not the writer. Better chunking, embeddings, and precision/recall get controlling passages to the drafting and cite-check agents with citations and metadata. That’s what stops fluent memos from missing authority.
Full Explanation
The correct focus is improving chunking strategy, embedding quality, and retrieval precision/recall so the retrieval agent supplies controlling passages, and passing citations and chunk metadata to drafting and cite-check agents. Multi-agent RAG needs consistent, citable context; metadata-rich retrieval lets the cite-check agent validate claims. Increasing drafting temperature and disabling retrieval is wrong because it increases ungrounded content. Giving raw 500-page PDFs without chunking is wrong because it is inefficient and often exceeds useful context. Using identical random chunk boundaries and never evaluating retrieval metrics is wrong because it prevents continuous improvement. Evaluate groundedness and citation accuracy across the agent chain. Treat retrieval quality as a first-class pipeline with metrics, not a black box behind a chatty writer agent.