
Northwind’s multi-agent underwriting system fails intermittently when three specialist agents collaborate. Engineers need to reconstruct which agent reasoned what, which tools ran, and how tokens were consumed across services. Which observability components should the architect specify?
Select an answer to reveal the explanation.
Short Explanation
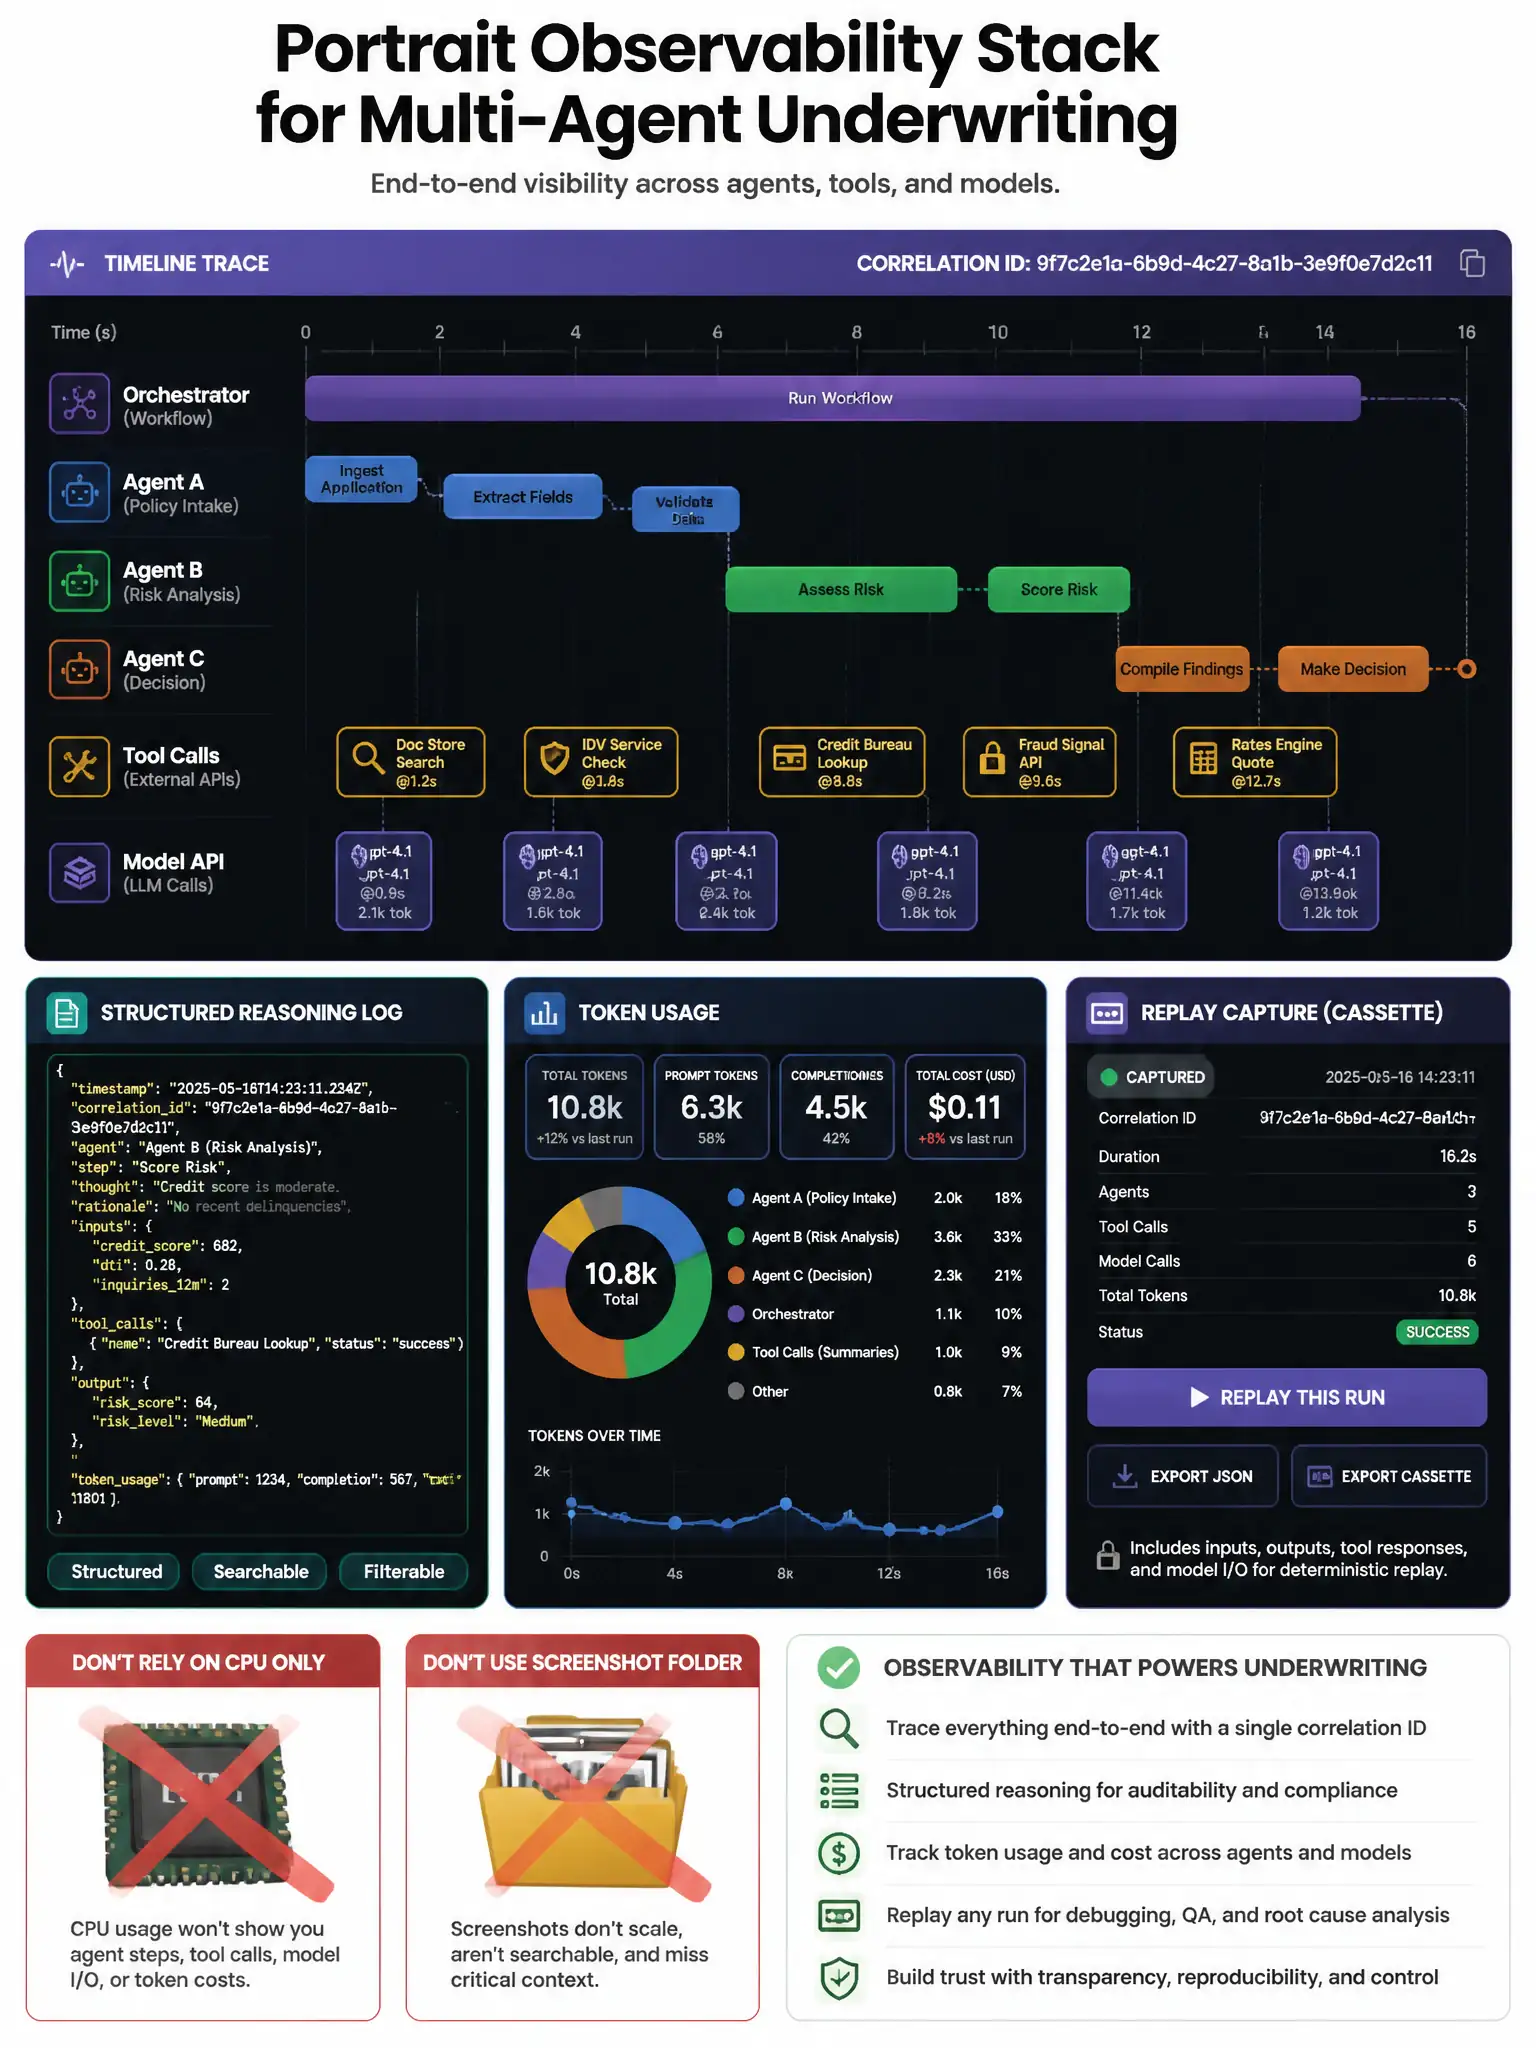
You need cross-service trace correlation so you can follow one request across the orchestrator, agents, tools, and model calls. You can't debug multi-agent failures with CPU charts, screenshots, or disabled production tracing. Specify correlation IDs, structured reasoning and tool logs, token telemetry, and replay capture so you can reproduce what happened.
Full Explanation
Multi-agent architectures should include observability components for cross-service trace correlation with correlation IDs, structured logging of agent reasoning and tool paths, token/prompt telemetry, execution tracking, and agent replay capture for reproducible debugging. The Azure VM CPU charts choice is incorrect: host CPU metrics do not reveal reasoning errors, tool failures, or coordination bugs. The UI screenshot choice is incorrect: UI screenshots lack correlation IDs, spans, and structured tool results. The disable tracing choice is incorrect: production-only failures require production telemetry; disabling traces increases mean time to recovery. Design correlation IDs that flow through orchestrator -> agents -> MCP/tools -> model endpoints, and retain replay artifacts under access control.