
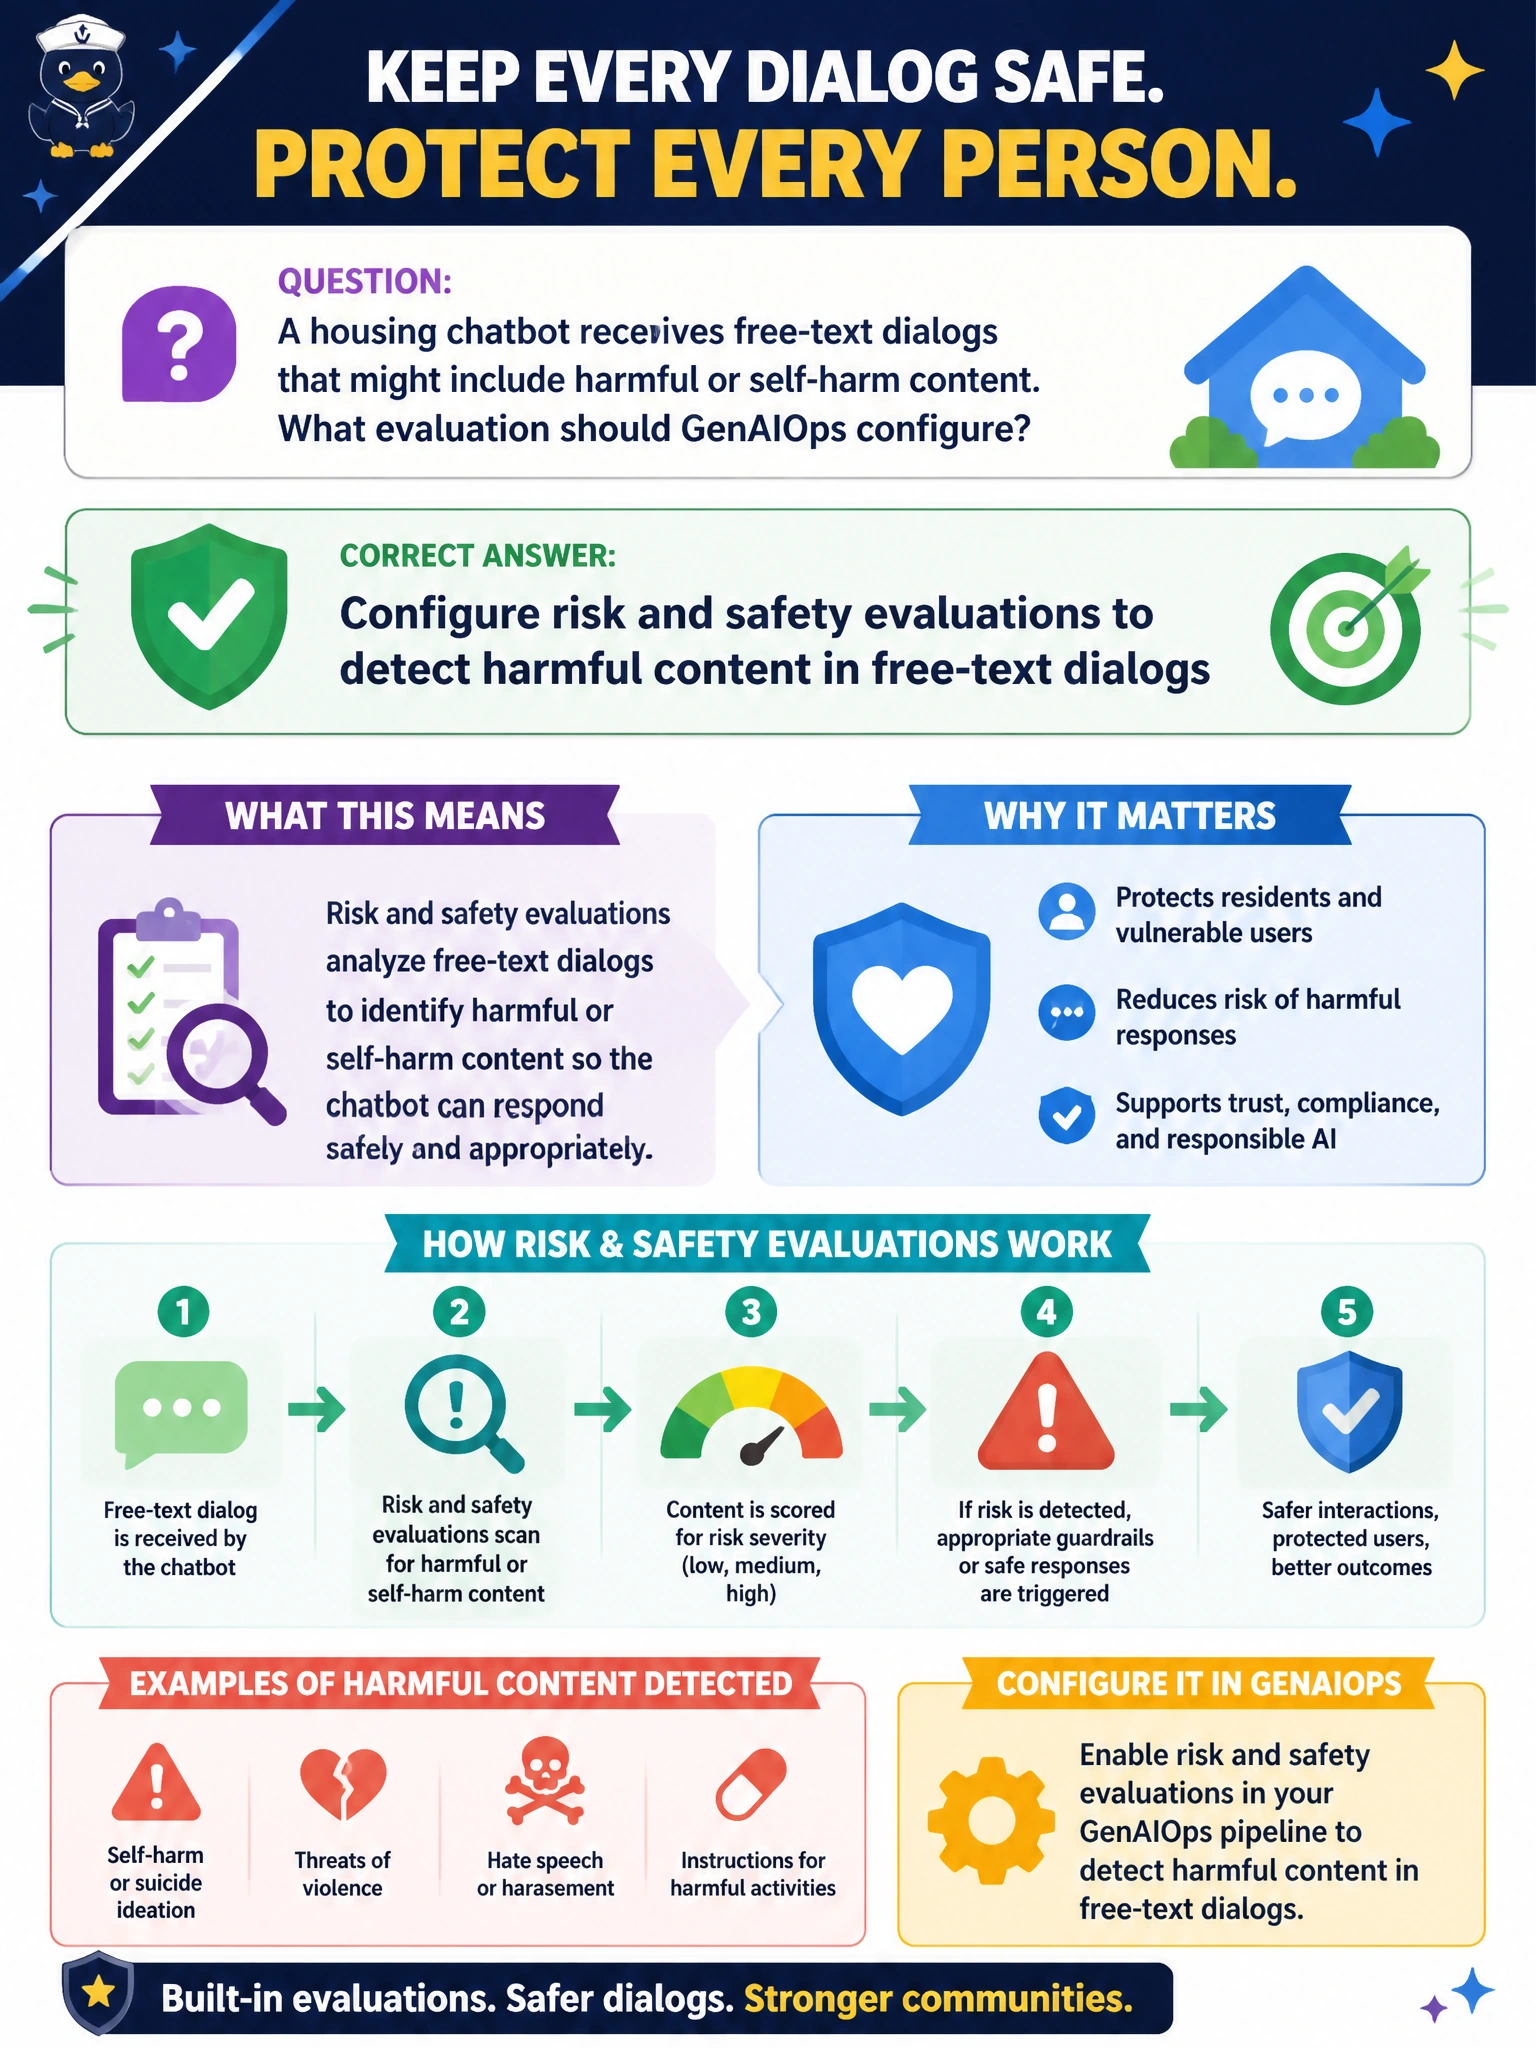
A housing chatbot receives free-text dialogs that might include harmful or self-harm content. What evaluation should GenAIOps configure?
Select an answer to reveal the explanation.
Short Explanation
Resident chats can go dark places — housing bots need a safety net. Wire risk and safety evaluations so harmful content gets caught before promotion.
Full Explanation
Configuring risk and safety evaluations to detect harmful content in free-text dialogs is the GenAIOps control for a housing chatbot that may receive self-harm or other harmful content. Safety evals score prompts and outputs against harm categories, jailbreaks, and policy violations before and after release. Municipal housing chats often include crisis language, abuse reports, or hostile content; detecting those patterns enables refusal, escalation to human services pathways, and measurement of whether prompt or model changes weaken protections.
Configuring groundedness evaluations to detect harmful content in free-text dialogs fails because groundedness measures factual alignment with source documents, not whether free-text dialogs contain harmful or self-harm content, so it cannot serve as the release-gating safety control. Configuring performance evaluations to detect harmful content in free-text dialogs fails because latency and throughput measure system speed, not the presence of harmful content, and do not provide the safety gating required for resident dialogs. Configuring fluency evaluations to detect harmful content in free-text dialogs fails because fluency measures language quality, not harm detection, and cannot substitute for systematic risk and safety scoring of free-text chats.
Exam caveat: Safety evaluation configuration must match city policy and escalation playbooks (including crisis resources). Over-blocking can deny legitimate housing help; tune thresholds with housing and social-services SMEs, and log false positives for review.
Operational check: Enable risk/safety eval suites on the housing dialog dataset and on red-team prompts; require passing safety gates in the release pipeline; verify escalation messaging for self-harm intents matches the approved civic script; monitor production safety-hit rates; and re-run suites after every model or prompt change.
Prefer to study offline? Printable PDF study book + test engine ($7.50, unofficial). These questions stay free here.