
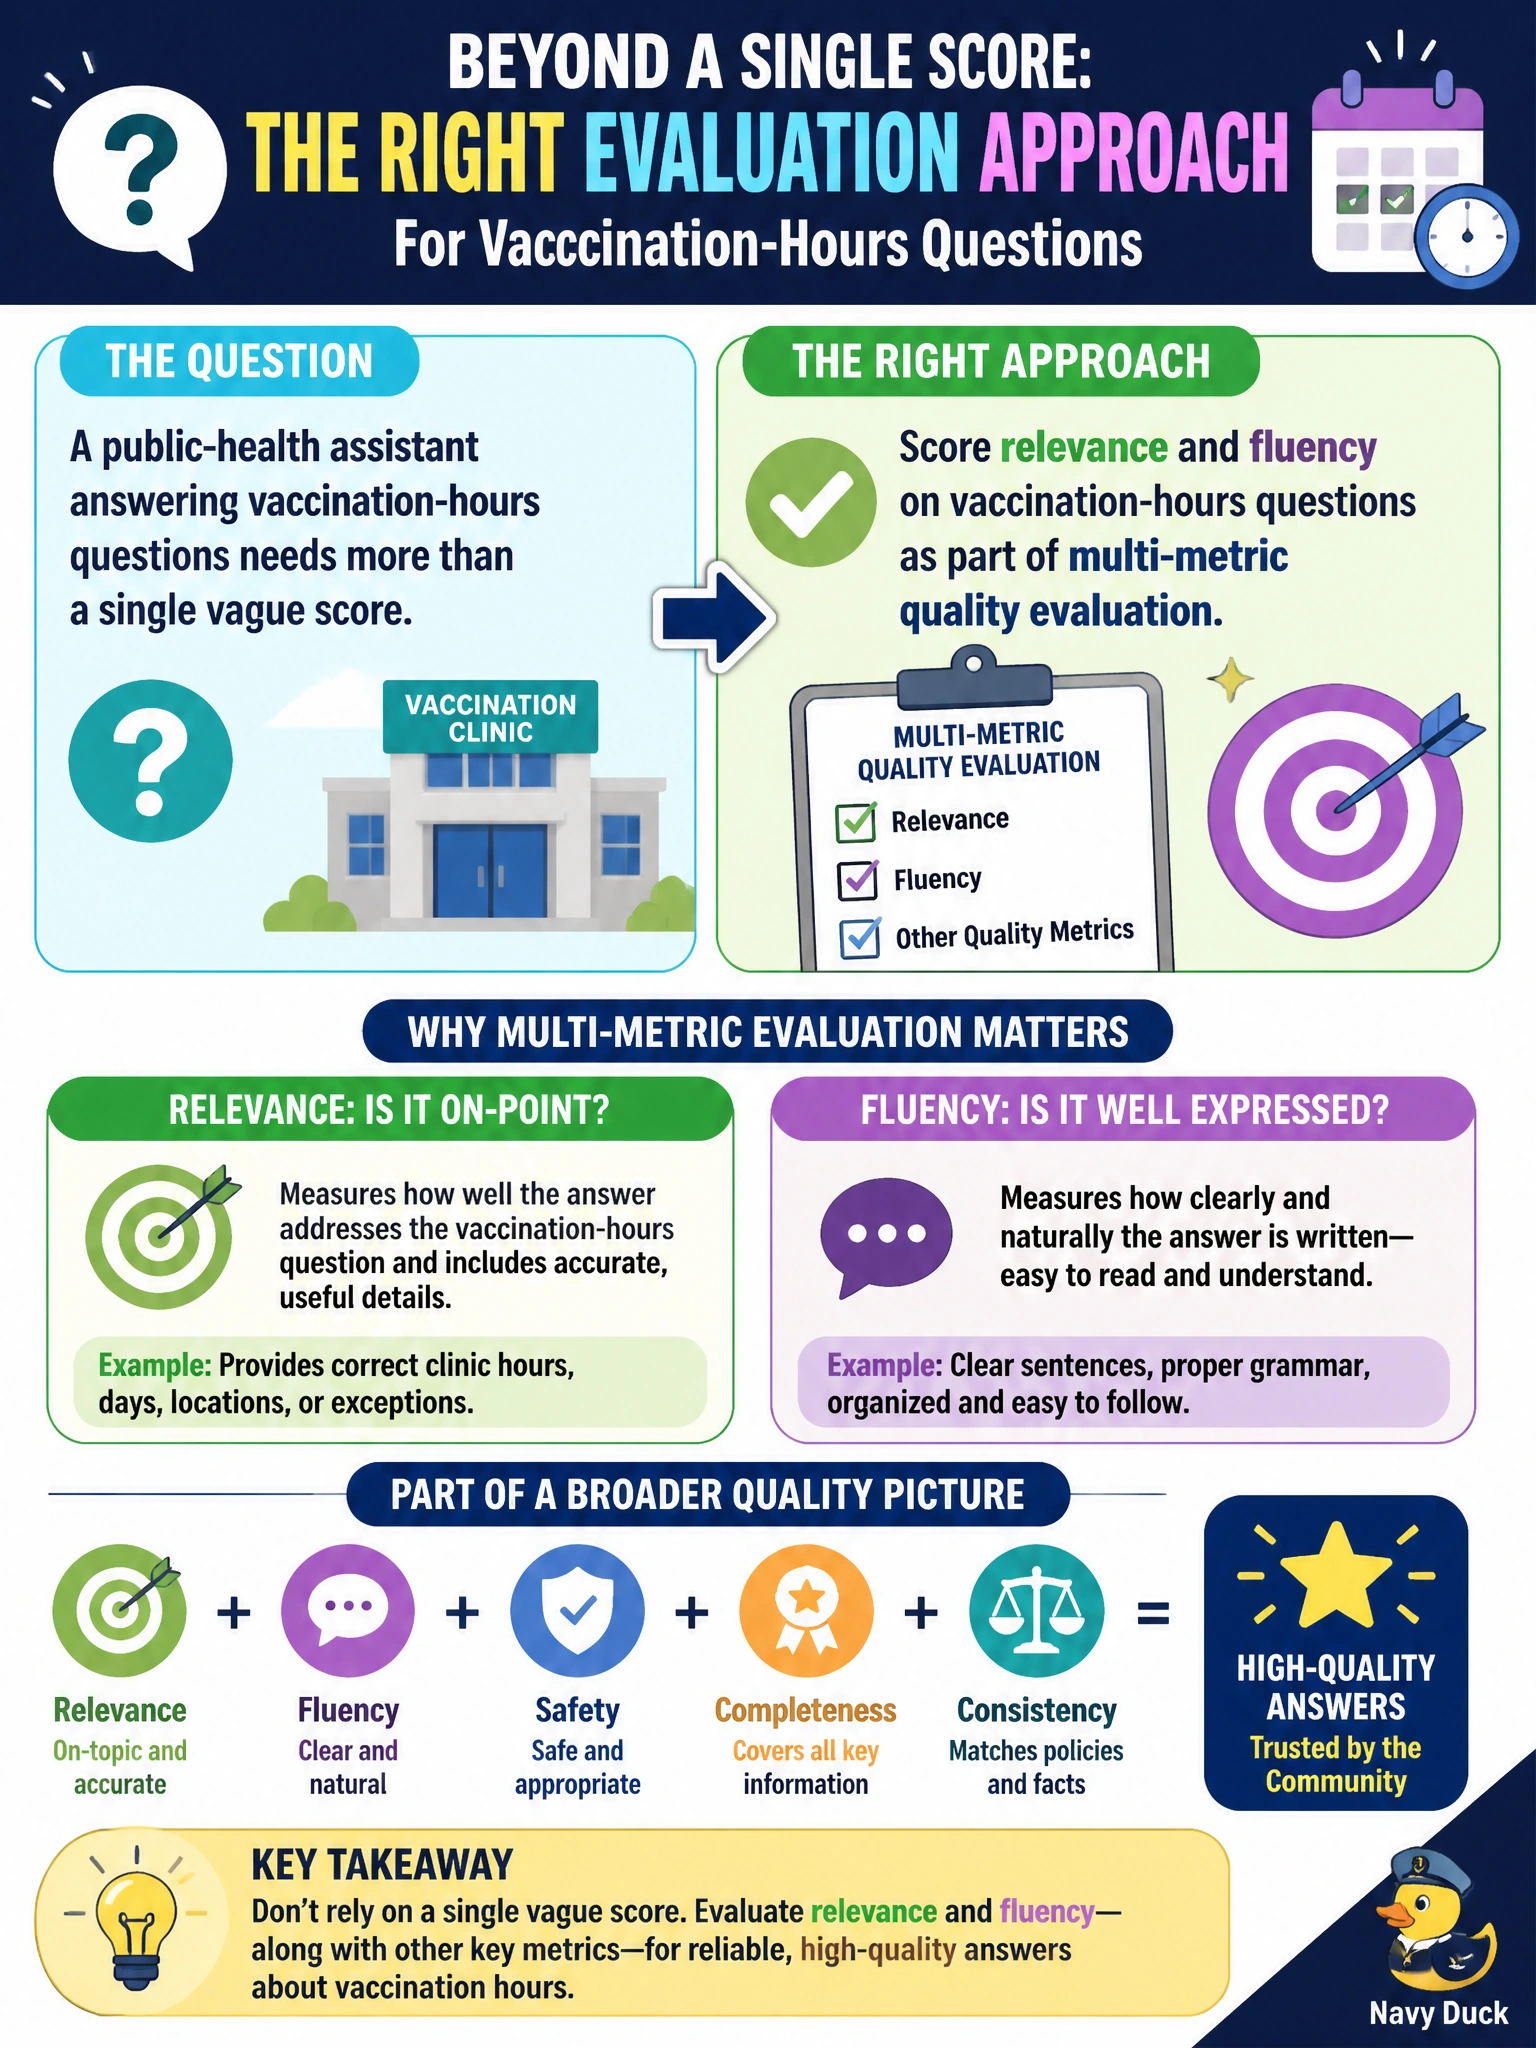
A public-health assistant answering vaccination-hours questions needs more than a single vague score. What evaluation approach fits?
Select an answer to reveal the explanation.
Short Explanation
On-hours questions can be correct-ish yet weirdly worded — or smooth yet off-topic. Score relevance and fluency together so the health assistant is useful and clear.
Full Explanation
Scoring relevance and fluency on vaccination-hours questions as part of multi-metric quality evaluation gives a public-health assistant the nuanced signal a single vague score cannot. Relevance checks that answers address clinic hours, locations, and eligibility; fluency checks that wording is clear for residents. Multi-metric evaluation surfaces cases that are fluent but off-topic or on-topic but garbled—both harmful for vaccination access messaging—and supports GenAIOps tradeoff decisions when a prompt edit improves one dimension and hurts another.
Scoring recall and precision on vaccination-hours questions as part of multi-metric quality evaluation fails because recall and precision measure retrieval coverage from schedule sources, not the quality of the final answer, so results can retrieve the right hours yet still be off-topic or garbled with no relevance or fluency signal for residents. Scoring hate and unfairness on vaccination-hours questions as part of multi-metric quality evaluation fails because those safety metrics detect toxic or biased language, not whether the answer addresses the resident's hours, eligibility, or location question clearly, so a safe answer can still be unhelpful and confusing. Scoring adherence and tool-call on vaccination-hours questions as part of multi-metric quality evaluation fails because those metrics check tool use and instruction following, not whether the hours response is relevant and fluent, and they offer no detail to guide fixes for off-topic or unclear messaging.
Exam caveat: Multi-metric dashboards need agreed weights or gates per civic risk; fluency must never outrank factual relevance for hours and locations. Keep hours test data synchronized with clinic schedule sources.
Operational check: Configure the eval job to emit relevance and fluency (plus groundedness/safety as applicable) on a vaccination-hours slice; set per-metric thresholds; investigate regressions by metric after each prompt change; validate a sample with public-health staff; and confirm schedule source updates invalidate stale expected answers.
Prefer to study offline? Printable PDF study book + test engine ($7.50, unofficial). These questions stay free here.