
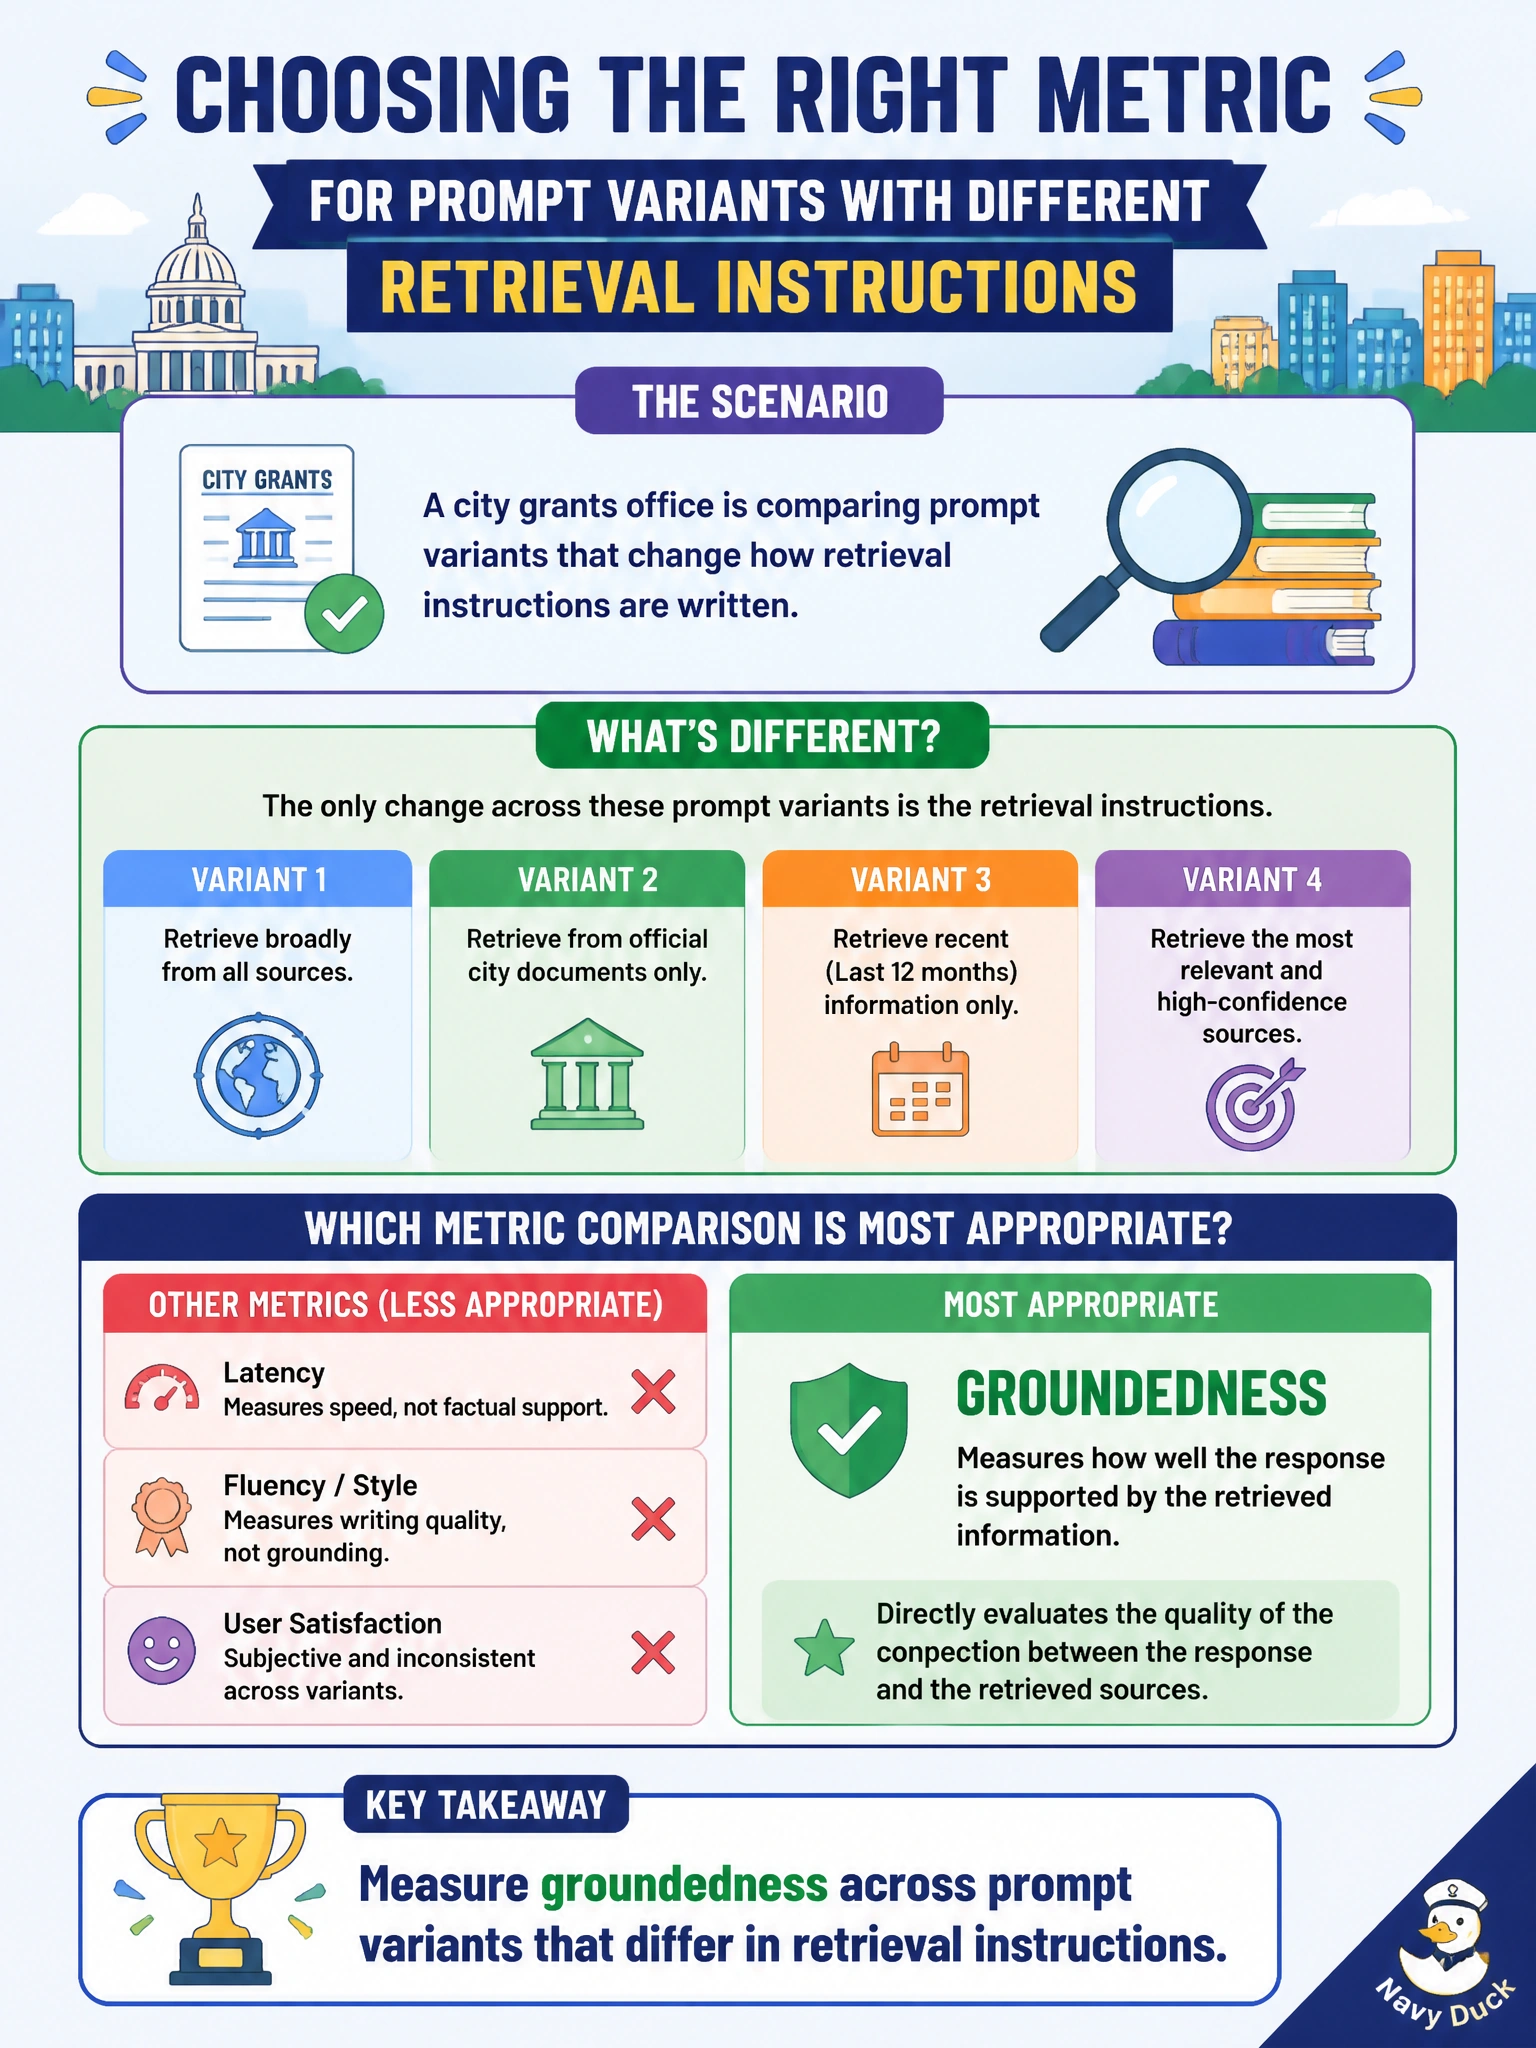
A city grants office is comparing prompt variants that change how retrieval instructions are written. Which metric comparison is most appropriate?
Select an answer to reveal the explanation.
Short Explanation
When prompts change how retrieval works, watch whether answers still stick to the grant docs. Groundedness is the score that tells you which variant stays honest.
Full Explanation
Measuring groundedness across prompt variants that differ in retrieval instructions is the appropriate metric comparison for a city grants office. When prompts change how the model calls or uses retrieval (top-k, citation rules, refuse-if-missing), the risk is that answers sound fluent while detaching from grant program documents. Groundedness scores whether claims remain supported by municipal sources, so GenAIOps can pick the retrieval-instruction variant that improves citation fidelity rather than comparing fluency, measuring one variant repeatedly, or comparing latency.
Comparing fluency ratings across prompt variants that differ in retrieval instructions fails civic accuracy—grant eligibility language must be correct, not just smooth. Measuring groundedness for a single prompt variant with repeated sampling fails mission outcomes; you cannot tell whether a retrieval-instruction variant actually improves citation fidelity without comparing variants. Comparing latency averages across prompt variants that differ in retrieval instructions fails transparency and auditability that grant programs require; fast answers are not enough if they are not grounded in municipal sources.
Exam caveat: Groundedness depends on retrieval quality as much as prompt text; a prompt cannot ground answers if the index lacks current NOFOs or program guides. Compare variants with the same corpus and judge model so metric deltas reflect instruction changes.
Operational check: Build an eval set of grant FAQs with required source passages; score groundedness (and citation presence) for each retrieval-instruction variant; set a minimum groundedness gate before promotion; review false-ungrounded and false-grounded errors with program staff; and re-run after corpus updates.
Prefer to study offline? Printable PDF study book + test engine ($7.50, unofficial). These questions stay free here.