
A housing eligibility helper must choose between two prompt variants before go-live. What comparison approach is sound?
Select an answer to reveal the explanation.
Short Explanation
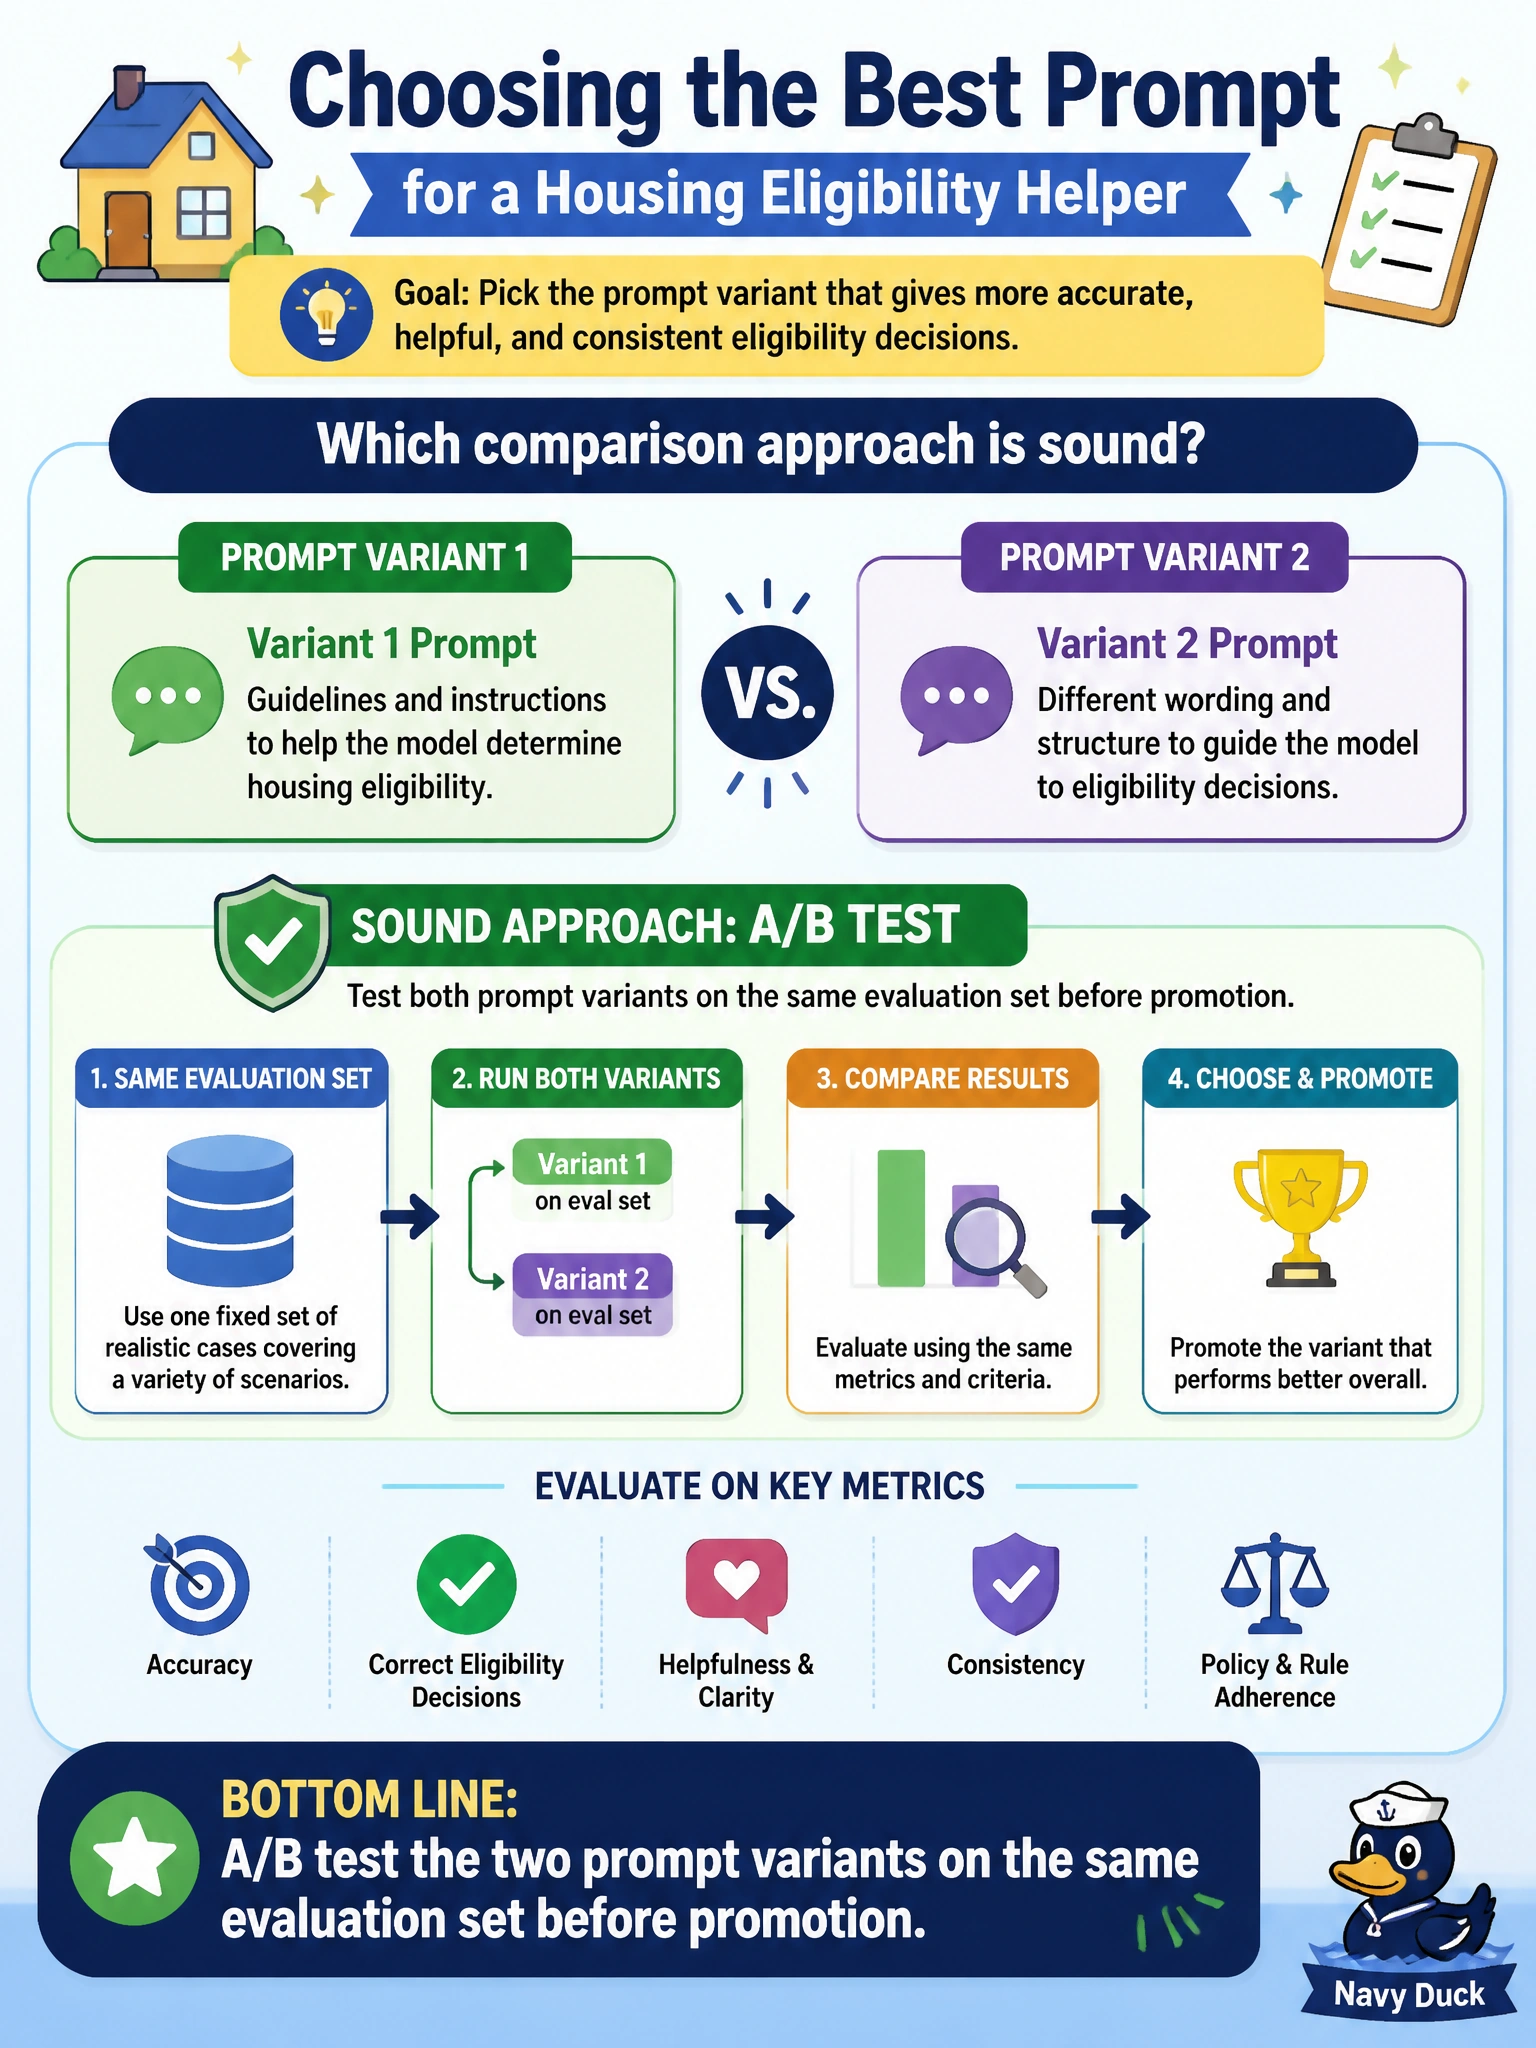
You can't fairly compare one prompt in staging against another in live traffic—conditions differ too much. Run both variants on the same housing eval set, then promote the winner with evidence.
Full Explanation
A/B testing two prompt variants on the same evaluation set before promotion is the sound comparison approach for a housing eligibility helper. Holding the question set, labels, model, and retrieval context constant attributes score differences to the prompt. That prevents false wins from easier questions or cherry-picked chats and gives housing program owners a defensible go-live decision based on eligibility accuracy, groundedness, and unsafe-advice refusal rates.
Selecting the variant with lower measured average token cost on the same evaluation set optimizes for cost rather than eligibility quality; a cheaper prompt can still generate incorrect eligibility determinations, unsafe advice, or ungrounded answers, so token cost alone cannot identify the variant that should go live. Comparing the first variant in staging against the second variant in production traffic fails experimental control because live traffic differs from staging in users, timing, and question mix; apparent wins may come from easier production chats rather than superior prompt performance. Ranking the variants by BLEU similarity to reference answers fails because BLEU only measures surface text overlap, not eligibility accuracy, groundedness, or refusal of unsafe advice; a response can closely match a reference wording while still giving wrong housing guidance.
Exam caveat: Same evaluation set is necessary for fairness, but the set must also be representative of real housing questions (languages, edge cases, adversarial prompts). Offline A/B on a fixed set is not identical to live traffic experiments, which need additional governance for resident-facing eligibility advice.
Operational check: Freeze an evaluation snapshot; score both variants with the same metrics and thresholds; document the winner and residual failure modes; promote only through the normal Foundry deployment path; and re-run the same set after promotion to confirm the live configuration matches the evaluated prompt.
Prefer to study offline? Printable PDF study book + test engine ($7.50, unofficial). These questions stay free here.