
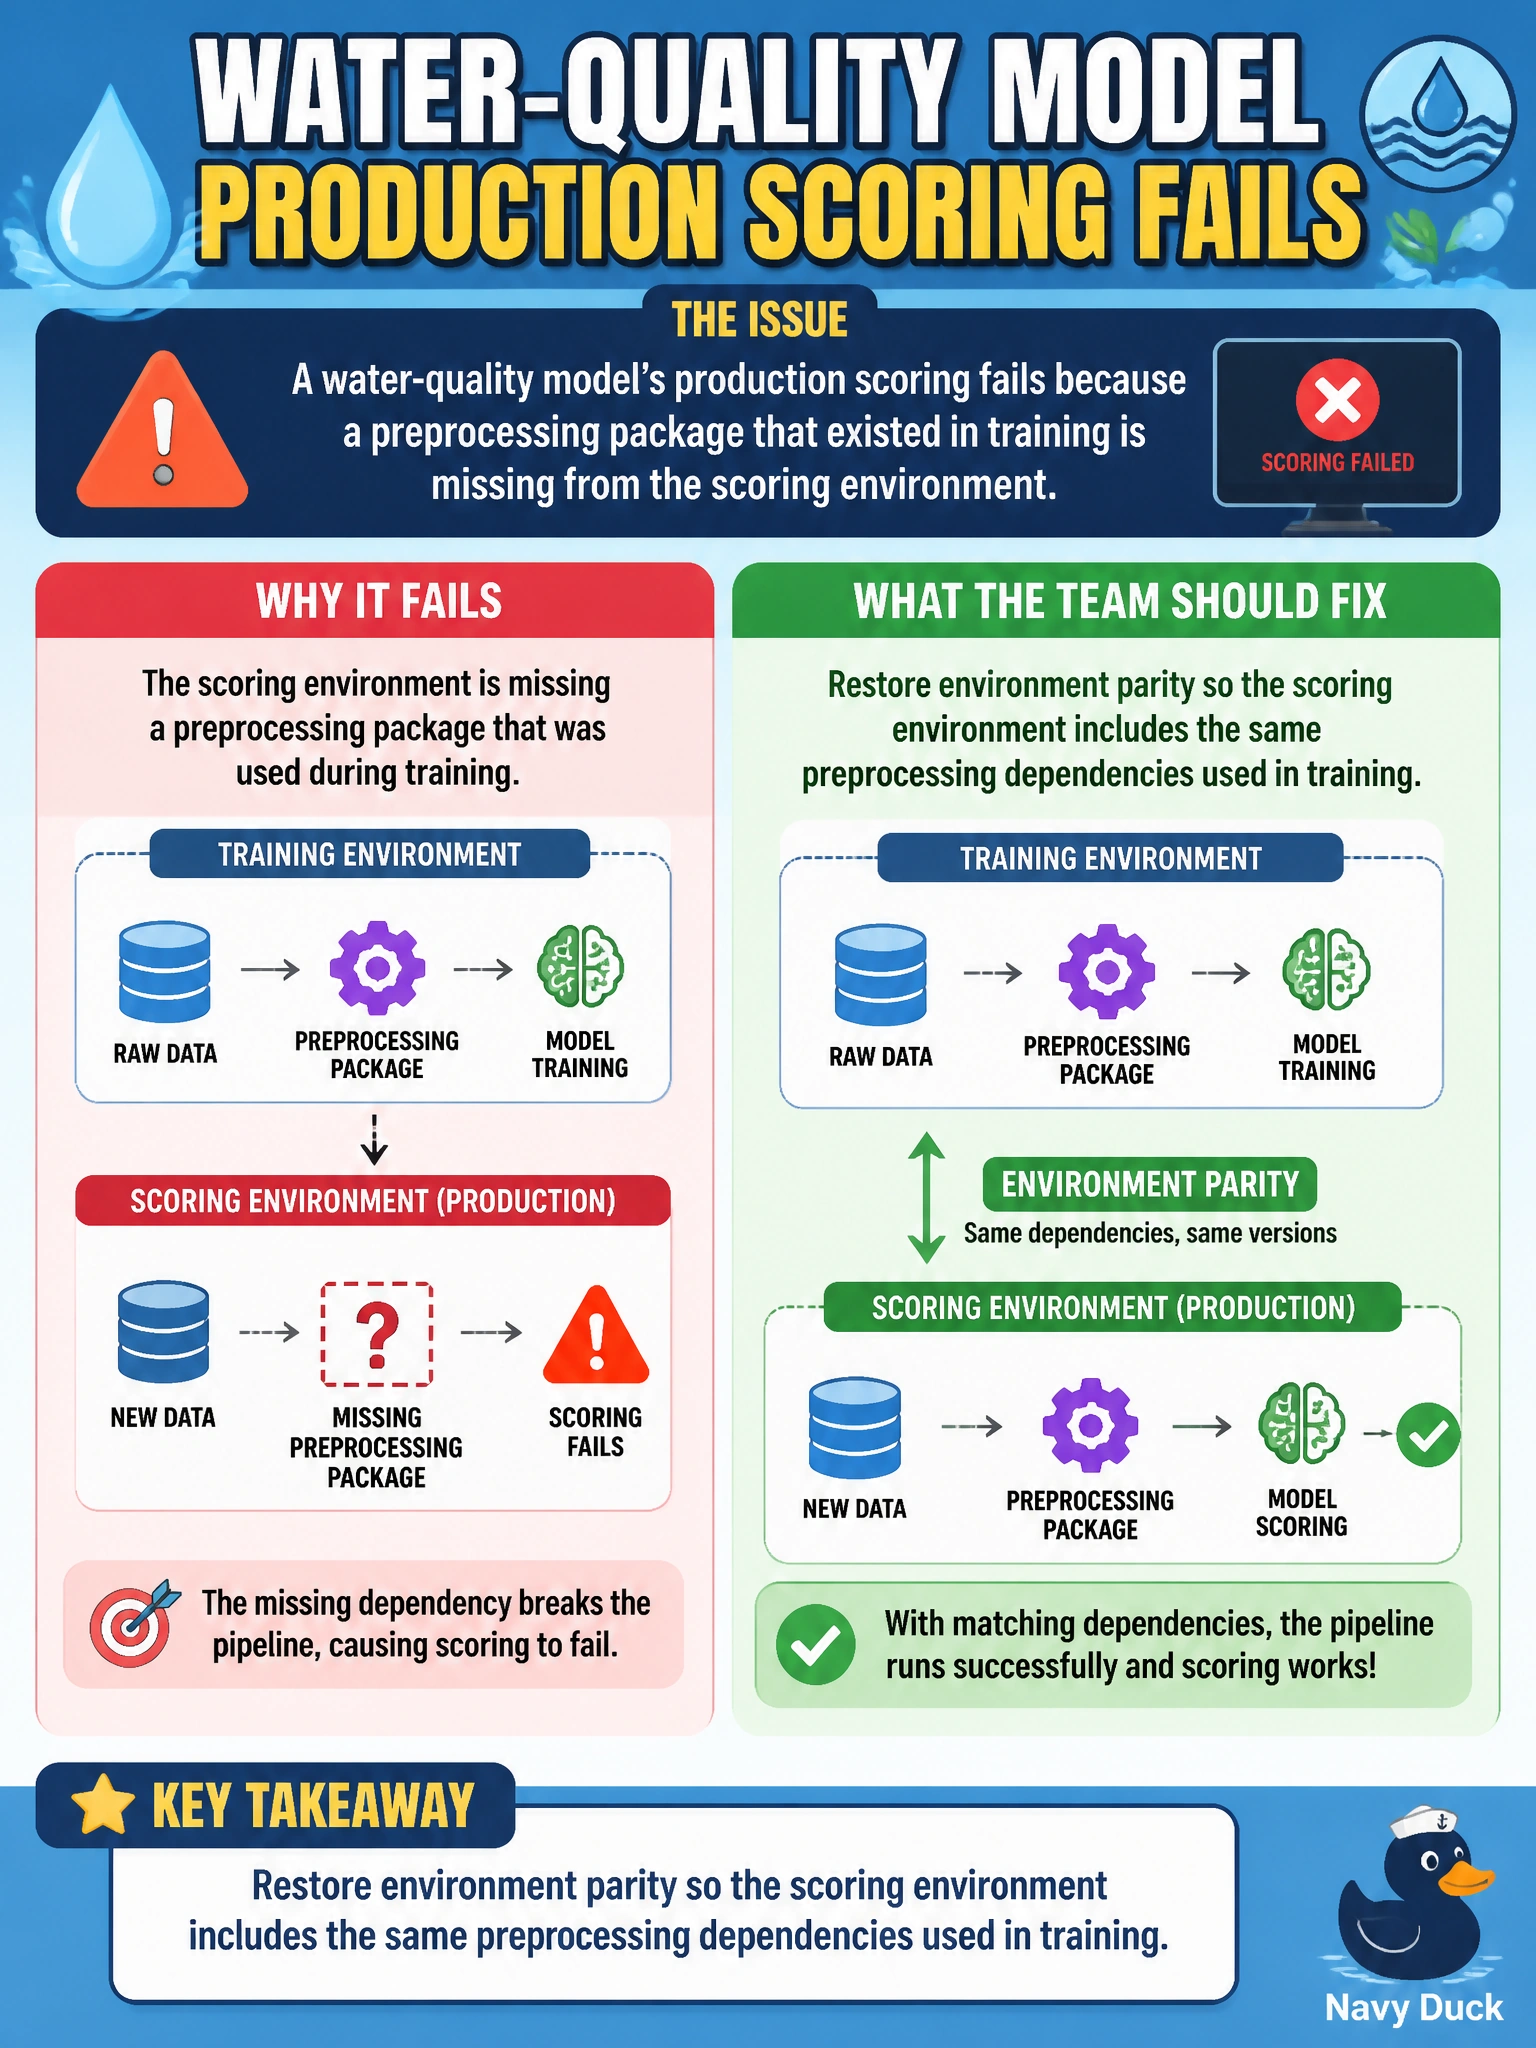
A water-quality model's production scoring fails because a preprocessing package that existed in training is missing from the scoring environment. What should the team fix?
Select an answer to reveal the explanation.
Short Explanation
Training and scoring have to speak the same dialect. If preprocessing was in the training environment, it belongs in the scoring environment too. You can't fix a missing package by re-registering with new lineage tags since tags don't install anything, so scoring still breaks.
Full Explanation
Restoring environment parity so the scoring environment includes the same preprocessing dependencies used in training is correct because production scoring must execute the same preprocessing contract the water-quality model learned. If a package present in training is missing at score time, pipelines fail or silently diverge. Aligning training and scoring Azure ML environments—same pins for preprocessing libraries—restores operational correctness for municipal water-quality inference.
Re-registering the water-quality model with new lineage tags so scoring inherits the training preprocessing dependencies only updates registry metadata; it does not install the missing preprocessing package in the scoring environment, so scoring will still fail at import time. Rebuilding the scoring image from the training base image using the newest compatible release of the preprocessing package does not restore exact environment parity, because a newer release can change preprocessing behavior from what the model learned, so the same pinned version must be restored. Retraining the water-quality model on the scoring compute so the training dependencies align with the production environment does not fix the scoring environment and wastes training effort; the scoring image will still lack the required preprocessing package.
Exam caveat: training/serving skew often appears as missing preprocessing packages. Fix environment parity; do not re-register the model with new lineage tags to inherit dependencies, and do not rebuild from the training base image using the newest compatible release instead of the same pinned preprocessing version. Register scoring environments as deliberately matched siblings of training environments.
Operational check: compare training vs scoring environment specifications, add the missing preprocessing package to the scoring environment (or rebuild both from one locked spec), redeploy or resubmit scoring, and verify a known water-quality batch scores without ModuleNotFound-style failures.
Prefer to study offline? Printable PDF study book + test engine ($7.50, unofficial). These questions stay free here.