
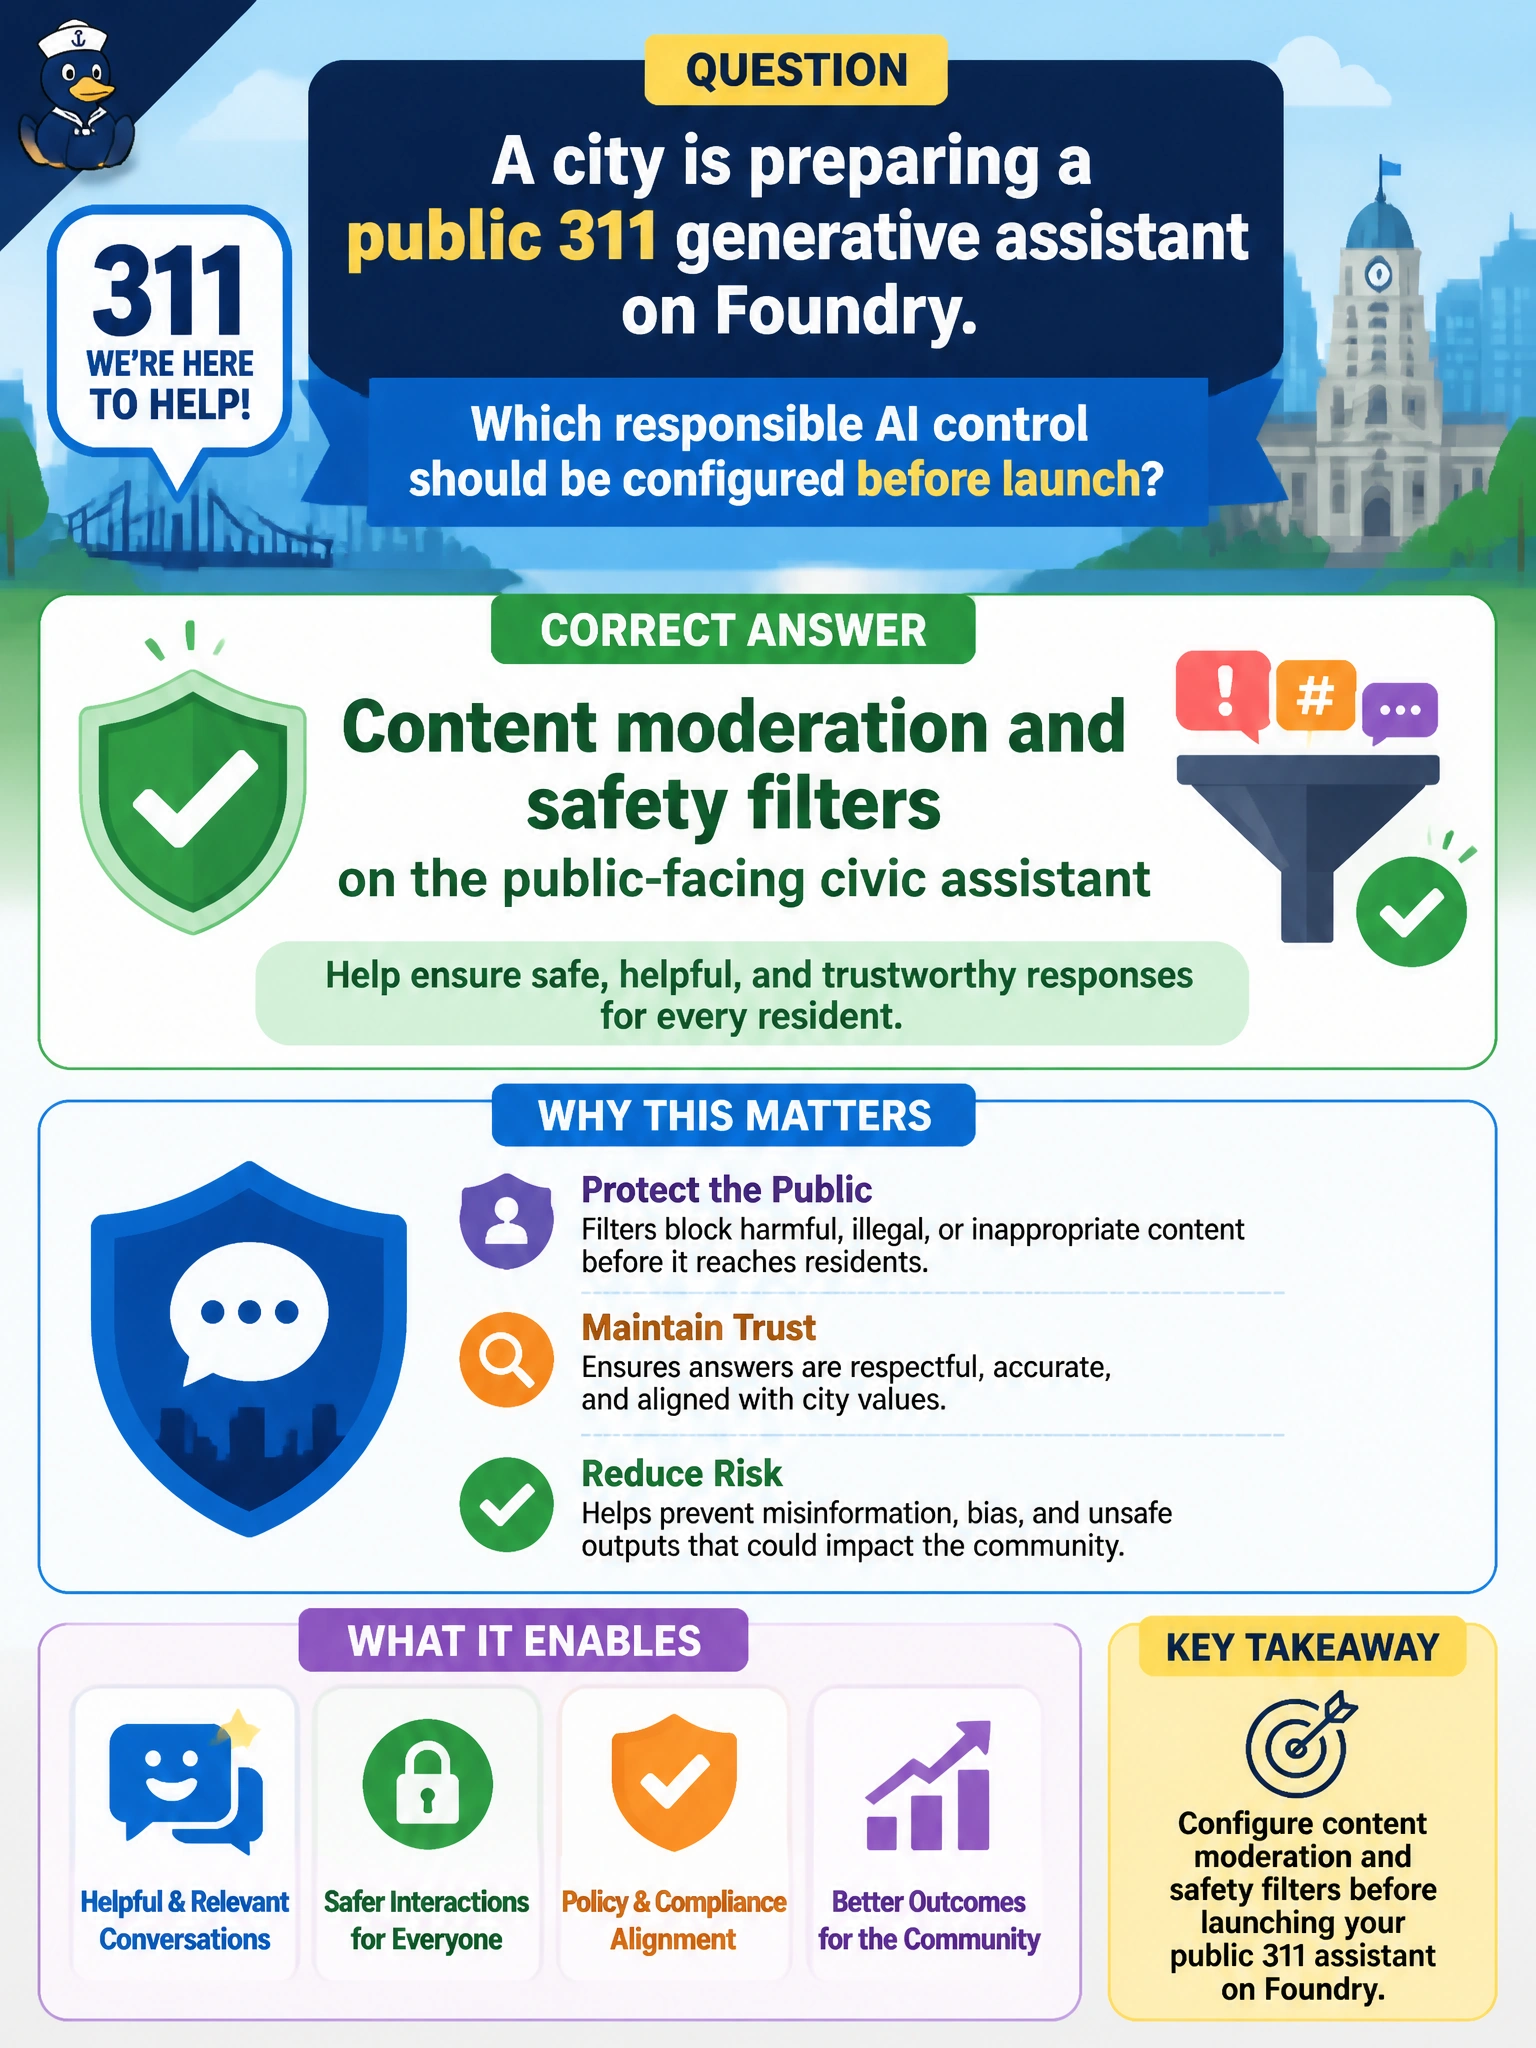
A city is preparing a public 311 generative assistant on Foundry. Which responsible AI control should be configured before launch?
Select an answer to reveal the explanation.
Short Explanation
A public 311 bot will hear everything from pothole complaints to nasty junk—you need a bouncer. Turn on content moderation and safety filters before launch so harmful prompts and outputs get blocked. Residents still get help; the city does not amplify abuse.
Full Explanation
Before launching a public 311 generative assistant on Foundry, the city must configure content moderation and safety filters on the public-facing civic assistant. The control works because open resident channels receive harassment, self-harm content, jailbreaks, and off-policy requests; input/output filtering and blocklists reduce harmful completions and create auditable safety events. Responsible-AI configuration is a launch prerequisite for municipal public bots, not an optional post-incident retrofit.
Prompt shield checks for PII in addresses on the public-facing civic assistant miss the scope because Prompt Shields detect direct and indirect prompt-injection and jailbreak attacks, not PII, and screening for injection does nothing to detect or redact street addresses nor to block harassment, self-harm, hate, or off-policy resident prompts and outputs before launch. Abuse monitoring for 311 answer accuracy on the public-facing civic assistant fails because abuse monitoring flags abusive use and harmful-content patterns for post-deployment review, not whether 311 answers are factually correct, and retrospective monitoring does not filter live resident prompts or outputs before the assistant goes live. Protected material checks for ordinances on the public-facing civic assistant are mis-scoped because city ordinances are public law meant to be quoted, not copyrighted protected material, and copyright-match detection does not filter harmful language or stop abusive completions from reaching residents when the assistant launches.
Exam caveat: filters require ongoing threshold tuning—over-blocking frustrates legitimate 311 intents; under-blocking misses abuse. Operational check: enable Foundry/Azure AI Content Safety (or equivalent) on input and output, review a pre-launch abuse corpus, assign owners for safety dashboards, and document an exception process for false positives that block real service requests.
Prefer to study offline? Printable PDF study book + test engine ($7.50, unofficial). These questions stay free here.