
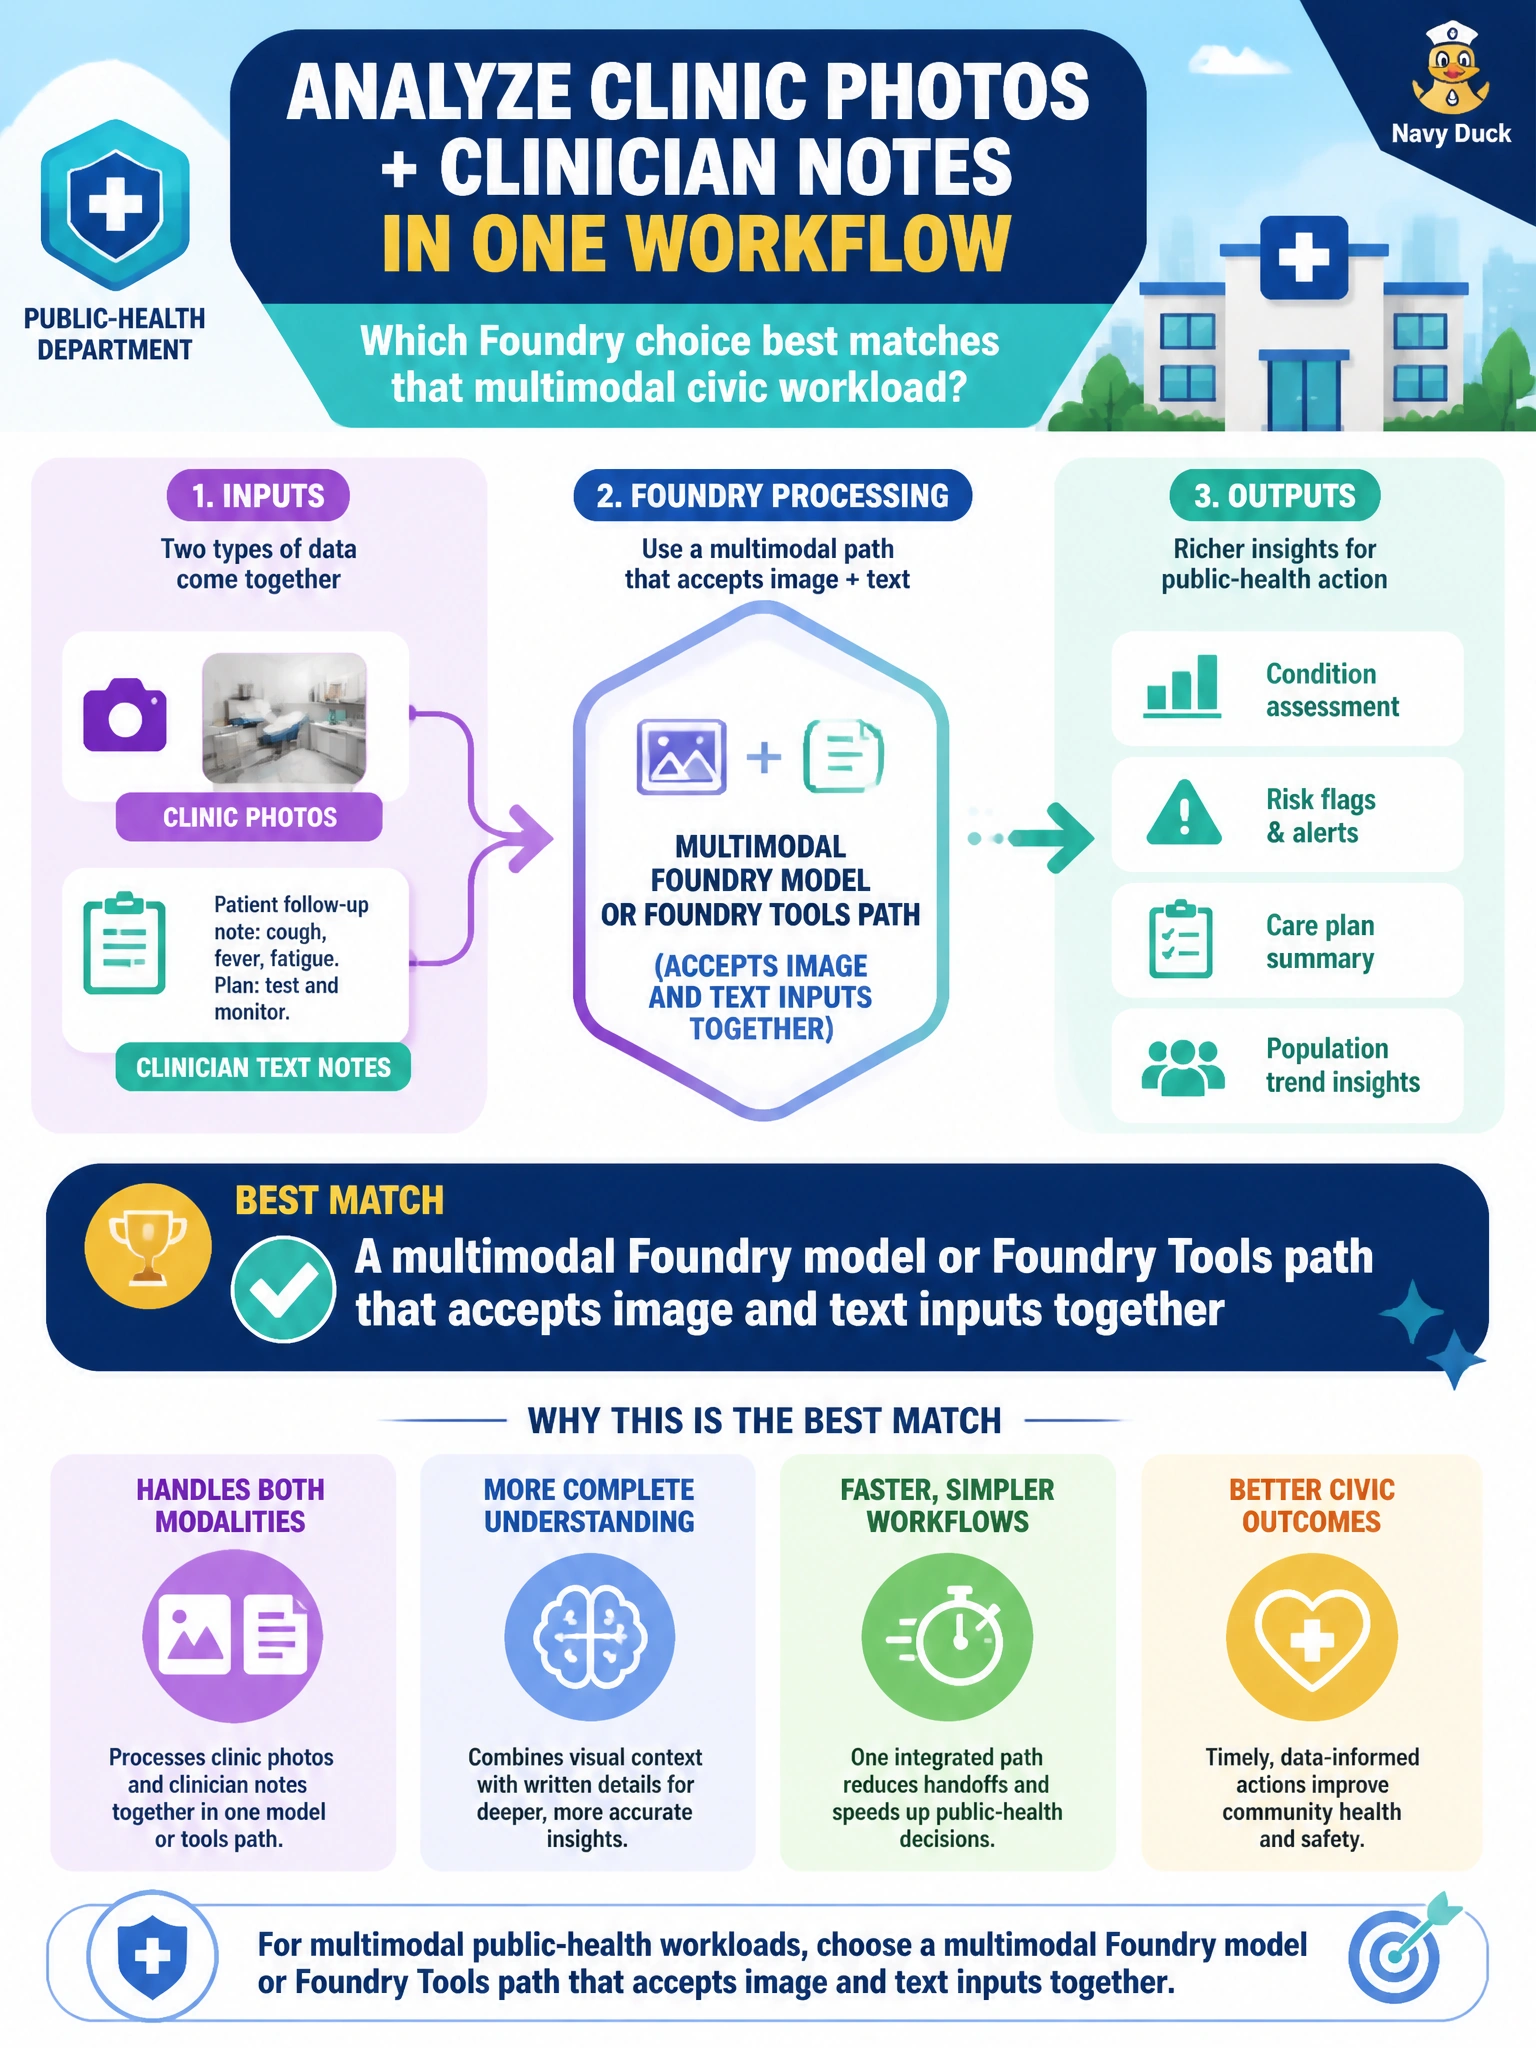
A public-health department must analyze clinic photos together with clinician text notes in one workflow. Which Foundry choice best matches that multimodal civic workload?
Select an answer to reveal the explanation.
Short Explanation
Photos plus notes are a package deal—like reading both the snapshot and the sticky note on the folder. Multimodal Foundry capabilities are built for that mixed input; if you pick a speech path, you're using an audio-focused route and you'll still miss the joint analysis you need.
Full Explanation
A public-health workflow that must analyze clinic photos together with clinician text notes is a multimodal civic workload. The correct Foundry choice is a multimodal model or Foundry Tools path that accepts image and text inputs together so visual evidence and written notes are interpreted in one solution. Planning modality to match mixed clinical inputs prevents discarding half of the case file before analysis begins. A multimodal Foundry embedding model that accepts image and text inputs together for analysis fails because it still optimizes for retrieval rather than analysis; it creates searchable vectors for finding similar cases instead of interpreting the photo and note together in one workflow. A multimodal Foundry speech path that accepts image and text inputs together for analysis fails because speech services are built for audio transcription and synthesis rather than vision-language interpretation; it does not perform the joint analysis of clinic photos with clinician notes the clinical workflow requires. A multimodal Foundry agent path that accepts image and text inputs together for analysis fails because agent orchestration coordinates multi-step actions rather than delivering direct multimodal interpretation; it adds coordination overhead instead of analyzing visual evidence with written notes in one solution. Exam caveat: multimodal capability does not replace privacy, PHI handling, or human clinical judgment—Foundry planning still sits under health-data controls. Operational check: submit a paired sample (photo + note), confirm both modalities influence the output, measure cost/latency versus a text-only baseline, and document when cases must escalate to a clinician rather than automated interpretation.
Prefer to study offline? Printable PDF study book + test engine ($7.50, unofficial). These questions stay free here.