
A quality engineering team at Contoso needs to validate their Copilot Studio agent against 200 predefined test utterances every time a new version is deployed to the Test environment. Running each utterance manually through the Test pane is too time-consuming. The team wants an automated, repeatable testing approach that can flag regressions when topic behavior changes between deployments. Which approach best meets this requirement?
Select an answer to reveal the explanation.
Short Explanation
Automating 200 utterances is like running a spell-checker instead of proofreading a novel word by word. You can fire all your test phrases at the agent programmatically with the bulk testing feature or a Direct Line test harness, then compare triggered topics and responses to expected outcomes. You'll get a regression report in minutes instead of hours.
Full Explanation
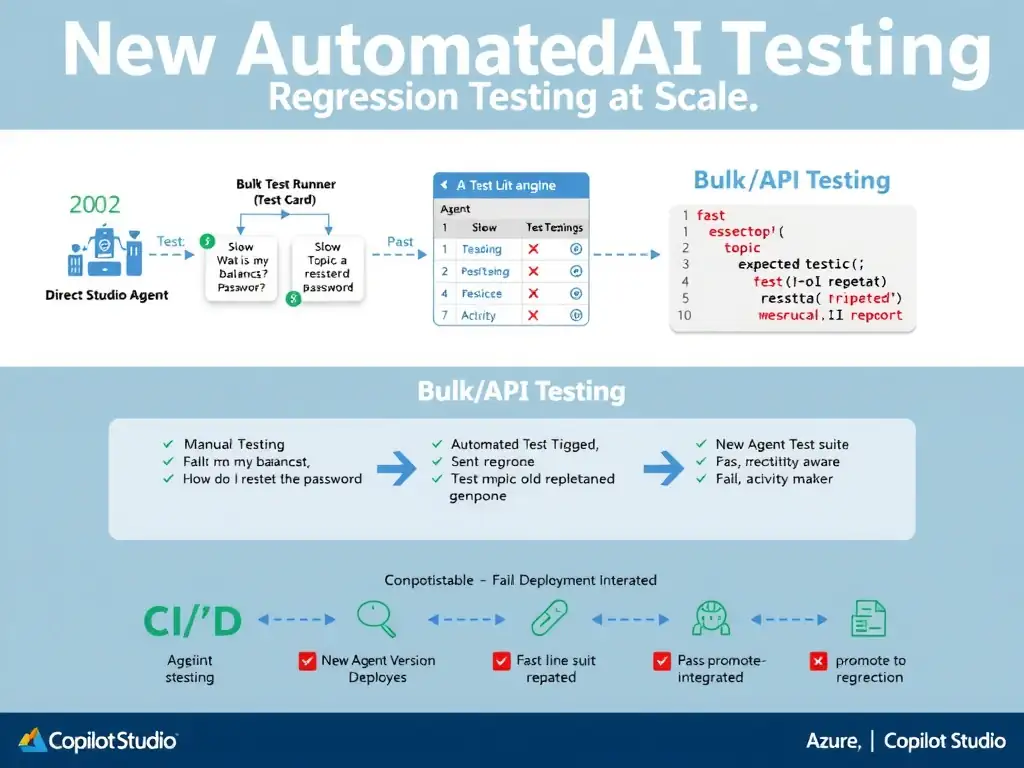
For regression testing of AI agents at scale, manual execution through the Test pane does not scale. The best approach is to use the Copilot Studio bulk testing feature or the Direct Line API with a test harness to send all 200 utterances programmatically and evaluate the responses.
Copilot Studio supports test sets — collections of predefined utterances with expected topic mappings — that can be run automatically against an agent to verify that each utterance triggers the correct topic. This feature is designed specifically for regression testing and generates a pass/fail report for each test case.
The Copilot Studio Direct Line channel exposes a REST API that allows external systems to send messages to the agent and receive responses programmatically. A test automation script (in Python, C#, or any language) can send all 200 utterances, capture the agent's response and triggered topic, and compare against expected outcomes. This is useful when teams need more sophisticated assertion logic than the built-in test sets provide.
The approach that enables conversation transcripts in the Analytics section and compares transcript exports between deployments manually is incorrect. This approach is still manual, time-consuming, and prone to human error. It does not scale to 200 utterances and does not provide automated regression detection.
The approach that hires additional testers to run the 200 utterances through the Test pane in parallel sessions is incorrect. Adding people to a manual process does not make it automated or repeatable. It also increases cost without solving the scalability or consistency problem.
The approach that configures a Power Automate flow to send random sample utterances to the agent once per day and log the responses in SharePoint is incorrect. Random sampling does not provide systematic coverage of all 200 test cases. Running samples once per day is not deployment-triggered regression testing. This approach would miss regressions on specific utterances that are not sampled.
For the AB-620 exam: automated AI testing is increasingly important as agents scale. Know that Copilot Studio supports test sets for bulk utterance testing, and that the Direct Line API is the mechanism for external integration-based testing. The exam may also reference Azure AI Foundry evaluation pipelines as the tool for automated groundedness and relevance scoring at scale.