
A Copilot Studio agent provides HR policy answers from an Azure AI Search index. The index contains documents tagged with a 'department' field. During a conversation, the agent collects the user's department from their Azure AD profile. The developer wants search results to be automatically scoped to the user's department. However, when testing, results from all departments appear regardless of the user's department. What must be done to enable per-user department filtering?
Select an answer to reveal the explanation.
Short Explanation
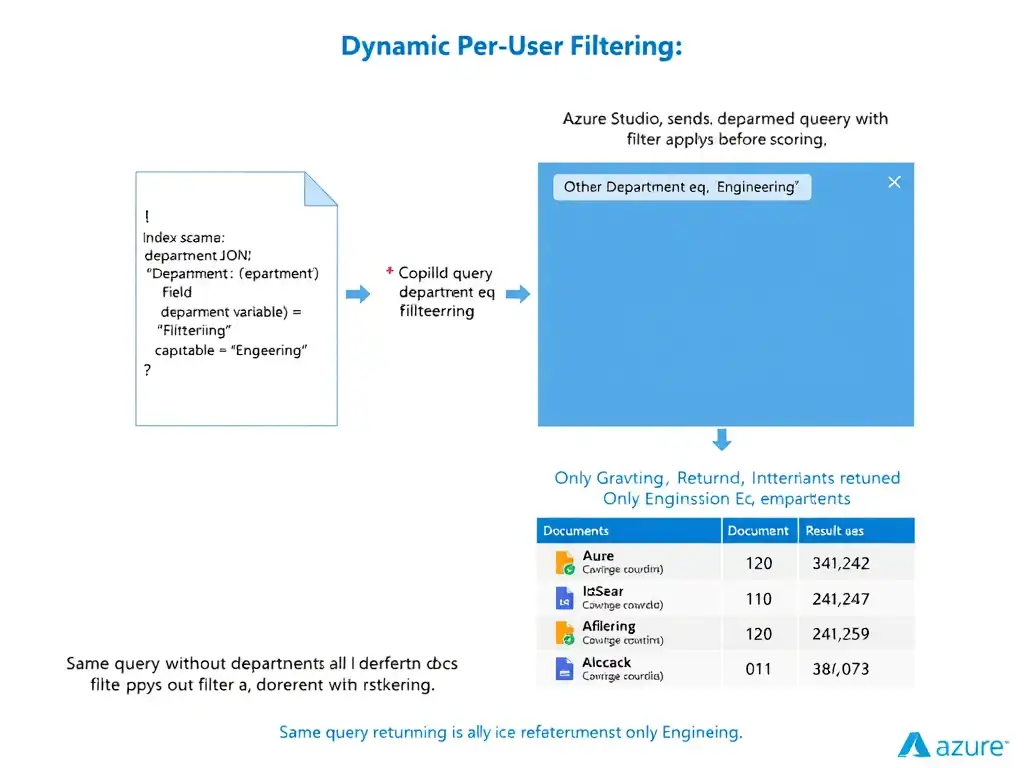
Filterable fields are the switches that make Azure AI Search query-time dynamic. Once you flip the 'filterable' switch on the department field, you can pass an OData filter with the user's department on every search call. That scopes results per user without separate indexes or post-processing.
Full Explanation
Azure AI Search supports field-level filtering through OData filter expressions, but a field must be declared as 'filterable: true' in the index schema before it can be used in filter expressions. This is an index-design decision that must be made when the index is created or updated. If the 'department' field is not filterable, any filter expression referencing it will be ignored or rejected. Once the field is filterable, the Copilot Studio knowledge source configuration or the Power Automate flow calling the search API can include a filter expression like 'department eq Engineering'. In an agent scenario where the department comes from the user's Azure AD profile, collected via authentication, the developer would capture this as a conversation variable and pass it dynamically to the search call, making the filter personalized per user. The separate-index approach is incorrect because maintaining a separate Azure AI Search index for each department is operationally expensive and fragile. Any schema changes require updates across all indices, and adding a new department requires creating a new index. The filterable field approach handles any number of departments with a single index. The row-level-security approach is incorrect because Azure AI Search does not have a native row-level security feature integrated with Azure AD group membership. While document-level access control can be implemented by storing user or group identifiers in index fields and filtering on them, this is a custom implementation pattern, not a built-in row-level security toggle. Additionally, even with such a pattern, the 'filterable' field requirement still applies. The post-processing flow approach is incorrect because receiving all search results in Power Automate and removing nonmatching documents is inefficient. Irrelevant documents are retrieved, transferred, and processed unnecessarily. Filtering at the search layer before retrieval is far more performant and is the architecturally correct approach. Exam tip: Two-step: make the field filterable in the index definition, then pass the filter at query time. Missing either step means filtering won't work. Index schema changes require re-indexing the data source.