
A public web agent for product FAQs must reduce harmful or abusive user inputs and unsafe model outputs. Which statement best reflects a responsible configuration approach?
Select an answer to reveal the explanation.
Short Explanation
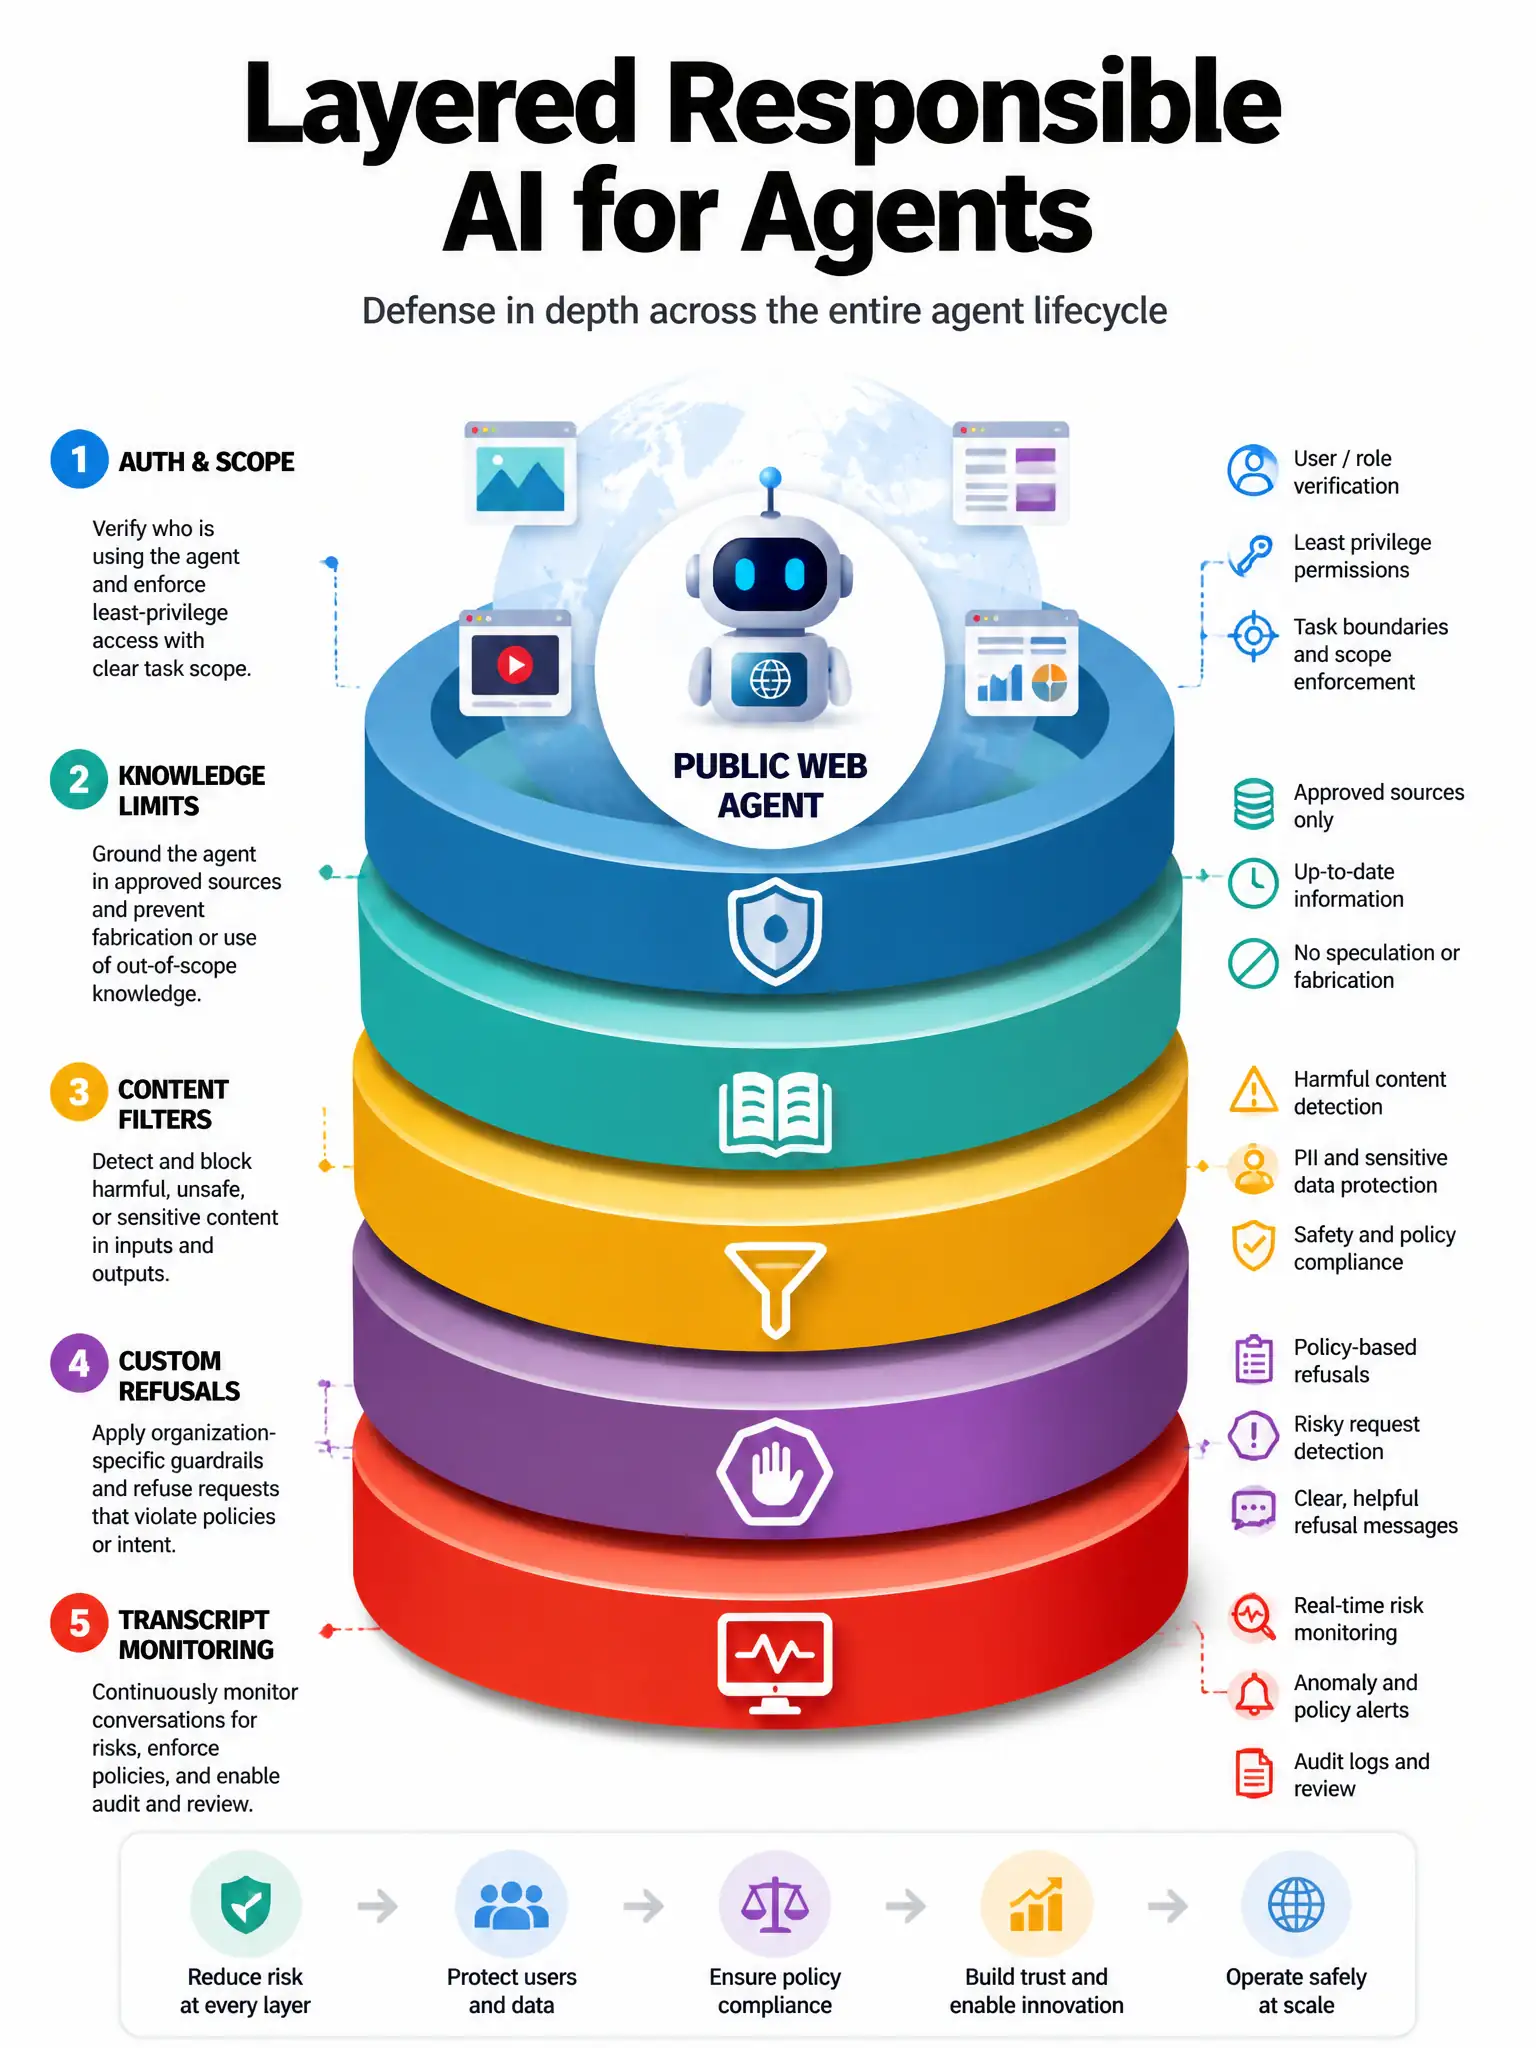
You need to stack defenses: use content filters, keep the knowledge scoped, make refusals clear, and monitor transcripts for abuse. Turning off guardrails just invites trouble.
Full Explanation
Responsible AI for agents is multi-layered: technical filters, grounding scope, instructional refusals, access control, and operational monitoring. Combining moderation/filters, scoped knowledge, clear refusals, and transcript monitoring is correct. Disabling filters for engagement removes safety. Publishing admin credentials breaks access control. Offline FAQs with no monitoring wrongly assumes web agents cannot be governed. Exam: expect transparency, privacy, human oversight, and content safety.