
Yuki is a knowledge engineer at Cedarwood Research Institute. The institute's Copilot Studio agent queries an Azure AI Search index built from 800-page technical research reports. Users report that the agent's answers are vague and sometimes combine unrelated information from different sections of the same report. The index currently stores each full document as a single record with one searchable text field. What should Yuki do to improve the agent's answer quality?
Select an answer to reveal the explanation.
Short Explanation
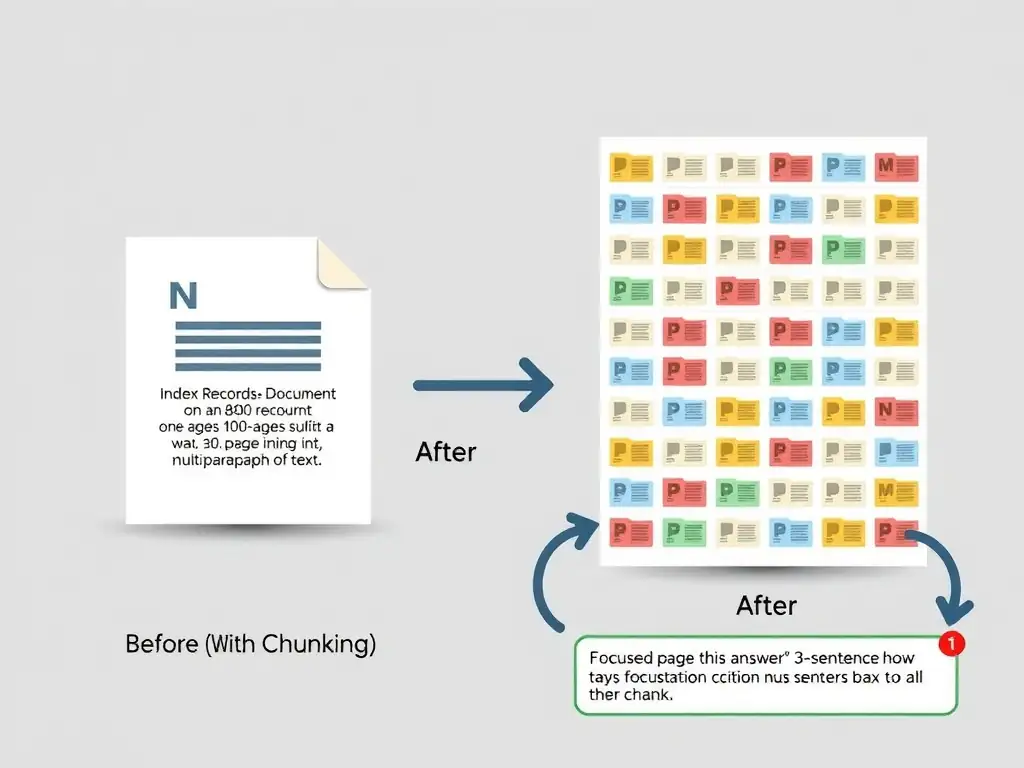
You’re storing an 800-page report as one giant record, so the agent gets a whole book when it needs one paragraph. Chunk the reports into smaller overlapping segments before indexing so each result is focused and the answer can be precise.
Full Explanation
When large documents are indexed as single records, retrieval-augmented generation (RAG) systems like Copilot Studio's knowledge search face a fundamental problem: the entire document is returned as a match, but only a small section is relevant. The language model must then synthesize an answer from thousands of tokens of mixed content, which degrades quality and coherence.
The correct approach is to implement a chunking strategy that splits each 800-page document into smaller overlapping segments before indexing, such as 512-token chunks with 50-token overlap, so each chunk is a separate, focused search result that the agent can return as a precise answer. Chunking splits each document into smaller, semantically coherent segments before indexing. Common chunking strategies include fixed-size character or token windows with overlap, such as 512 tokens per chunk with 50-token overlap between adjacent chunks to preserve context at boundaries, sentence-level splitting, or paragraph-level splitting. Each chunk becomes its own index record. When the agent queries the index, it retrieves the specific chunk or chunks relevant to the question rather than the full document, producing more precise answers.
The semantic ranker approach is incorrect. The semantic ranker re-orders search results by relevance but cannot extract a relevant sub-section from within a single large document record. If the document is stored as one record, the ranker can move it up or down the result list but cannot isolate the relevant passage. That is a retrieval problem, not a ranking problem.
The Storage Optimized L2 tier approach is incorrect. The Storage Optimized L2 tier provides larger index storage capacity and higher document counts for very large indexes, but it does not improve the agent's ability to extract precise answers from large documents. The problem here is index design, not storage capacity.
The custom scoring profile approach is incorrect. Boosting longer documents would make the problem worse, not better. A scoring profile that favors longer content would push 800-page reports to the top of results when shorter, more focused chunks would be more useful. Scoring profiles tune retrieval order, not answer quality within retrieved documents.
Exam caveat: Chunking strategy is a critical knowledge base design decision for AI Search-backed agents. Expect AB-620 to test whether you know that large documents need to be chunked before indexing to enable precise, grounded answers. Overlap between chunks is important to avoid losing context at chunk boundaries.