
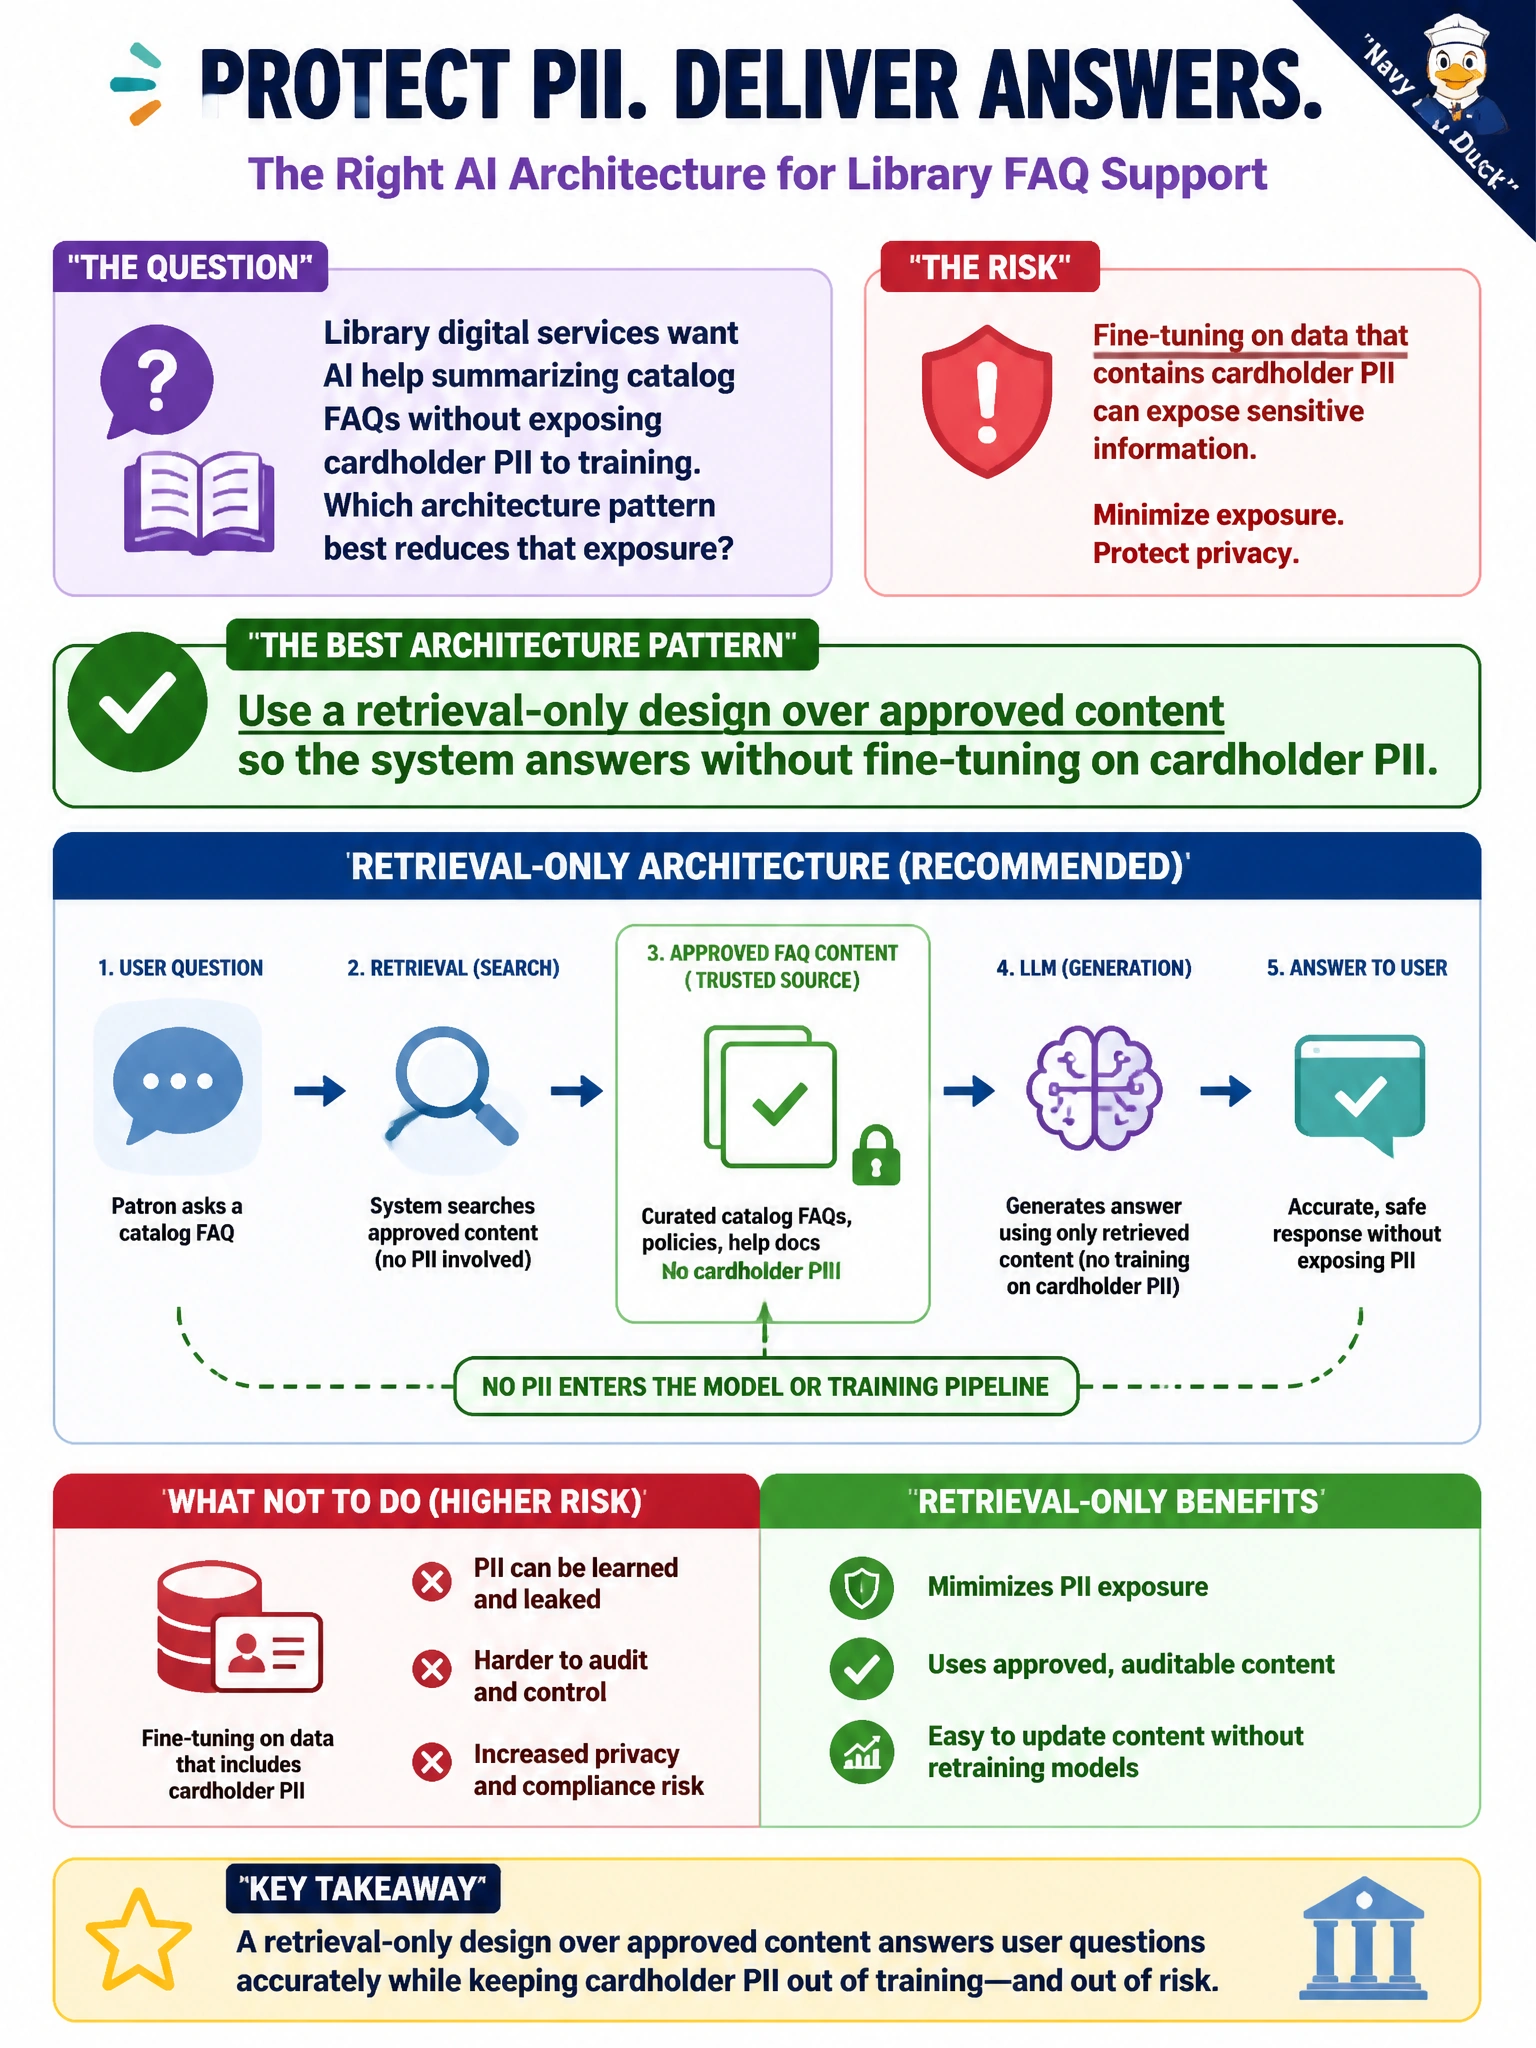
Library digital services want AI help summarizing catalog FAQs without exposing cardholder PII to training. Which architecture pattern best reduces that exposure?
Select an answer to reveal the explanation.
Short Explanation
Prefer search-and-answer over baking patron lives into the model. You'll still spread PII if you're fine-tuning on anonymized transcripts with recoverable patron keys for tone and building a vector index linked to session histories. Hosting it in a private VPC with logging and encryption won't fix it if it's still learning continuously on chat history.
Full Explanation
Hosting the summarizer in a private VPC with access logging and encrypted storage for continuous learning on chat history fails because VPC isolation, logging, and encryption do not prevent training-time exposure when chat history containing cardholder PII is still used for learning. A retrieval-only design over approved content lets the system answer from curated FAQ and catalog materials without fine-tuning on cardholder PII, which sharply reduces training-time exposure, retention of patron behavior in model parameters, and the chance that personalization leaks across users. That architecture pattern matches privacy-preserving municipal library AI goals while still delivering useful summaries.
Fine-tuning a catalog summarizer on anonymized transcripts indexed with recoverable patron keys for tone fails because recoverable keys mean the data is only pseudonymized and still re-identifiable, so it trains on cardholder PII and embeds it into model state where deletion, purpose limitation, and access control are hardest. Building a vector index of past patron questions linked to session histories to enrich FAQ summary context over time fails because it keeps cardholder-linked queries and behavior in retrieval data, creating retention and re-identification risks instead of answering retrieval-only from approved content.
Exam caveat: Prefer retrieval-over-approved-content patterns when the stem emphasizes avoiding PII in training; fine-tuning a catalog summarizer on anonymized transcripts indexed with recoverable patron keys for tone is the privacy-breaking distractor.
Operational check: Index only approved FAQ/catalog sources, block cardholder PII from training corpora, keep filters on policy answers, and document that the assistant is retrieval-grounded rather than fine-tuned on anonymized transcripts indexed with recoverable patron keys.
Prefer to study offline? Printable PDF study book + test engine ($7.50, unofficial). These questions stay free here.