
A risk committee is evaluating whether to deploy an AI system for automated debt collection communications. The system was trained primarily on historical communications from accounts that were successfully resolved. What dataset bias risk does this create?
Select an answer to reveal the explanation.
Short Explanation
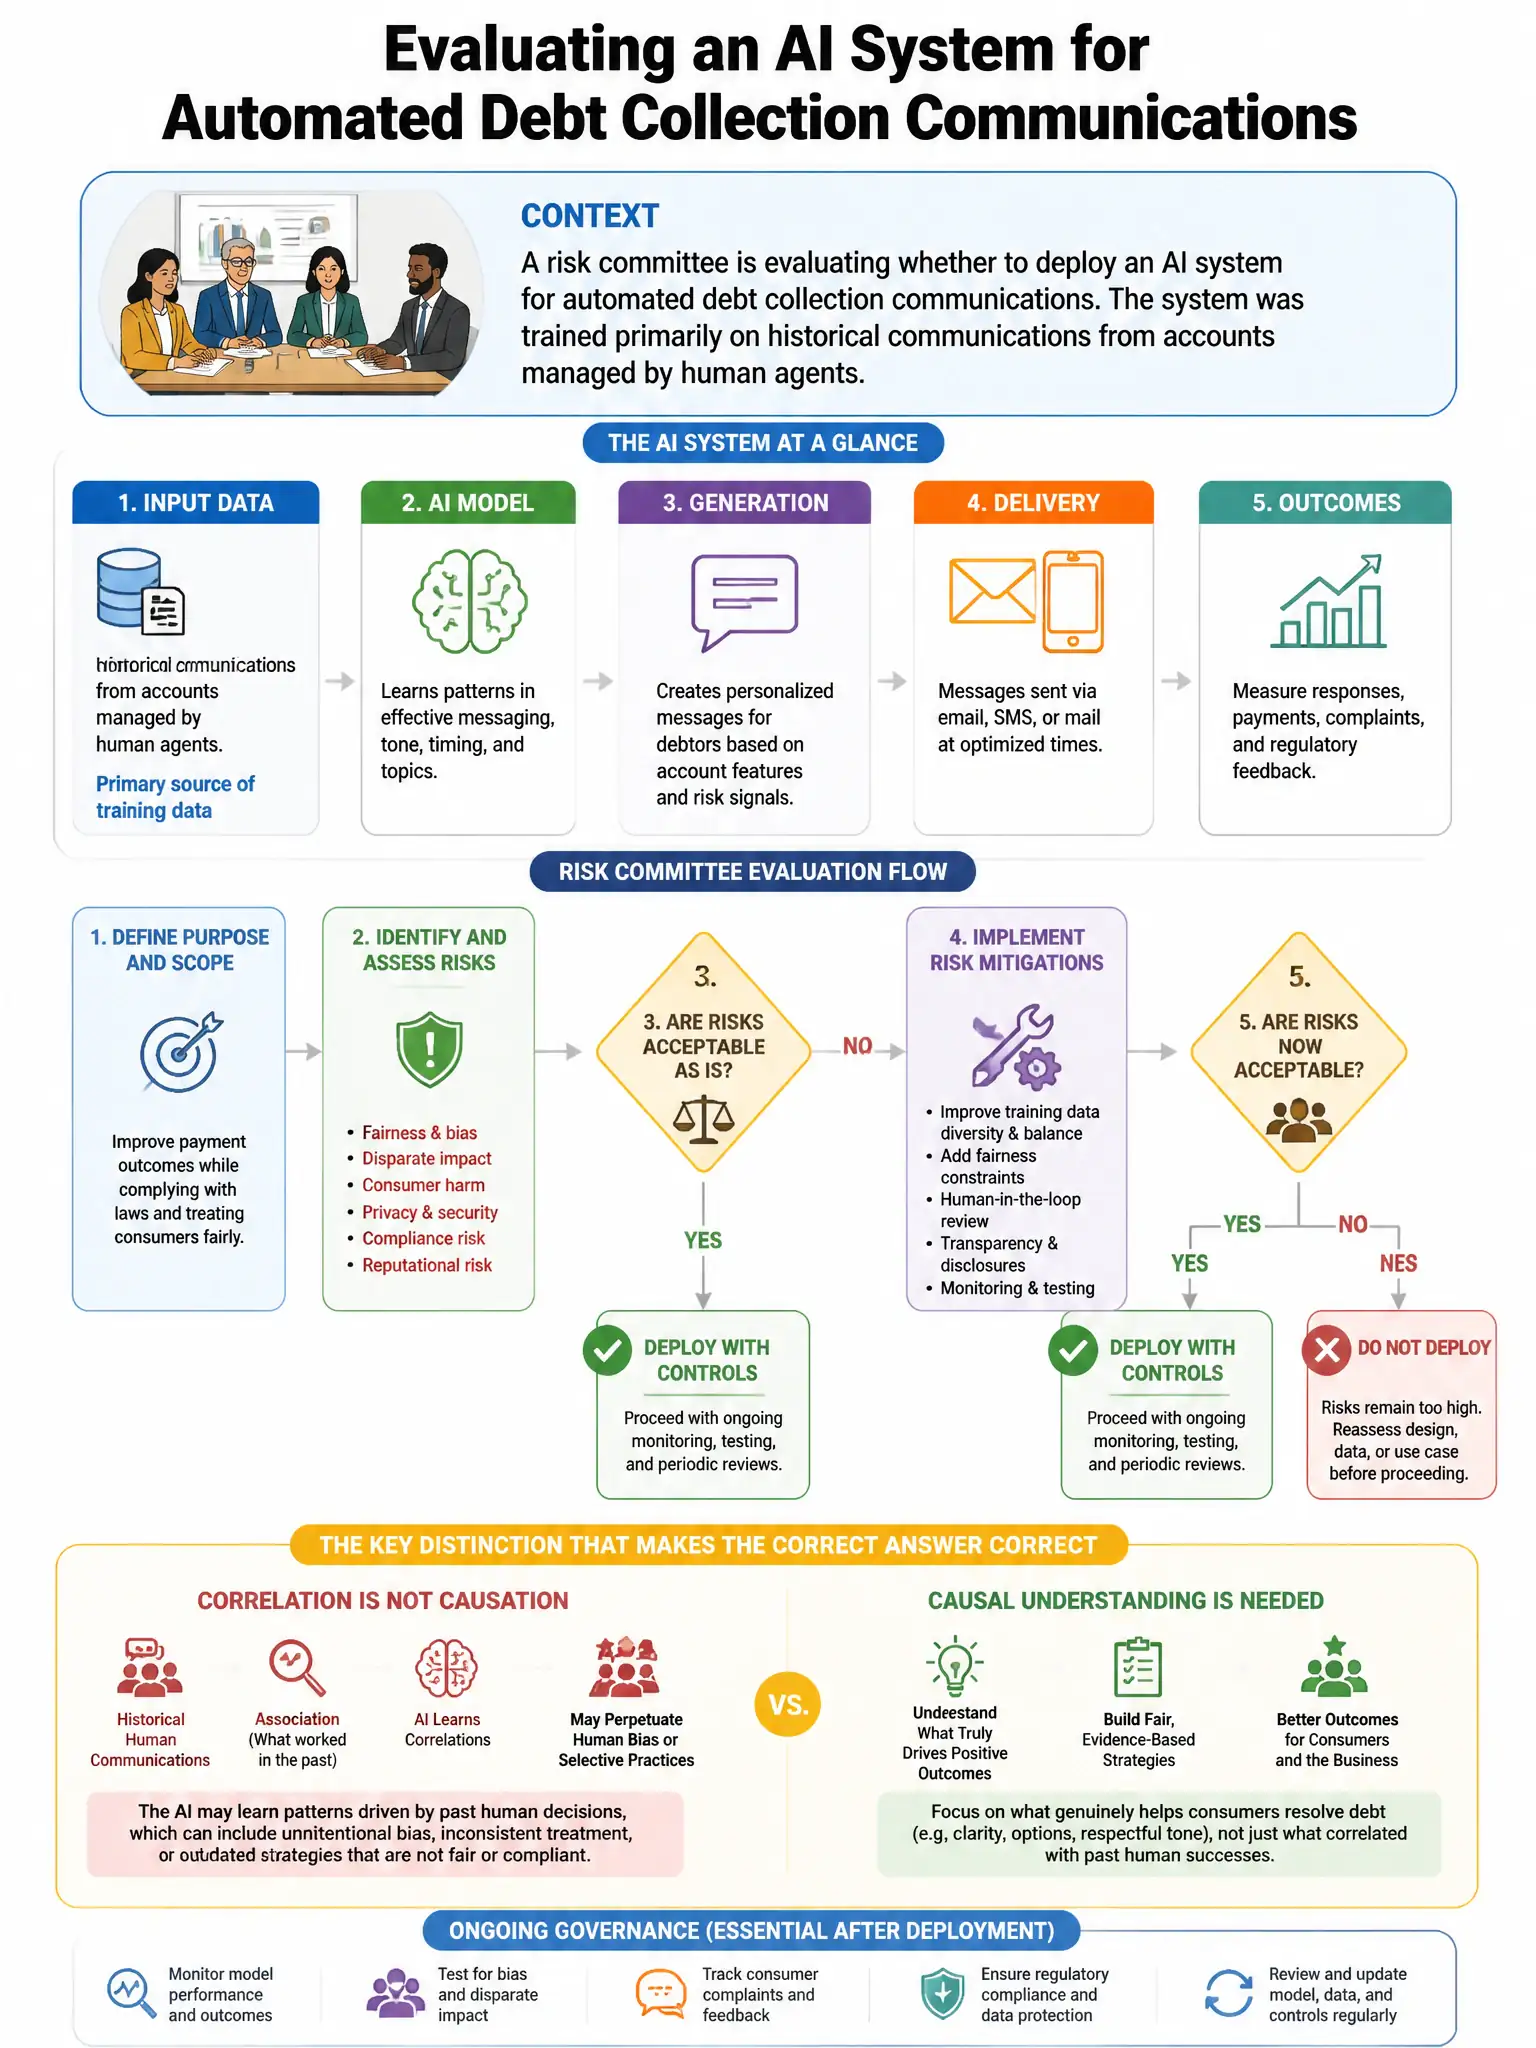
Here's the deal — training only on accounts that were successfully resolved creates survivorship bias, so the model learns what worked when collection succeeded but misses what's needed for harder accounts. That's why the overrepresentation of successful cases is the right answer.
Full Explanation
Training exclusively on successfully resolved accounts creates survivorship bias — the model learns what worked for cases where collection succeeded but has no exposure to accounts where standard approaches failed, potentially rendering it less effective for harder collections. The option about using too small a dataset relative to the total population of accounts is a volume concern, not the specific bias type. The option about data scientists preferring certain communication styles is a human cognitive bias in development, not a dataset bias. The option about excluding accounts opened after the training data cutoff date is a temporal generalization concern, not the primary bias identified.