
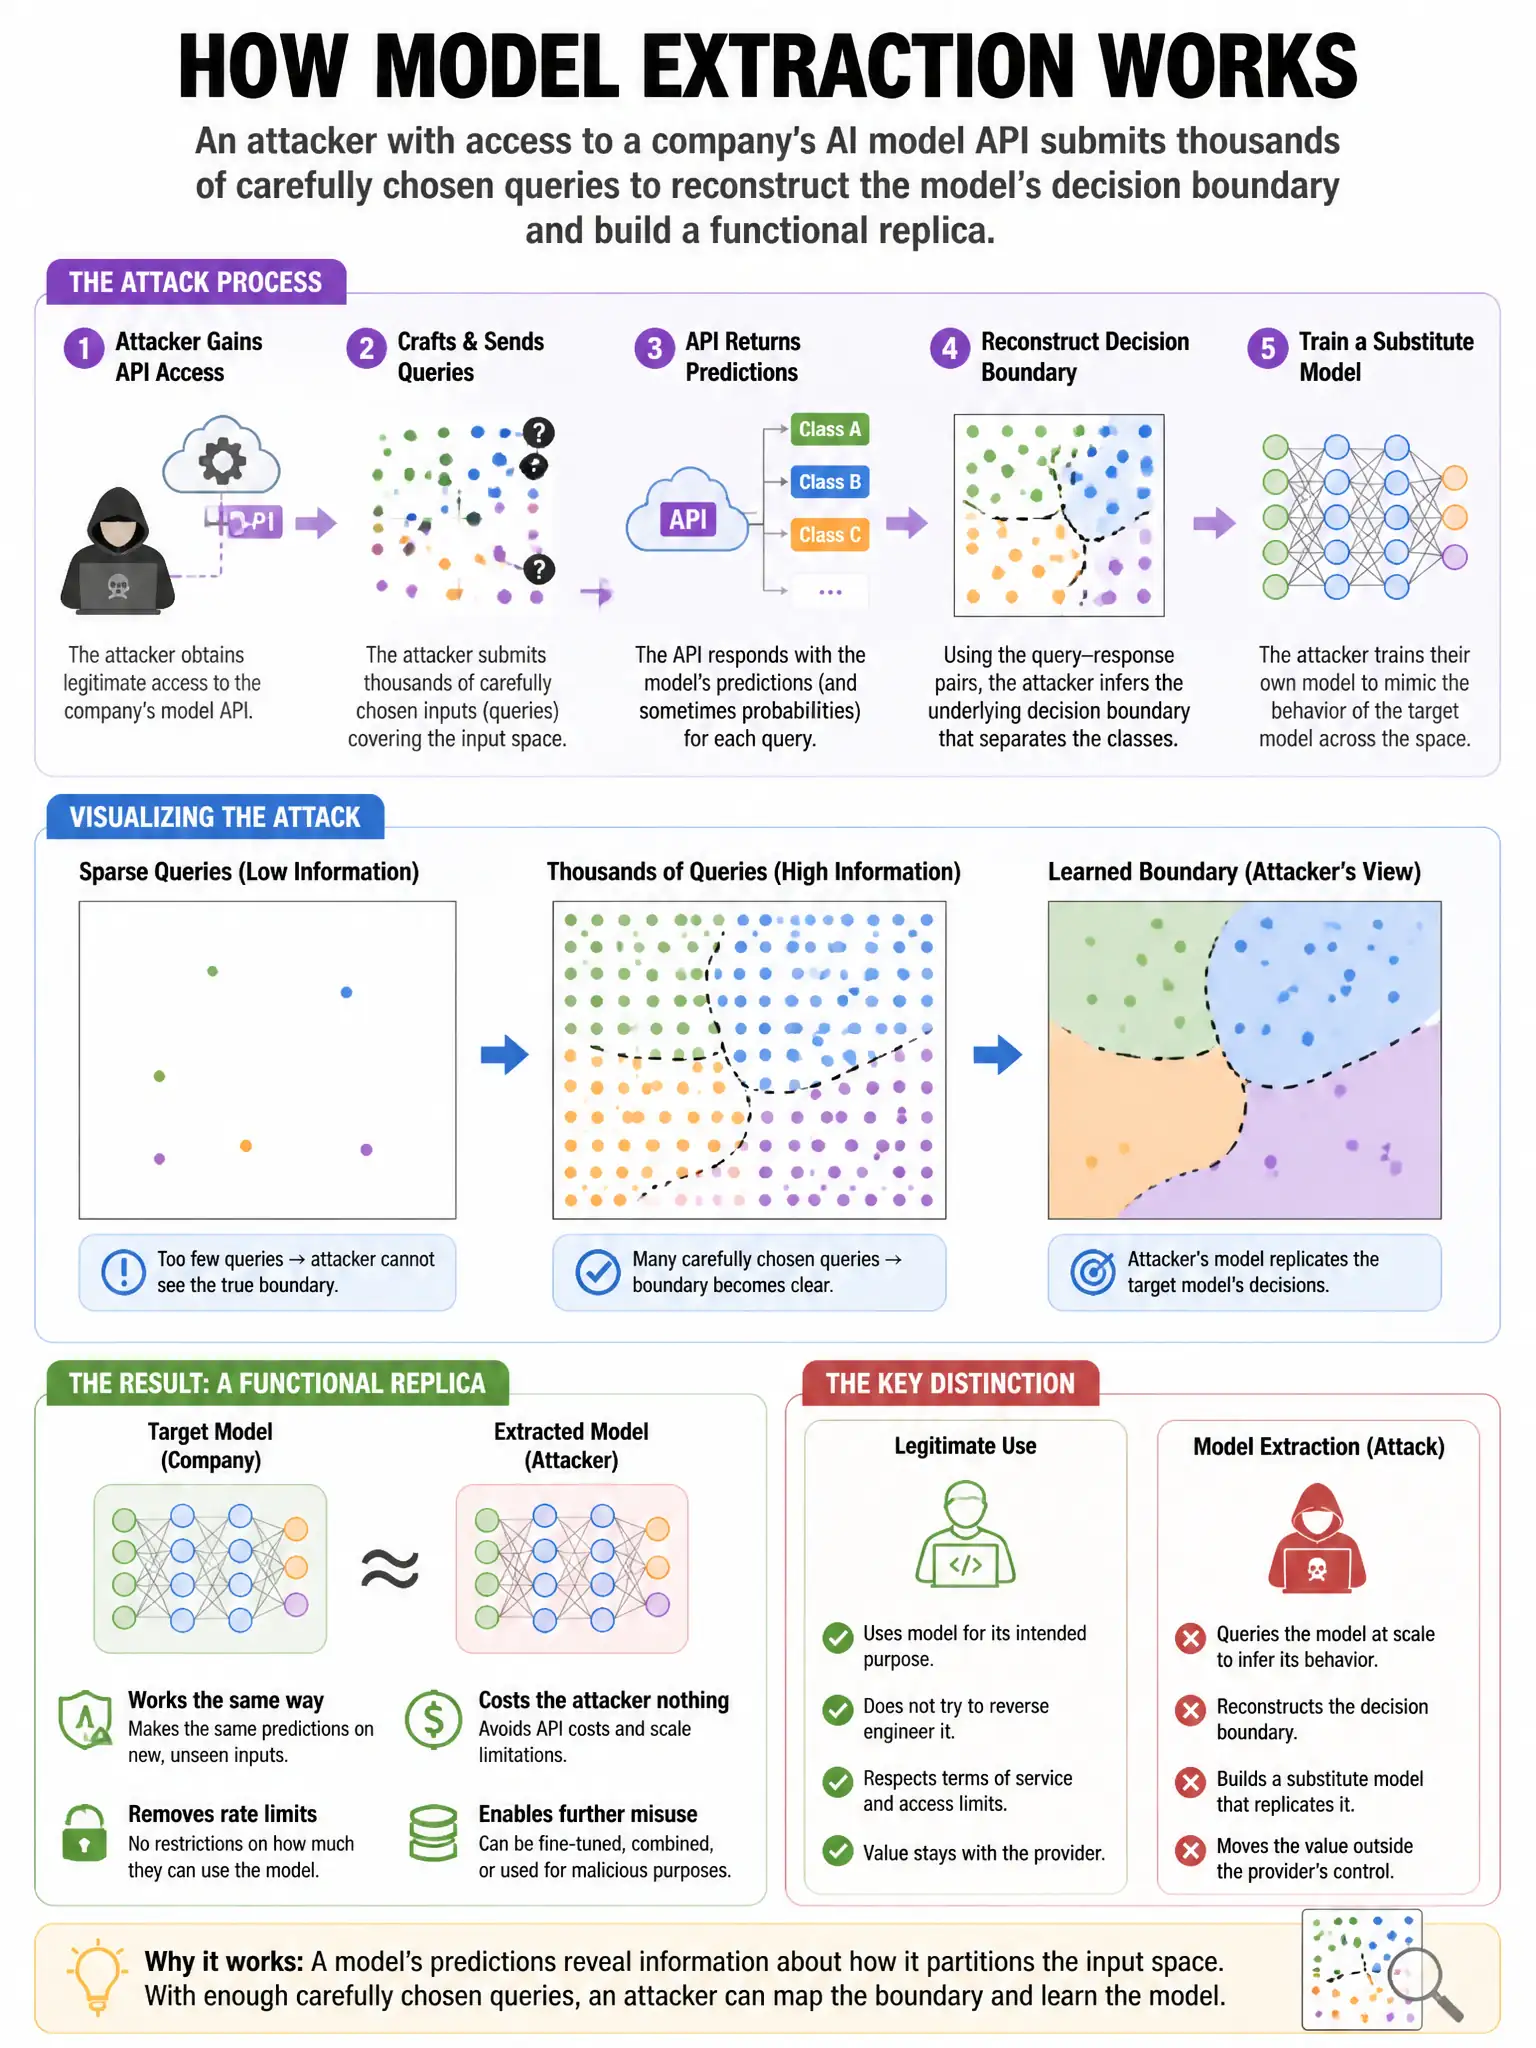
An attacker with access to a company's AI model API submits thousands of carefully chosen queries to reconstruct the model's decision boundary and build a functional replica. Which attack type is this?
Select an answer to reveal the explanation.
Short Explanation
Here's the deal — you're describing a model extraction attack, where you hammer a model's API with crafted queries to rebuild its decision boundary and clone its behavior. That steals the model and lets you keep attacking it without needing the original API. The other options don't fit: poisoning corrupts training data, membership inference checks if data was used, and gradient leakage pulls training data from gradients.
Full Explanation
Model extraction, also called model stealing, is right because querying an API to reconstruct the decision boundary and build a surrogate steals the model and enables later attacks without API access. Data poisoning corrupts training data. Membership inference only checks whether a record was in the training set. Gradient leakage reconstructs training data from gradients, usually in federated learning.