
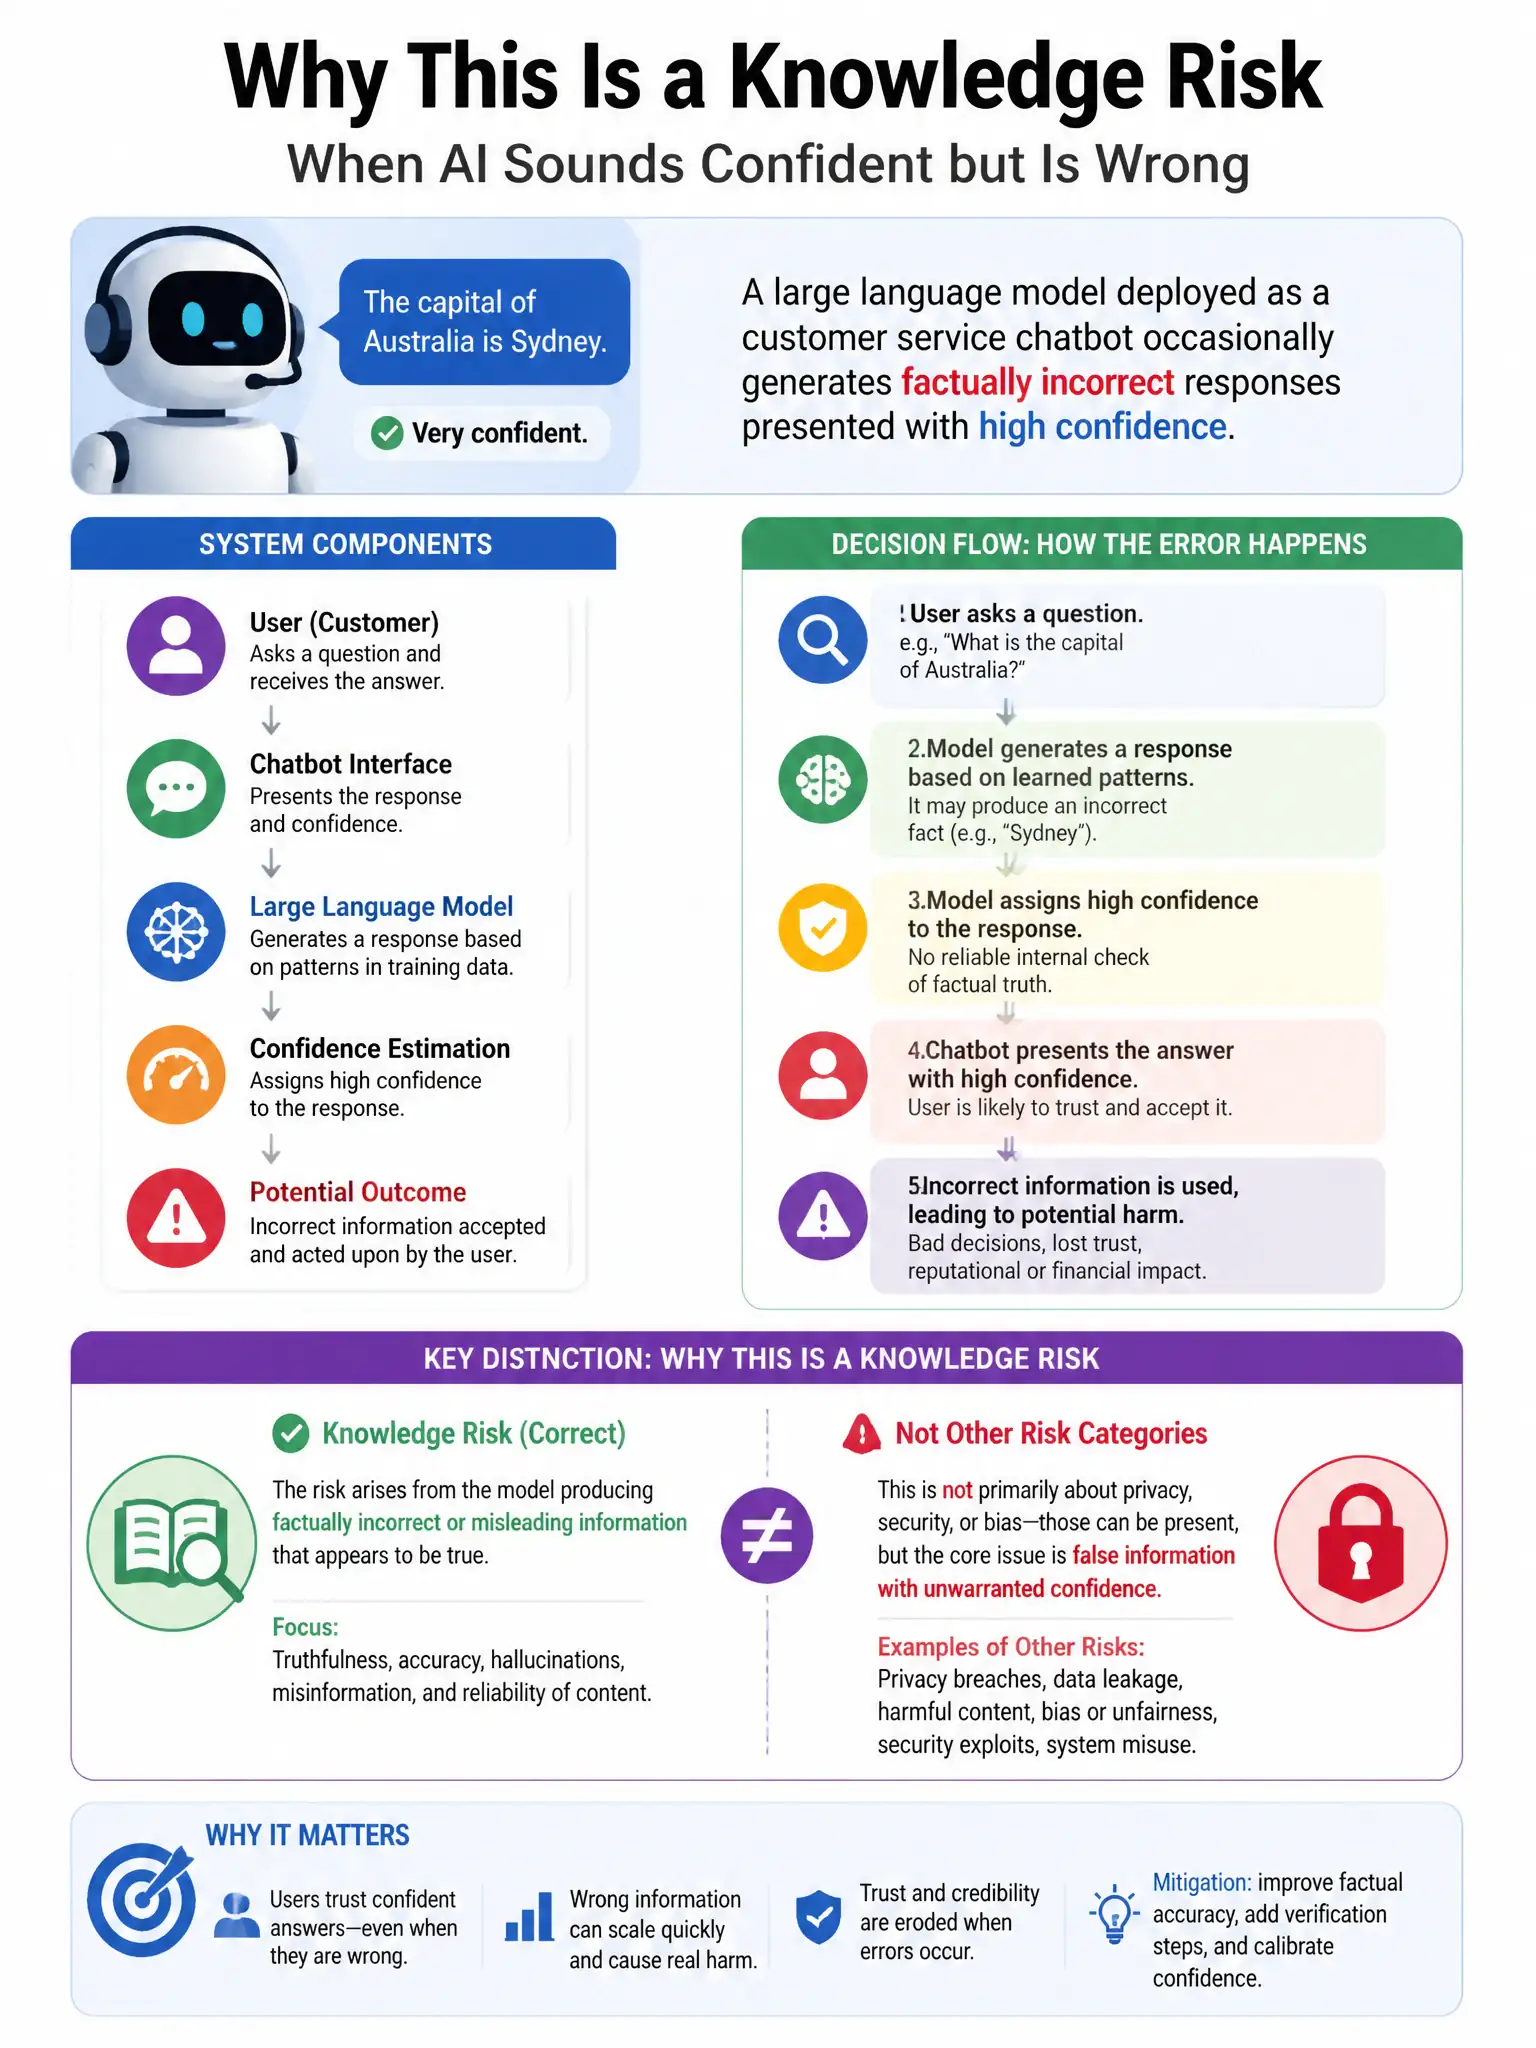
A large language model deployed as a customer service chatbot occasionally generates factually incorrect responses presented with high confidence. Which emerging AI risk category does this BEST represent?
Select an answer to reveal the explanation.
Short Explanation
You're dealing with hallucination because the chatbot is confidently making up fluent but wrong answers. That's a core LLM risk in customer-facing use, not an attack or privacy leak.
Full Explanation
Hallucination — generating plausible but factually incorrect content — is correct because large language models can produce confident, fluent, but false or fabricated answers, a distinct risk in customer-facing LLM deployments. Prompt injection via user-supplied inputs is an attack vector. Model extraction through repeated API queries is model theft. Training data memorization revealing personally identifiable information is a privacy risk from memorization.