
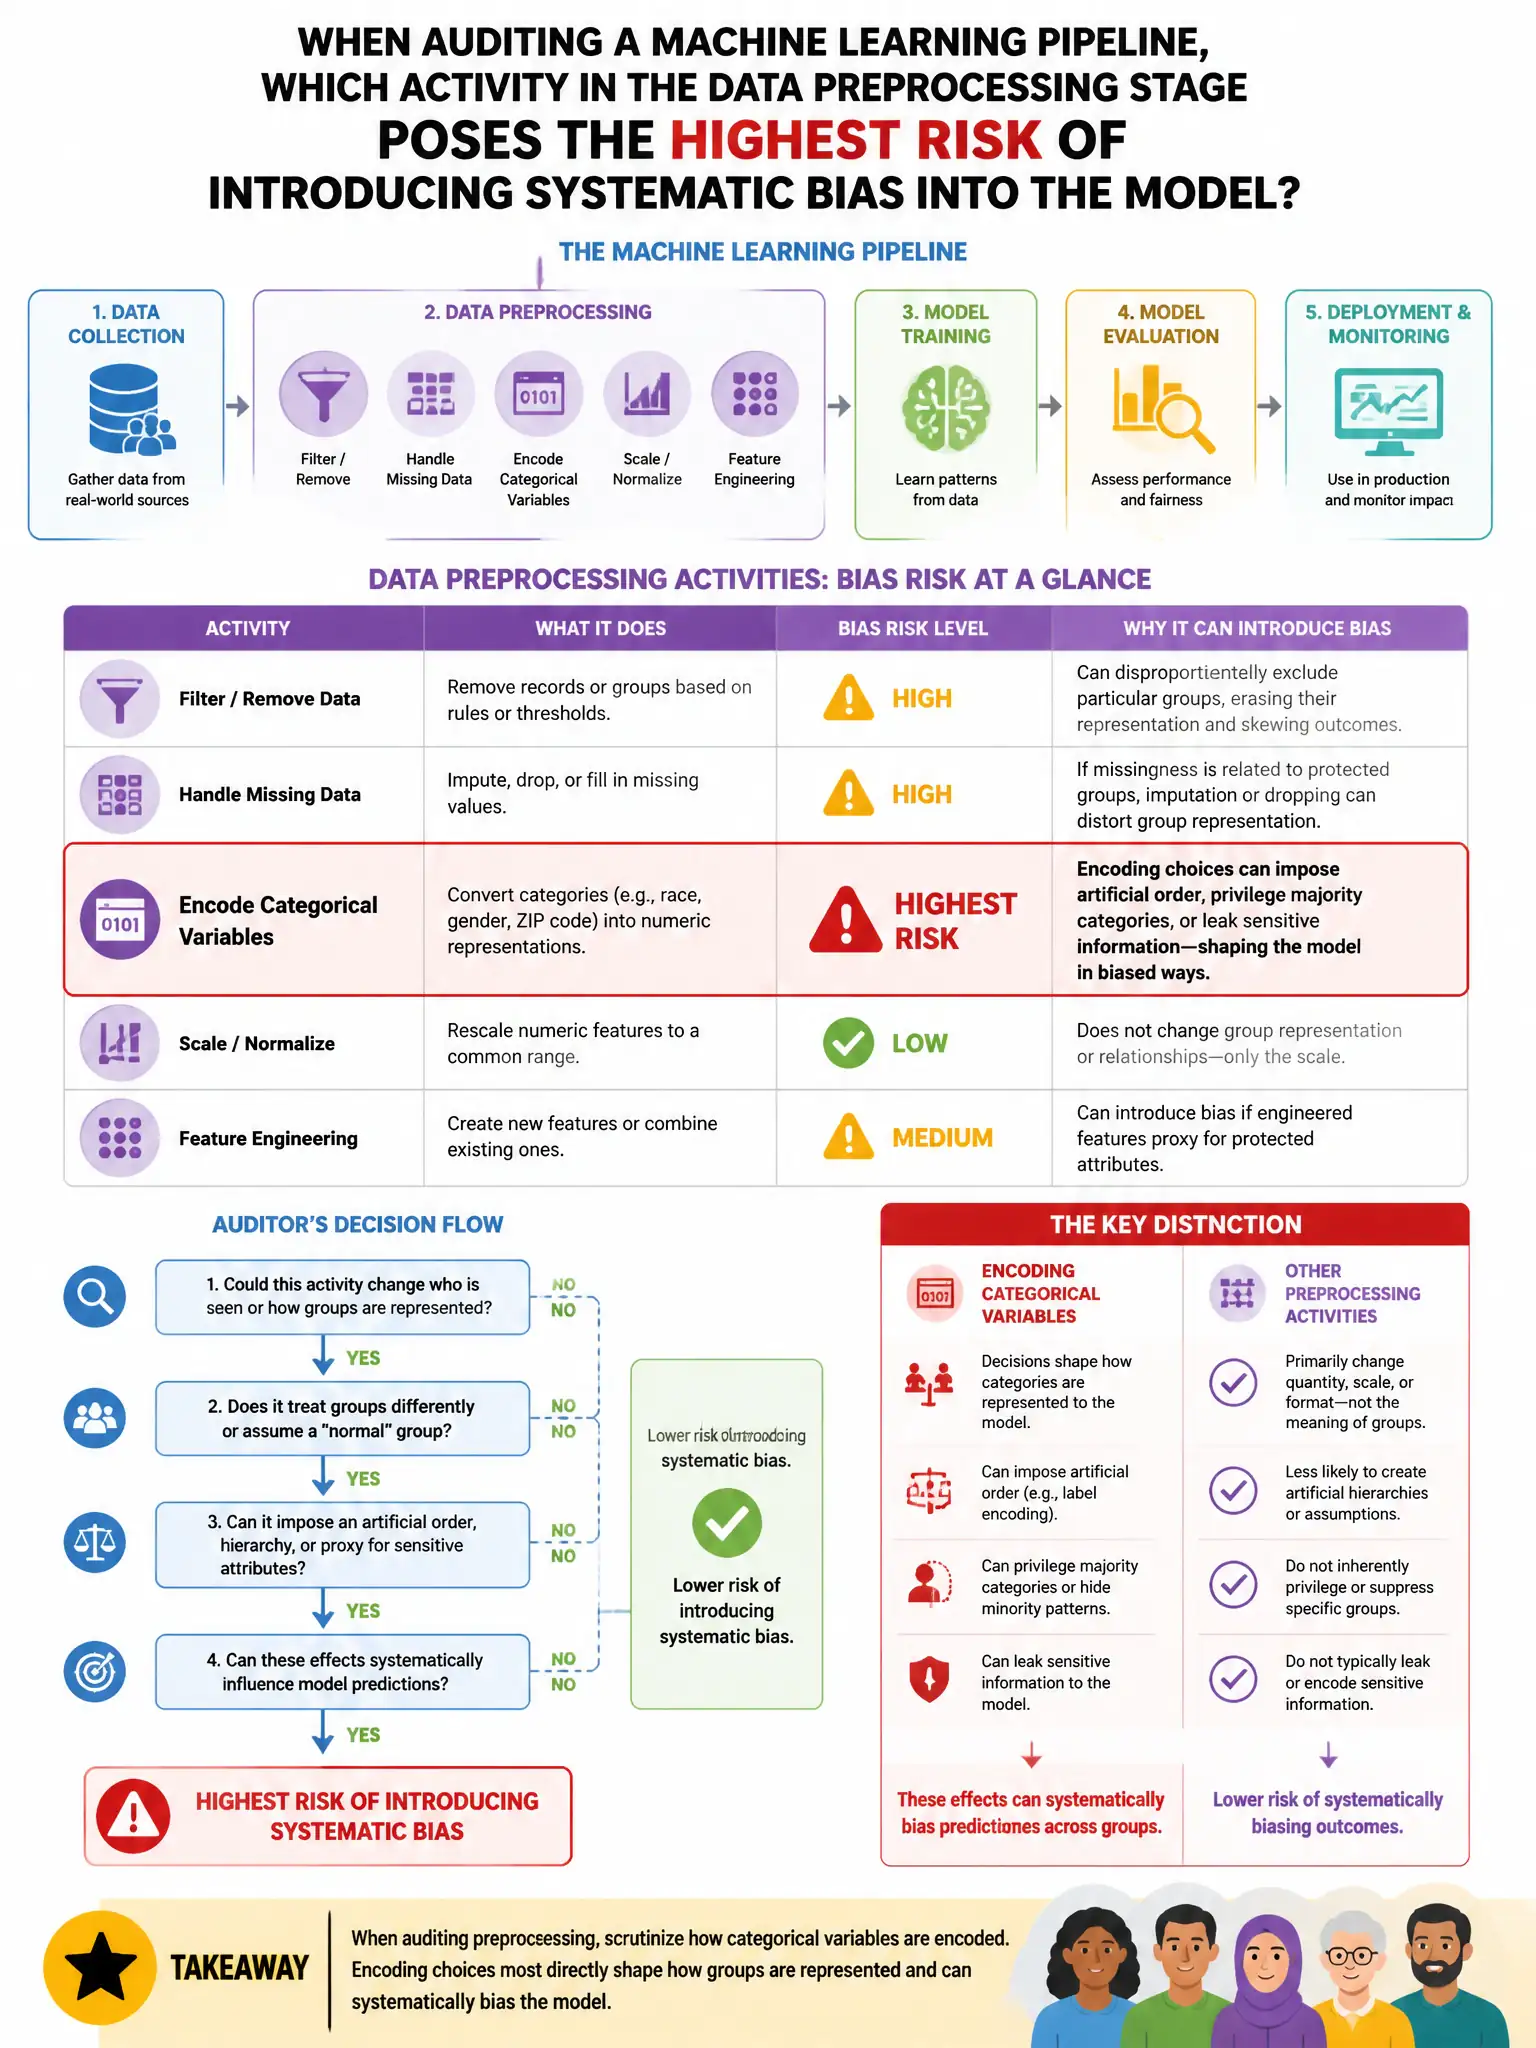
When auditing a machine learning pipeline, which activity in the data preprocessing stage poses the HIGHEST risk of introducing systematic bias into the model?
Select an answer to reveal the explanation.
Short Explanation
Imputing missing values using the mean of a majority demographic group is the highest-risk activity because it systematically underrepresents minority group characteristics. That embeds structural bias into the training data, and the model can learn and propagate that bias.
Full Explanation
Imputing missing values using the mean of a majority demographic group is correct because it systematically underrepresents minority group characteristics, embedding structural bias into the training data that propagates through model training. Normalizing continuous variables to a 0-1 range and encoding categorical variables using one-hot encoding are standard preprocessing steps that do not inherently introduce bias. Removing duplicate records from the training dataset generally improves data quality.