
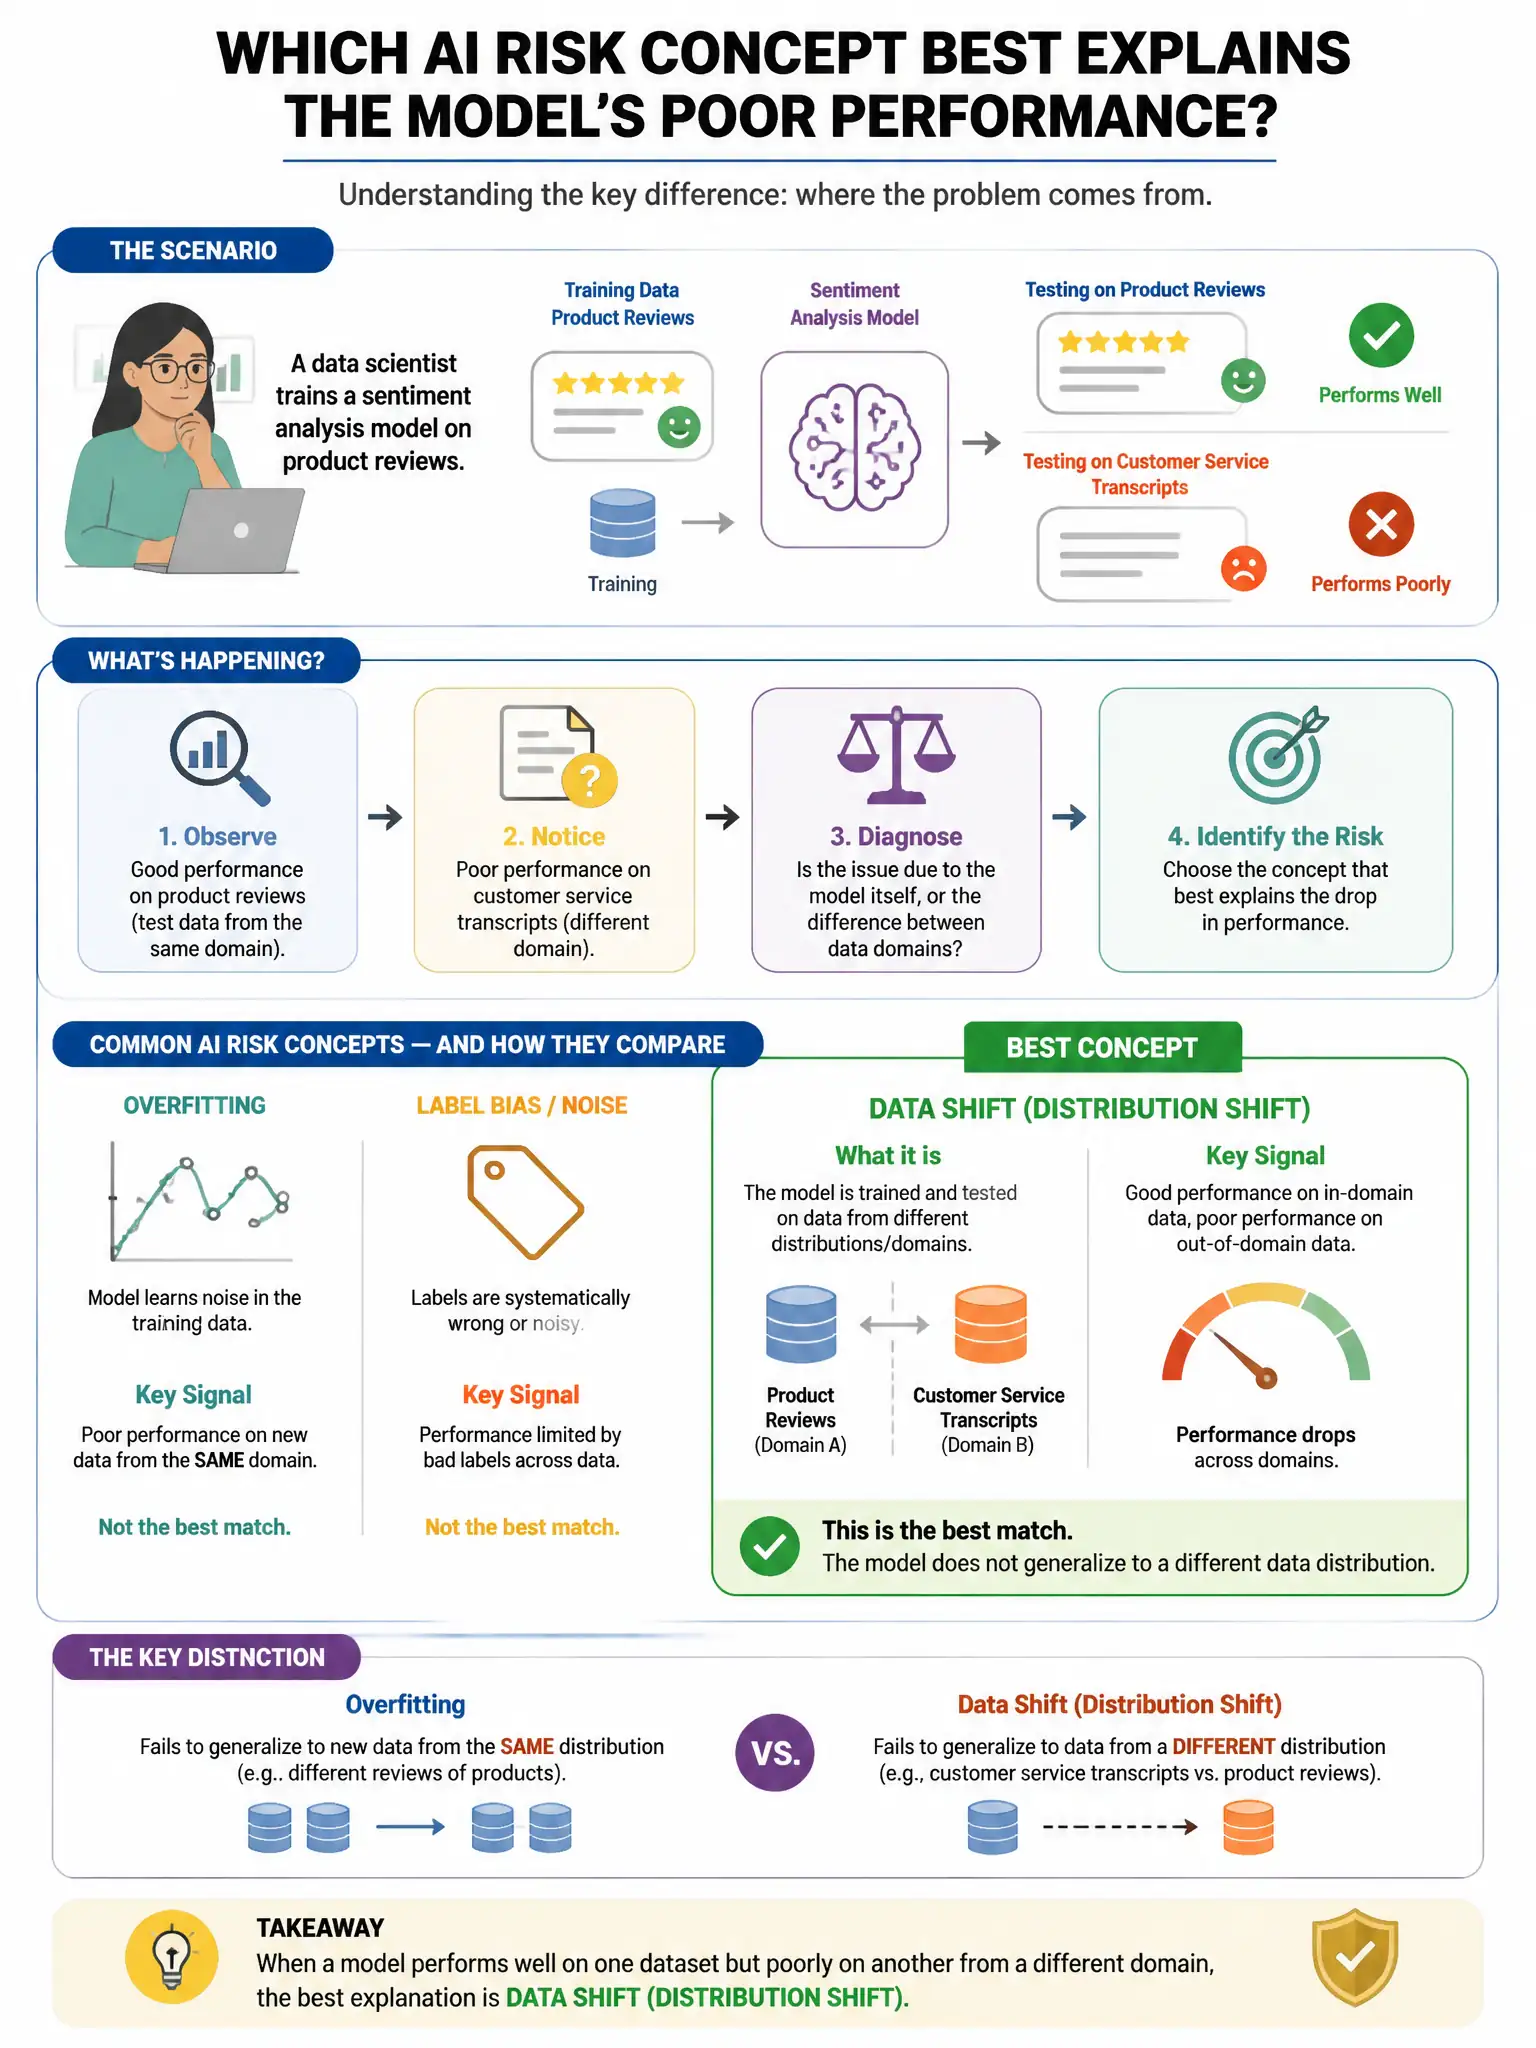
A data scientist notices that a sentiment analysis model trained on product reviews performs well in testing but poorly on customer service transcripts. Which AI risk concept BEST explains this failure?
Select an answer to reveal the explanation.
Short Explanation
Here's the deal — you're seeing distribution shift, specifically domain shift, because product reviews and customer service transcripts don't have the same statistical characteristics. That mismatch causes the model to perform well in testing but poorly in the new deployment domain.
Full Explanation
The correct concept is distribution shift between training and deployment domains, specifically domain shift. It occurs when the training data (product reviews) and deployment data (customer service transcripts) have different statistical characteristics, causing performance degradation even when the model performs well during testing. The underfitting due to insufficient model complexity explanation is wrong because underfitting manifests as poor training performance, not as a failure that is specific to a new domain. The label poisoning in the product review dataset explanation is wrong because label poisoning is a deliberate attack, not a natural domain mismatch. The overfitting caused by excessive regularization explanation is wrong because regularization typically reduces overfitting, and excessive regularization causes underfitting rather than overfitting.