
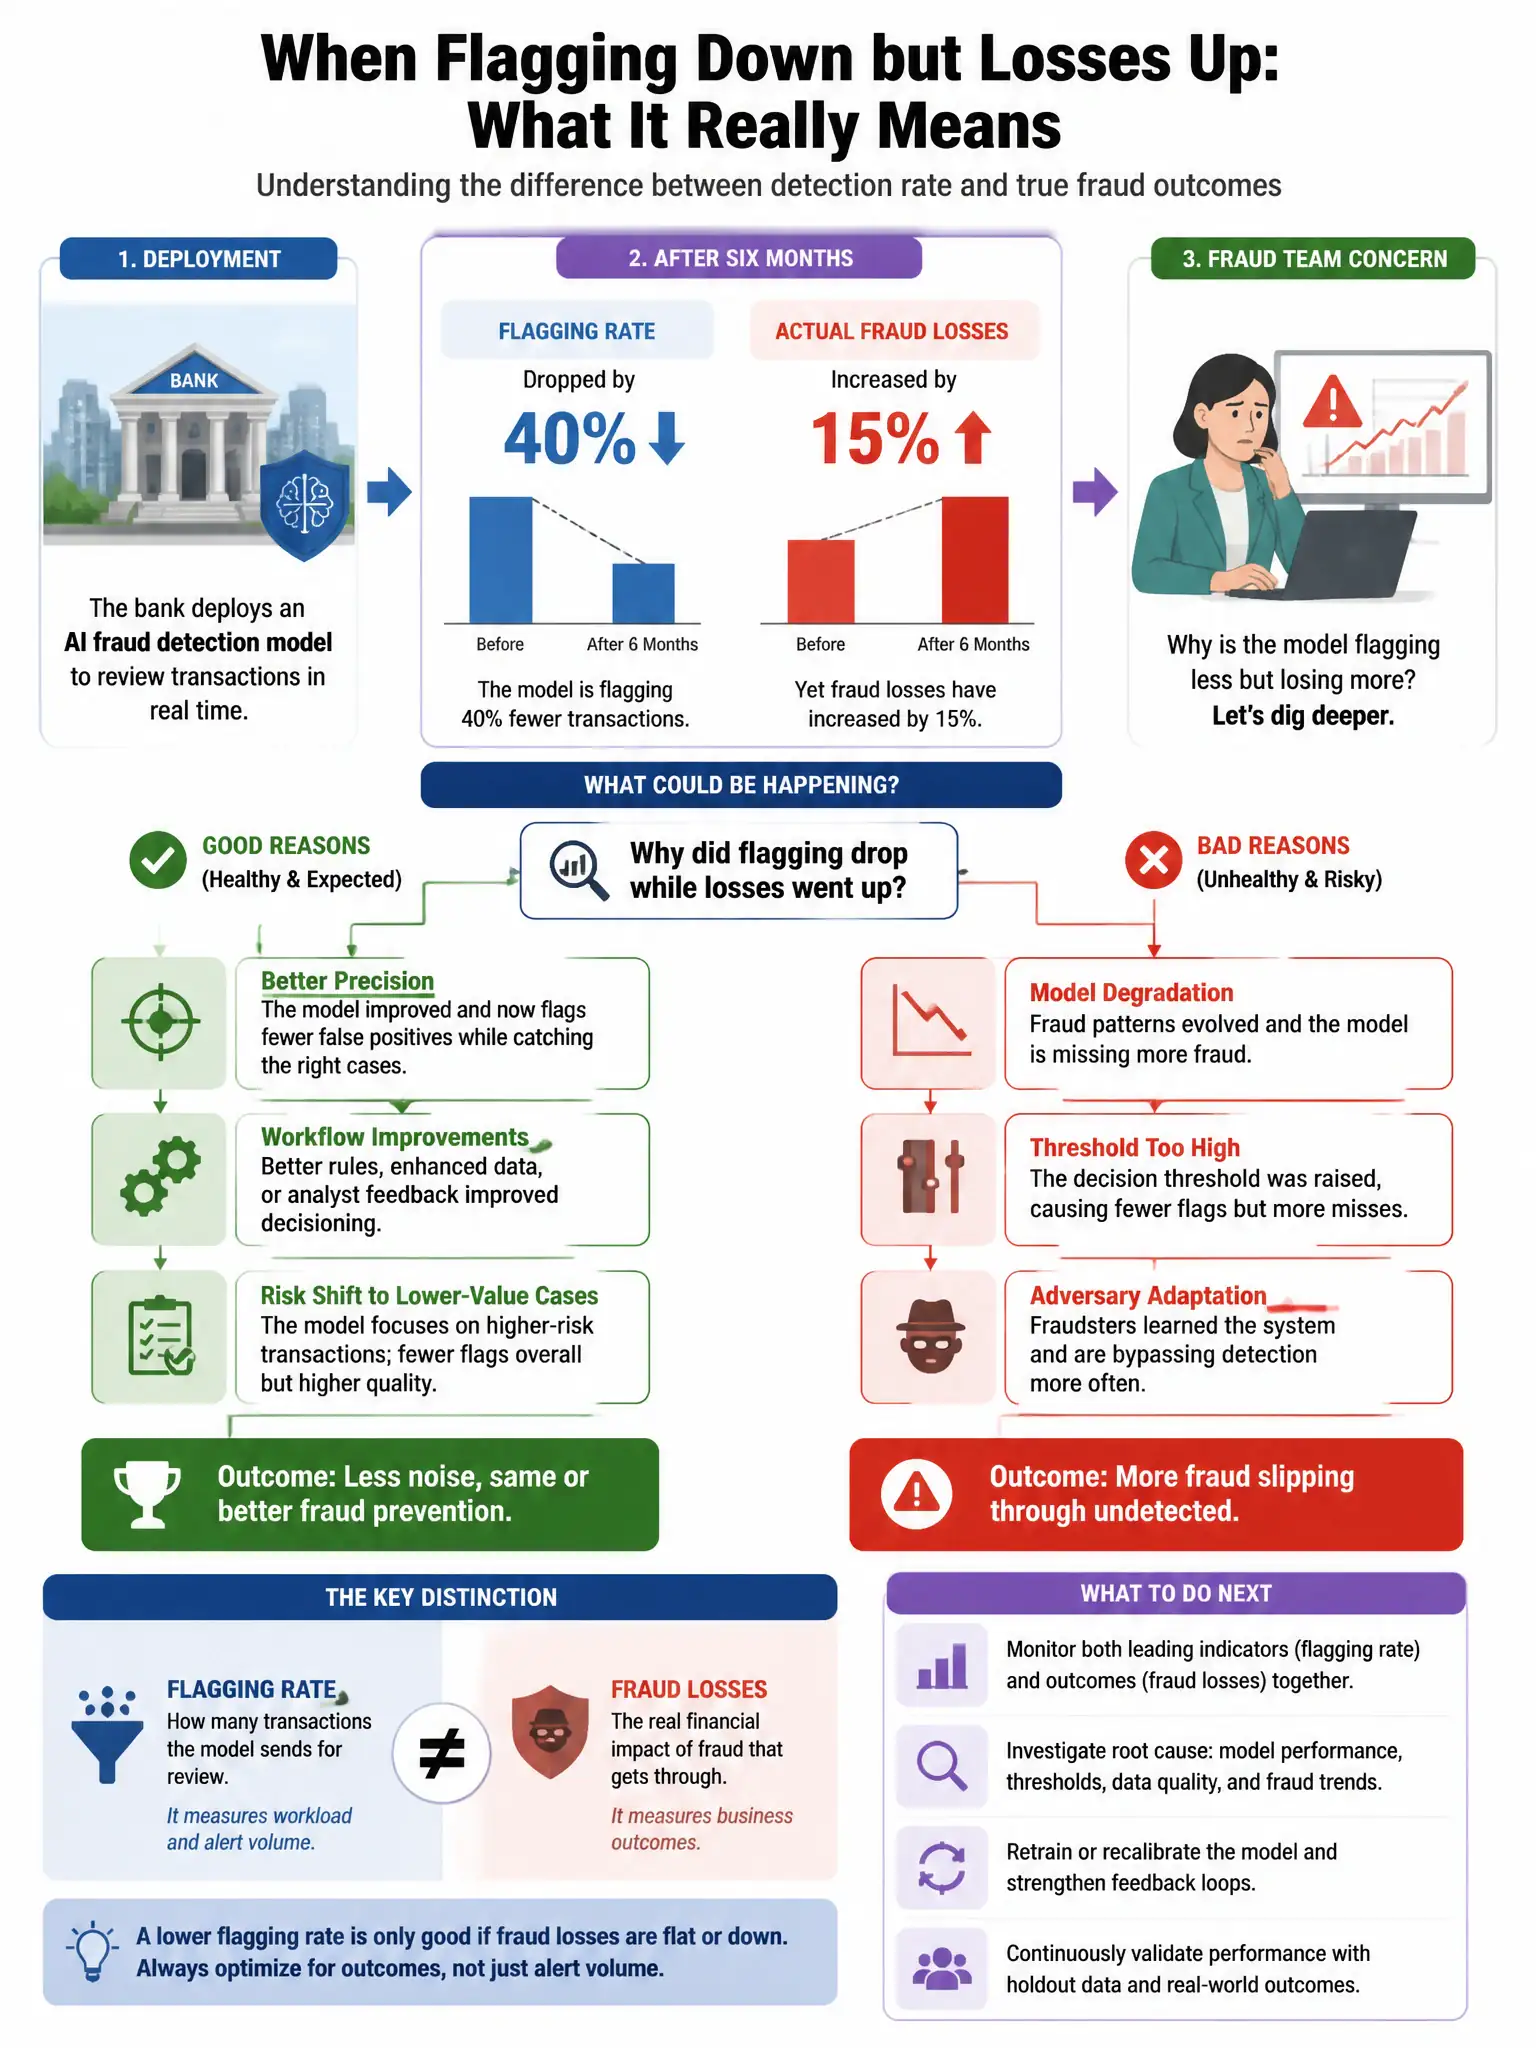
A bank deploys an AI fraud detection model. After six months, the fraud team notes that the model's flagging rate has dropped by 40% while actual fraud losses have increased by 15%. Model performance metrics (AUC, precision) appear stable on the monitoring dashboard. How should this apparent contradiction be explained and addressed?
Select an answer to reveal the explanation.
Short Explanation
Here's the deal — this pattern points to adversarial concept drift: fraudsters have studied the model's detection patterns and adapted to evade it. Your standard metrics can look stable if the labels still come from the same now-evaded detection process, so you need to test against real fraud behavior instead of trusting the dashboard.
Full Explanation
This pattern is consistent with adversarial concept drift: fraudsters may have studied the model's detection patterns and adapted to evade detection. Standard monitoring metrics, such as precision and area under the curve, may not detect this if evaluation labels still come from the same now-evaded detection process. That creates a blind spot where apparent performance looks stable while real-world effectiveness declines. The right response is active adversarial testing and re-evaluation against current fraud behavior. The view that dashboard metrics are correct and fraud losses are unrelated ignores business evidence. Lowering the threshold to raise flagging rates and recover prior detection does not address evasion and may mask it. Supplementing training data with more legitimate transactions to recalibrate the baseline also misses the issue: the problem is adversarial adaptation, not baseline miscalibration.