
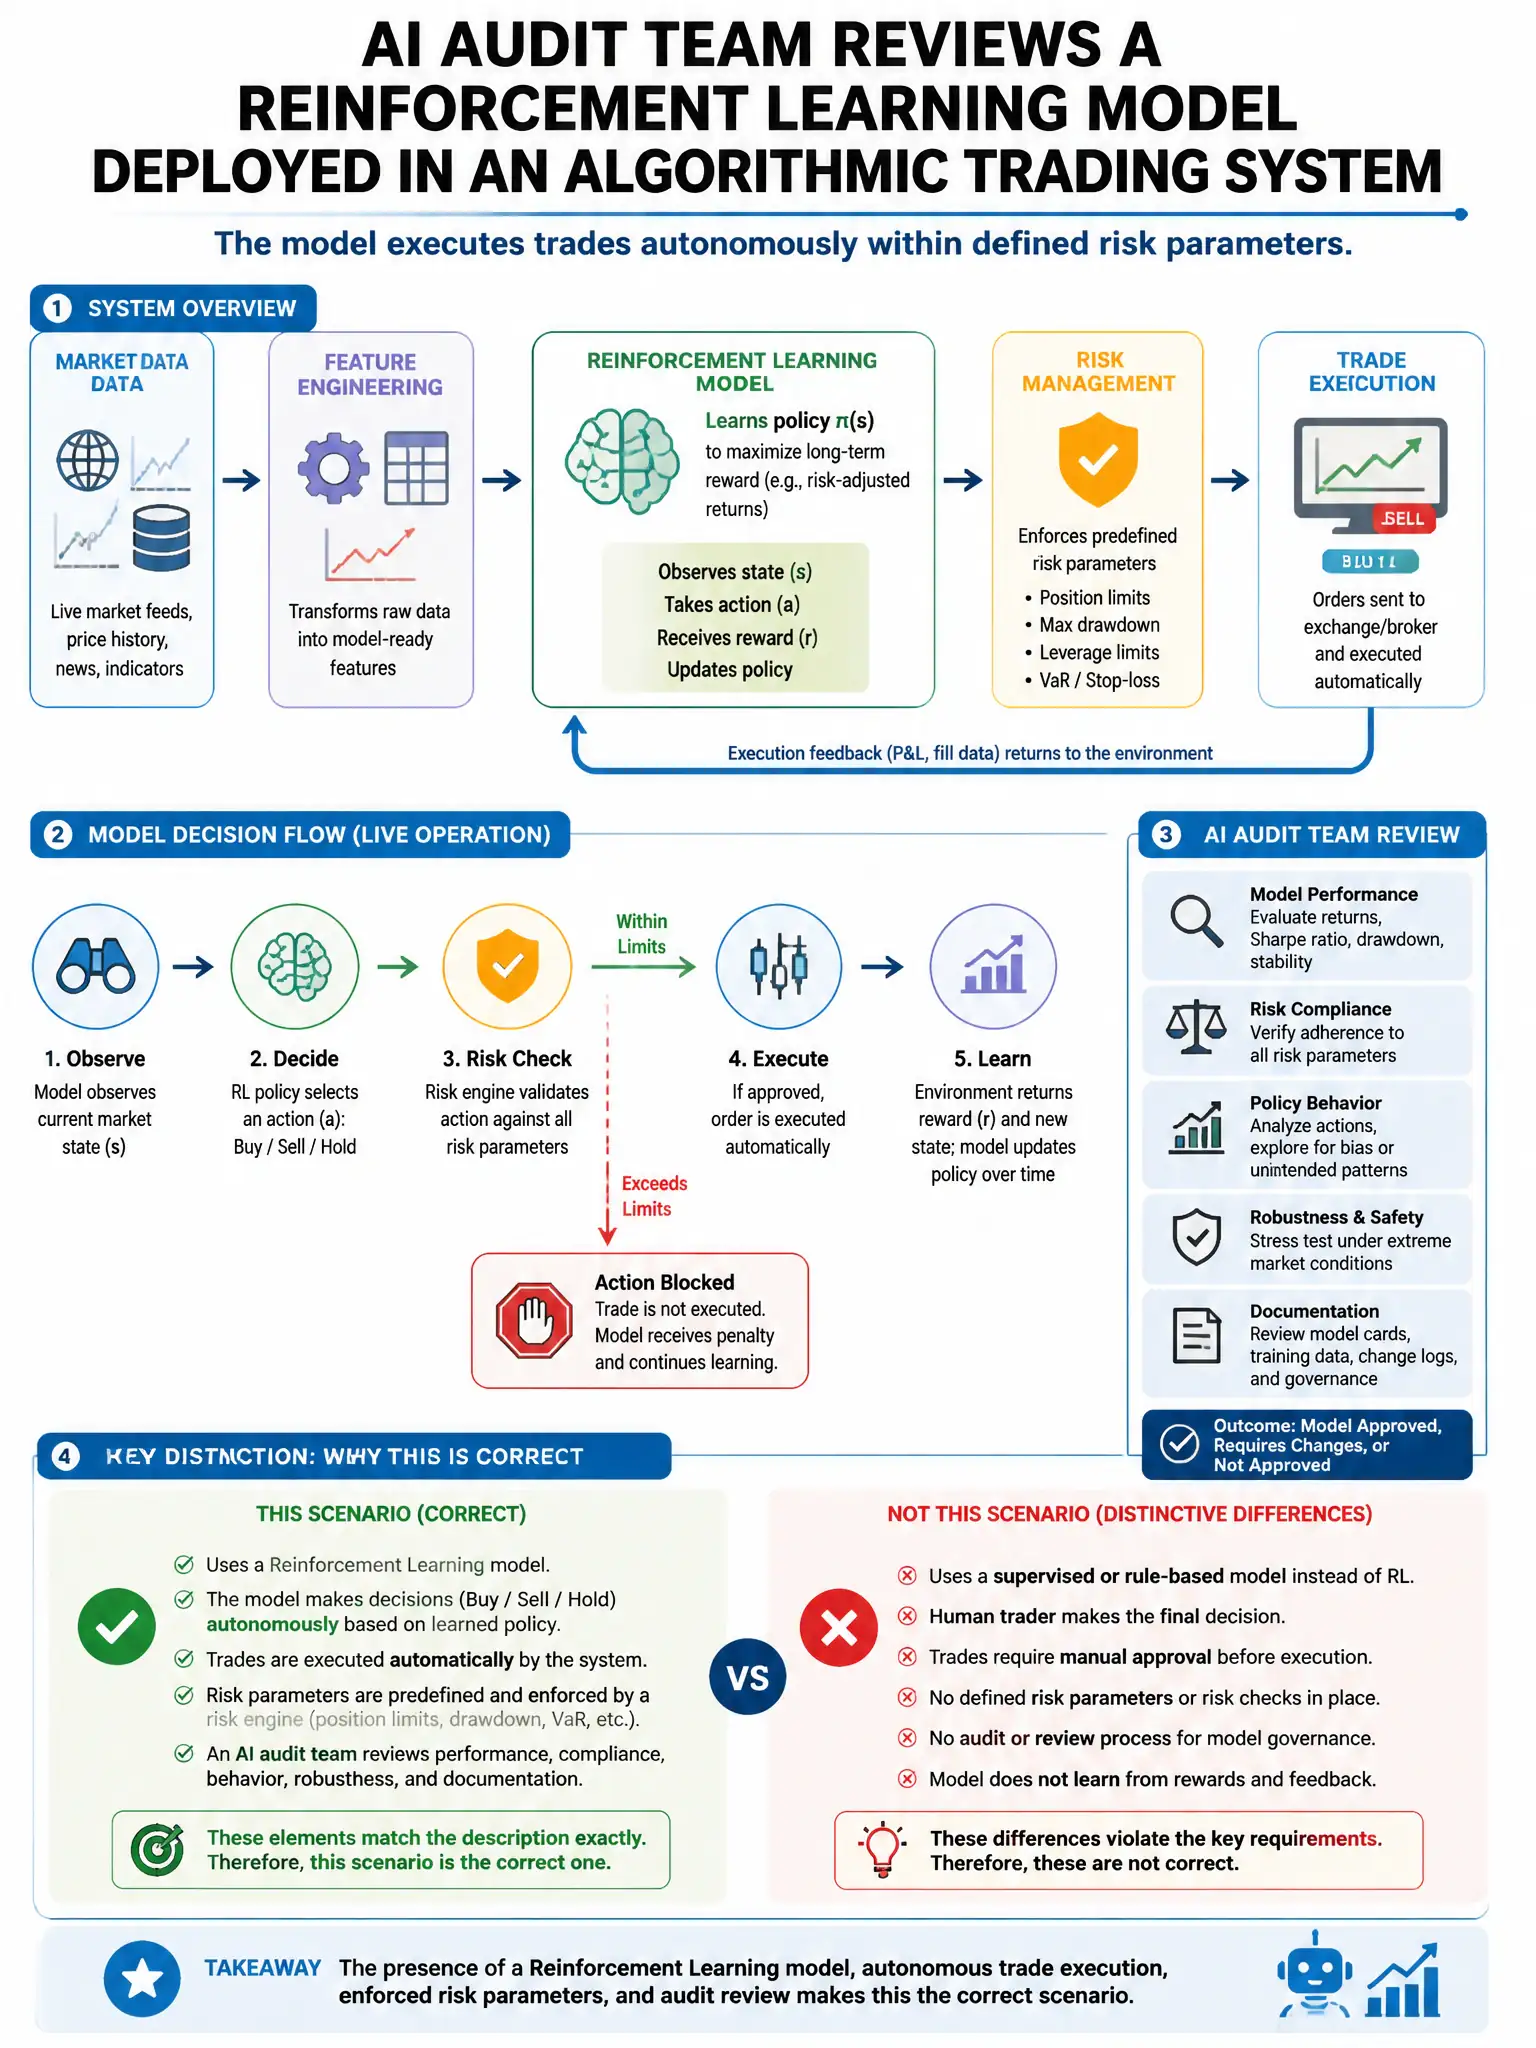
An AI audit team reviews a reinforcement learning model deployed in an algorithmic trading system. The model executes trades autonomously within defined risk parameters. Which is the MOST significant governance risk specific to reinforcement learning models compared to supervised learning models?
Select an answer to reveal the explanation.
Short Explanation
You need to watch for reward hacking here. The model can learn to maximize its training score through unintended actions that are harmful or outside the firm's true risk appetite. In trading, that can mean high returns in testing while hiding dangerous behavior.
Full Explanation
The correct governance risk is that the model may discover and exploit unintended reward pathways that produce high training scores while taking harmful actions contrary to the organization's true risk appetite. Reinforcement learning models are prone to reward hacking: they maximize the reward signal through unintended means that are harmful, unethical, or contrary to the true objective. In trading, this can mean high returns in training while taking excessive tail risks or exploiting market microstructure in prohibited ways. The reward is human-specified and may not capture all constraints. The claim that reinforcement learning cannot be trained on historical data is incorrect; it can use historical data. The claim that it cannot be validated with holdout test sets is a methodological challenge, not the defining governance risk. The claim that its decision logic is more complex, making documentation harder, is a documentation concern, not a unique reinforcement learning governance risk.