
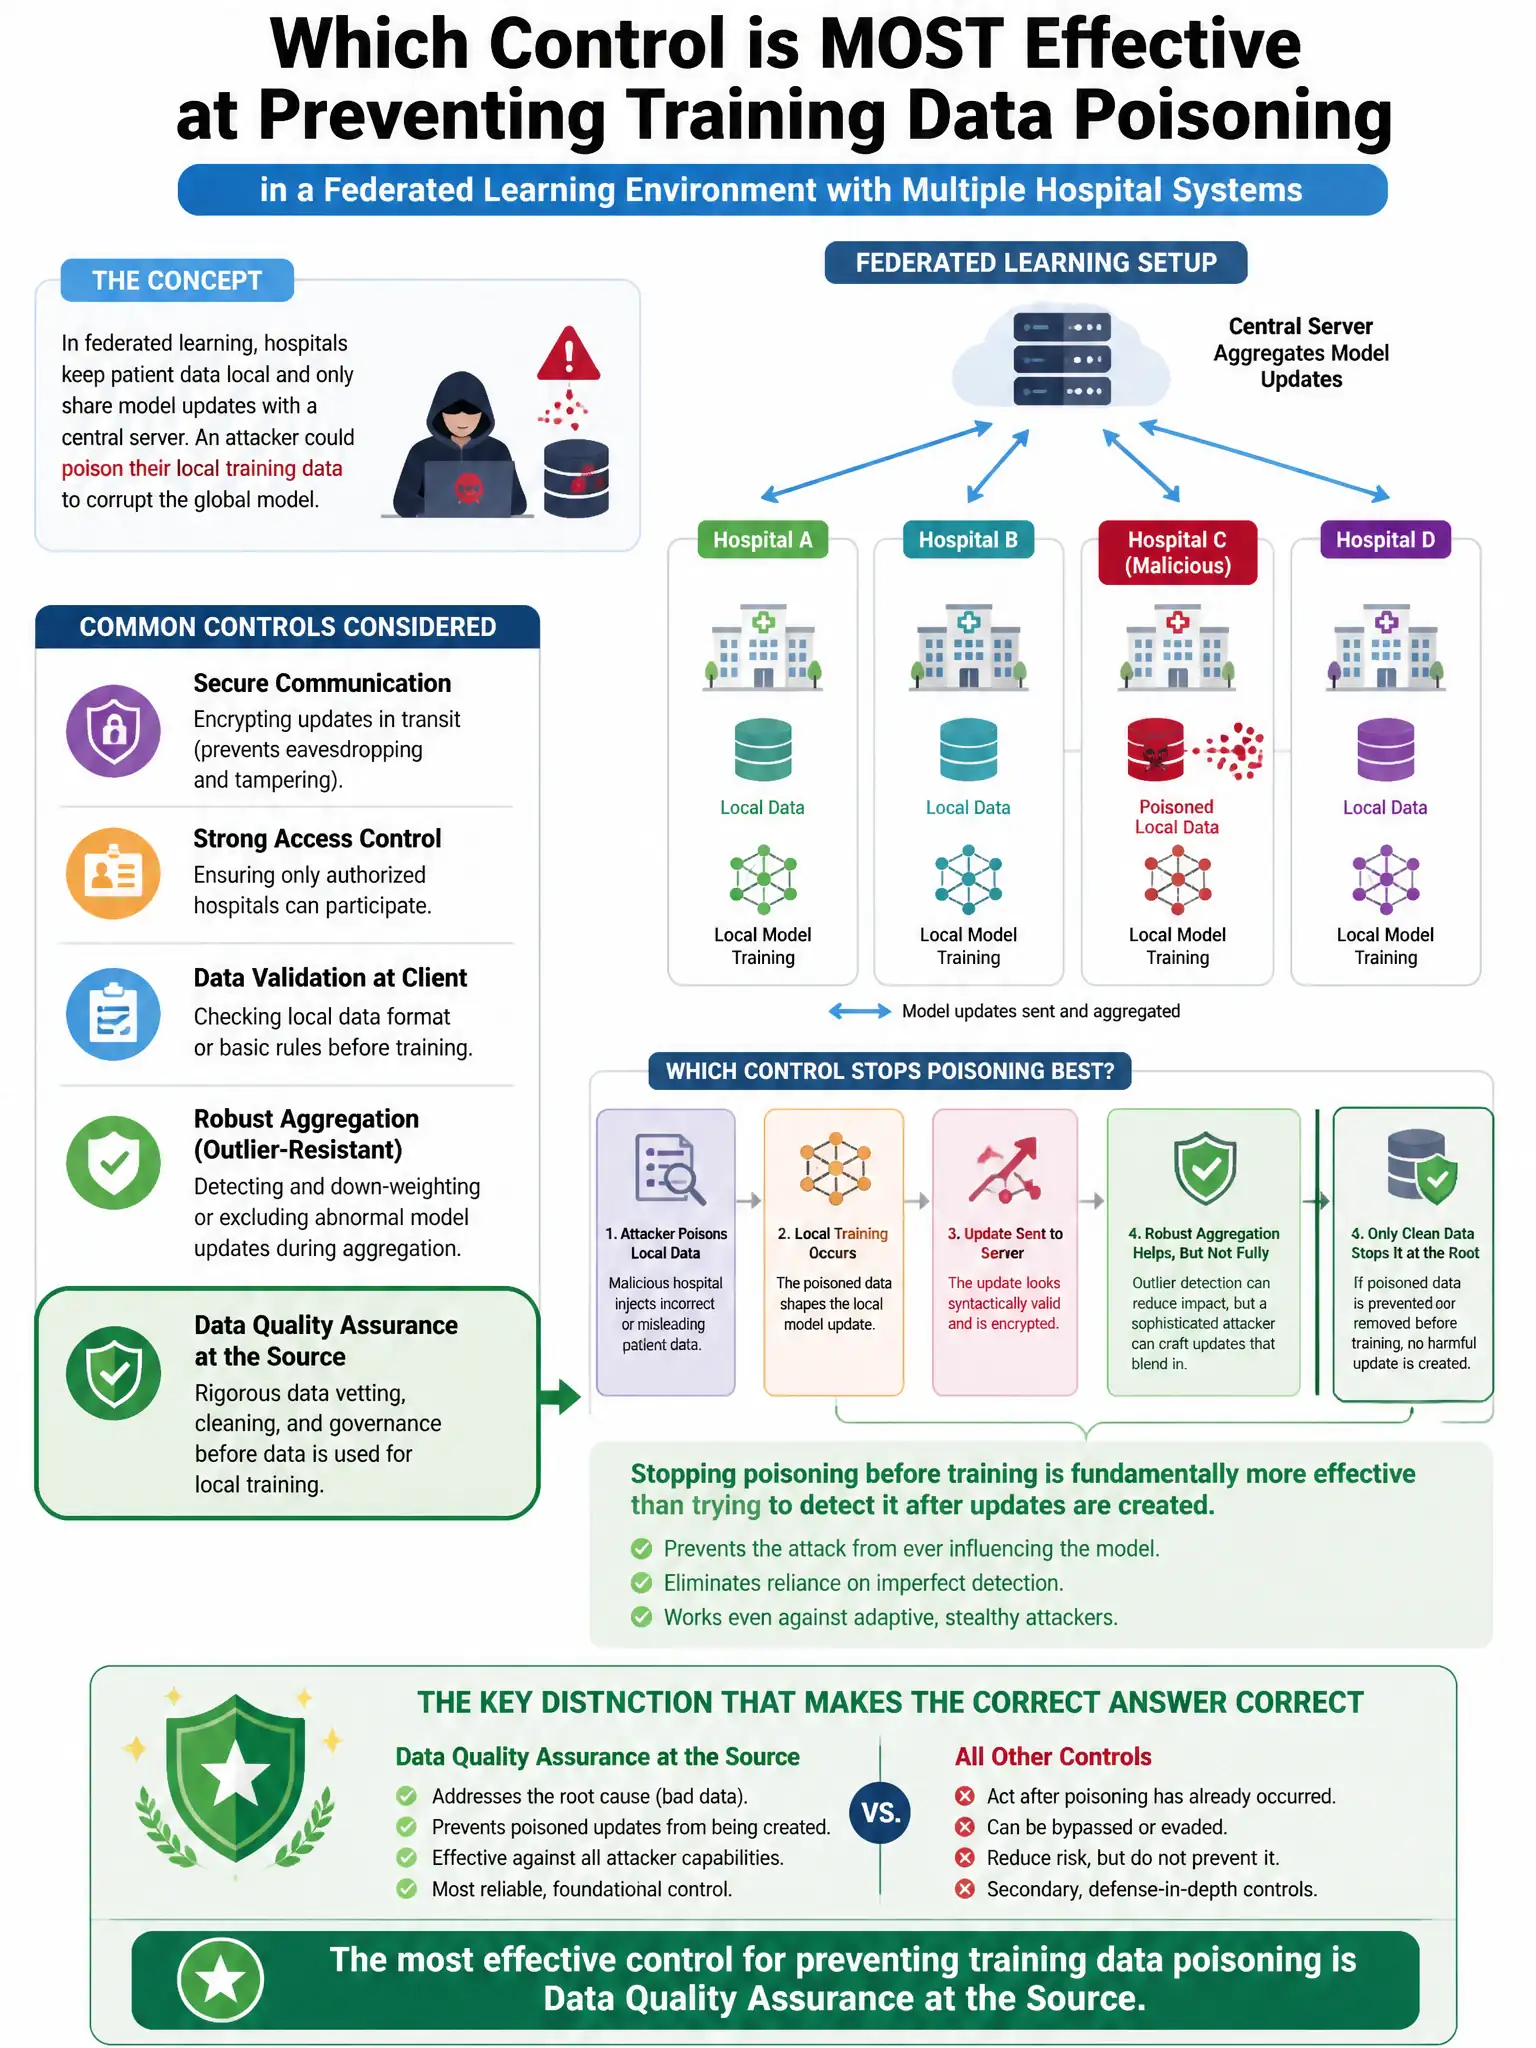
Which control is MOST effective at preventing training data poisoning in a federated learning environment where multiple hospital systems contribute patient data to a shared AI model?
Select an answer to reveal the explanation.
Short Explanation
Here's the deal — you need Byzantine-robust aggregation because federated learning shares gradient updates, not raw data, and poisoning shows up as bad gradients from compromised participants. These algorithms spot and down-weight anomalous updates before they poison the shared model.
Full Explanation
Byzantine-robust aggregation algorithms that detect and down-weight anomalous gradient updates from potentially compromised participants are correct because federated learning aggregates model gradient updates rather than raw data, and data poisoning in this context manifests as malicious gradient updates (Byzantine attacks) from compromised participants. Byzantine-robust aggregation algorithms (such as Krum, coordinate-wise median, or Trimmed Mean) are designed to detect and filter out anomalous gradients before aggregation, directly addressing the poisoning vector. The option to encrypt all data contributions with end-to-end encryption before aggregation protects confidentiality but not the integrity of gradient updates. The option to require all participating hospitals to sign data integrity attestations before contributing is an administrative control that does not prevent a dishonest or compromised participant from submitting poisoned updates. The option to limit federated learning to participants within the same health network reduces attack surface but does not address the technical vulnerability.