
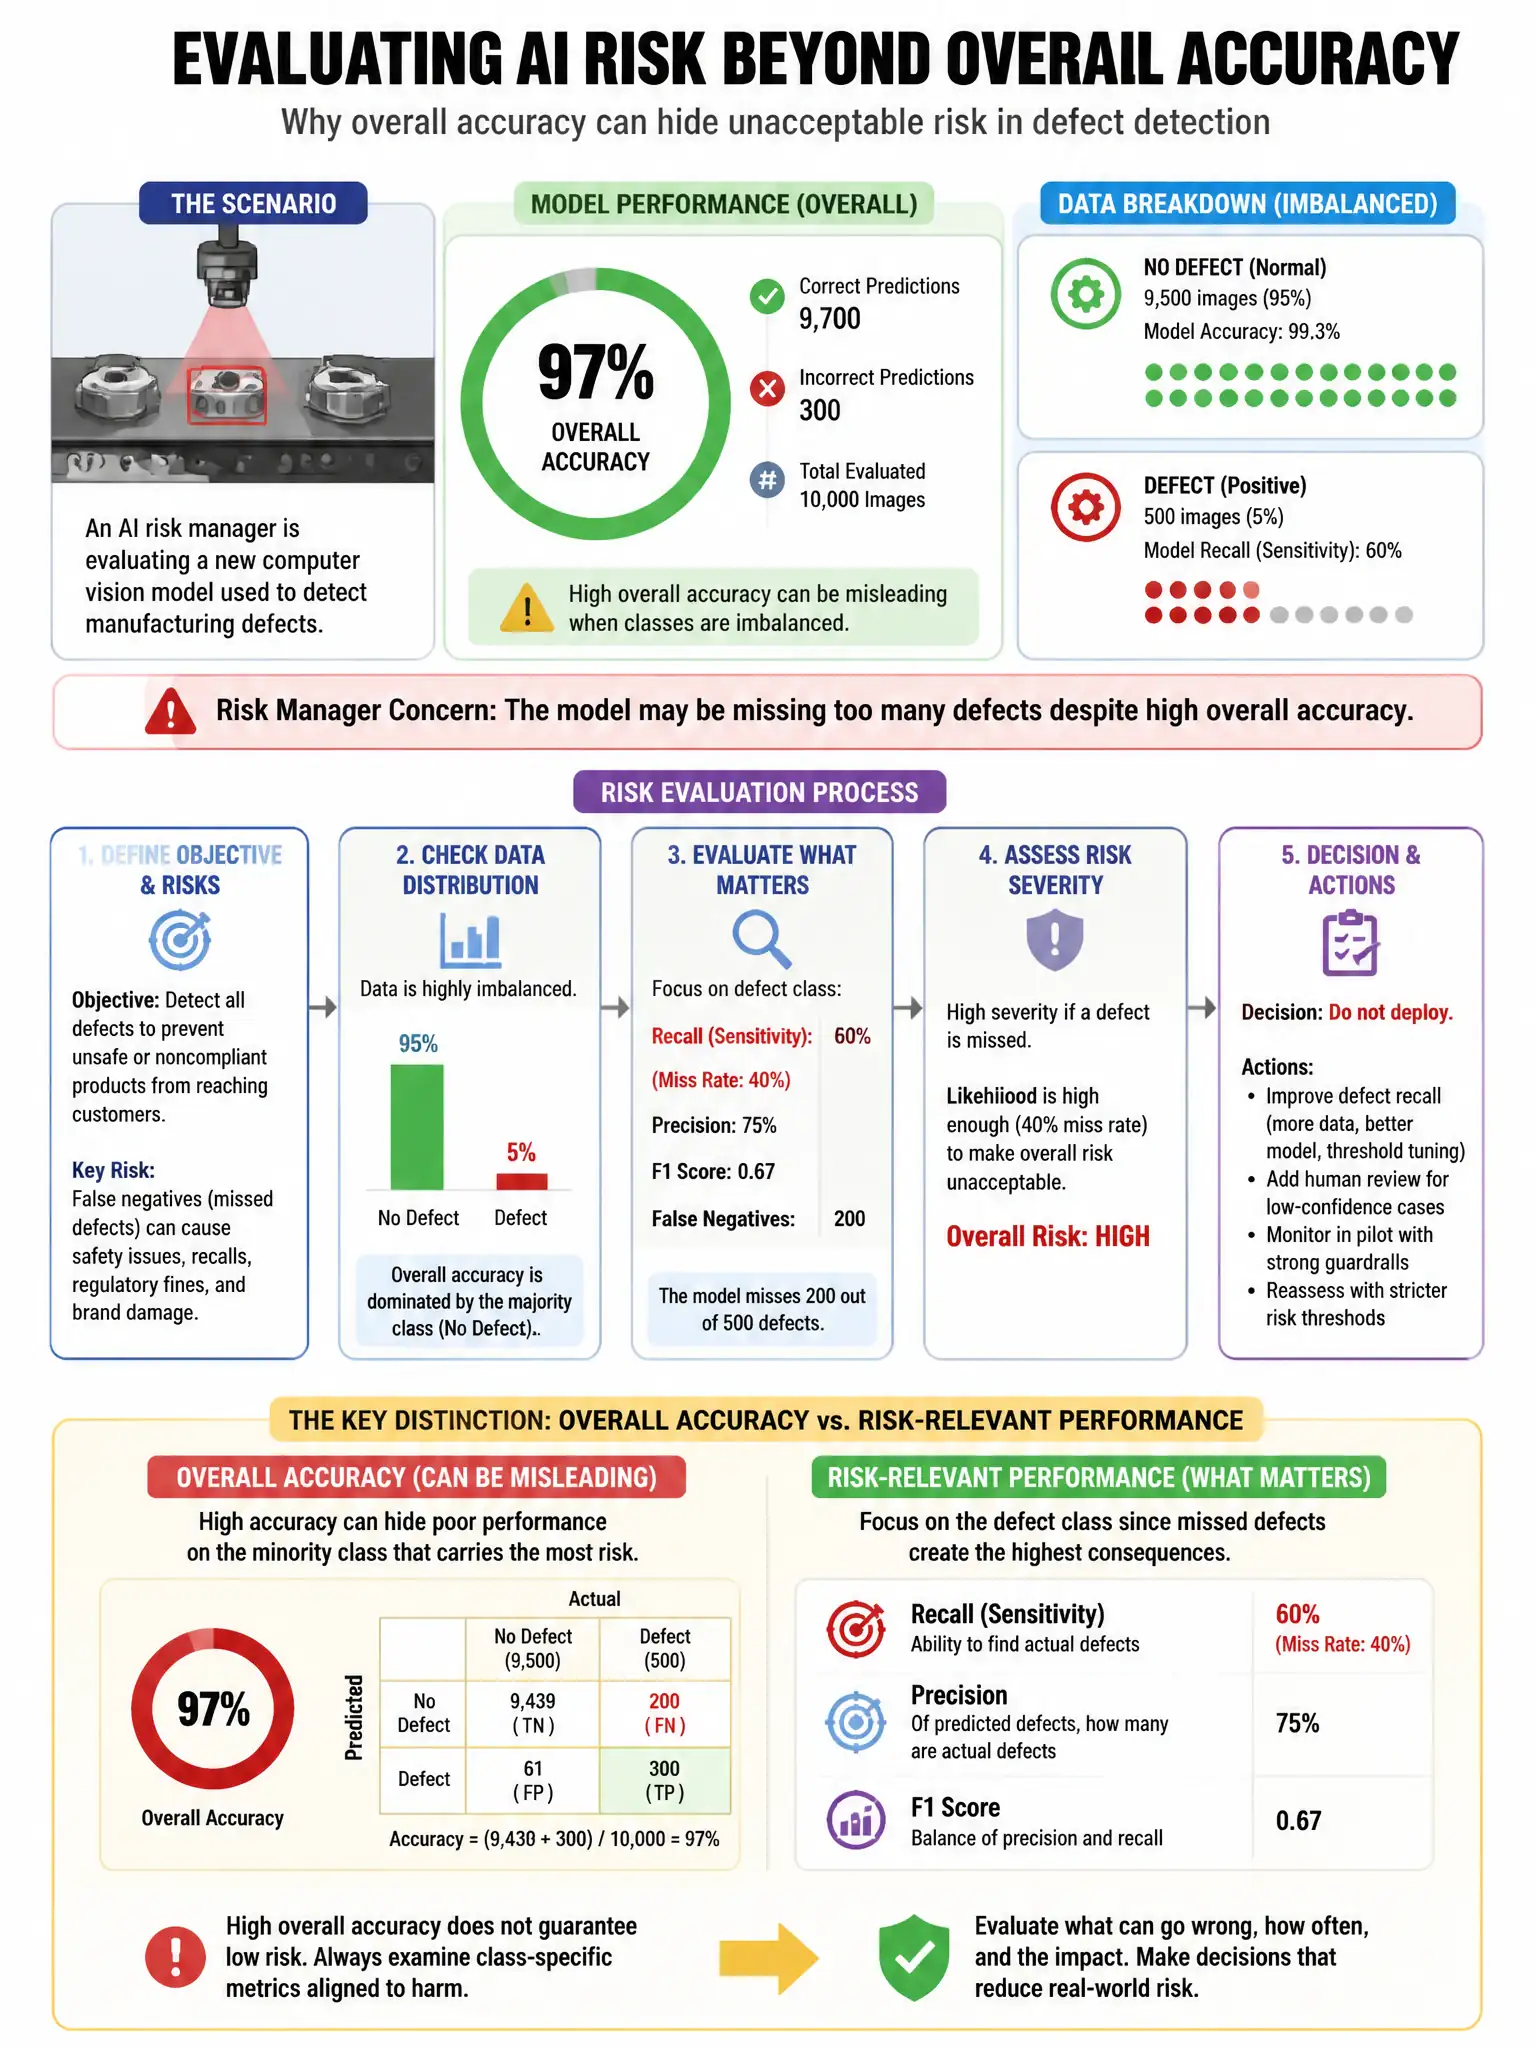
An AI risk manager is evaluating a new computer vision model used to detect manufacturing defects. The model achieves 97% overall accuracy, but the risk manager is concerned about performance on rare defect types. Which metric BEST captures risk related to rare defect classes?
Select an answer to reveal the explanation.
Short Explanation
Here's the deal — you want per-class recall because it shows how well the model catches each defect type, especially rare ones. High overall accuracy can hide poor performance on minority classes.
Full Explanation
Per-class recall (sensitivity) for each defect type is best because it directly measures the model's ability to correctly identify each defect type, including rare ones. High overall accuracy can mask poor performance on minority classes (accuracy paradox). Overall accuracy across all defect types can be inflated by common classes and hide rare-class misses. AUC-ROC computed on the full test set aggregates performance and can obscure rare-class failure. F1 score computed on the most common defect type only ignores rare defect risk entirely.