
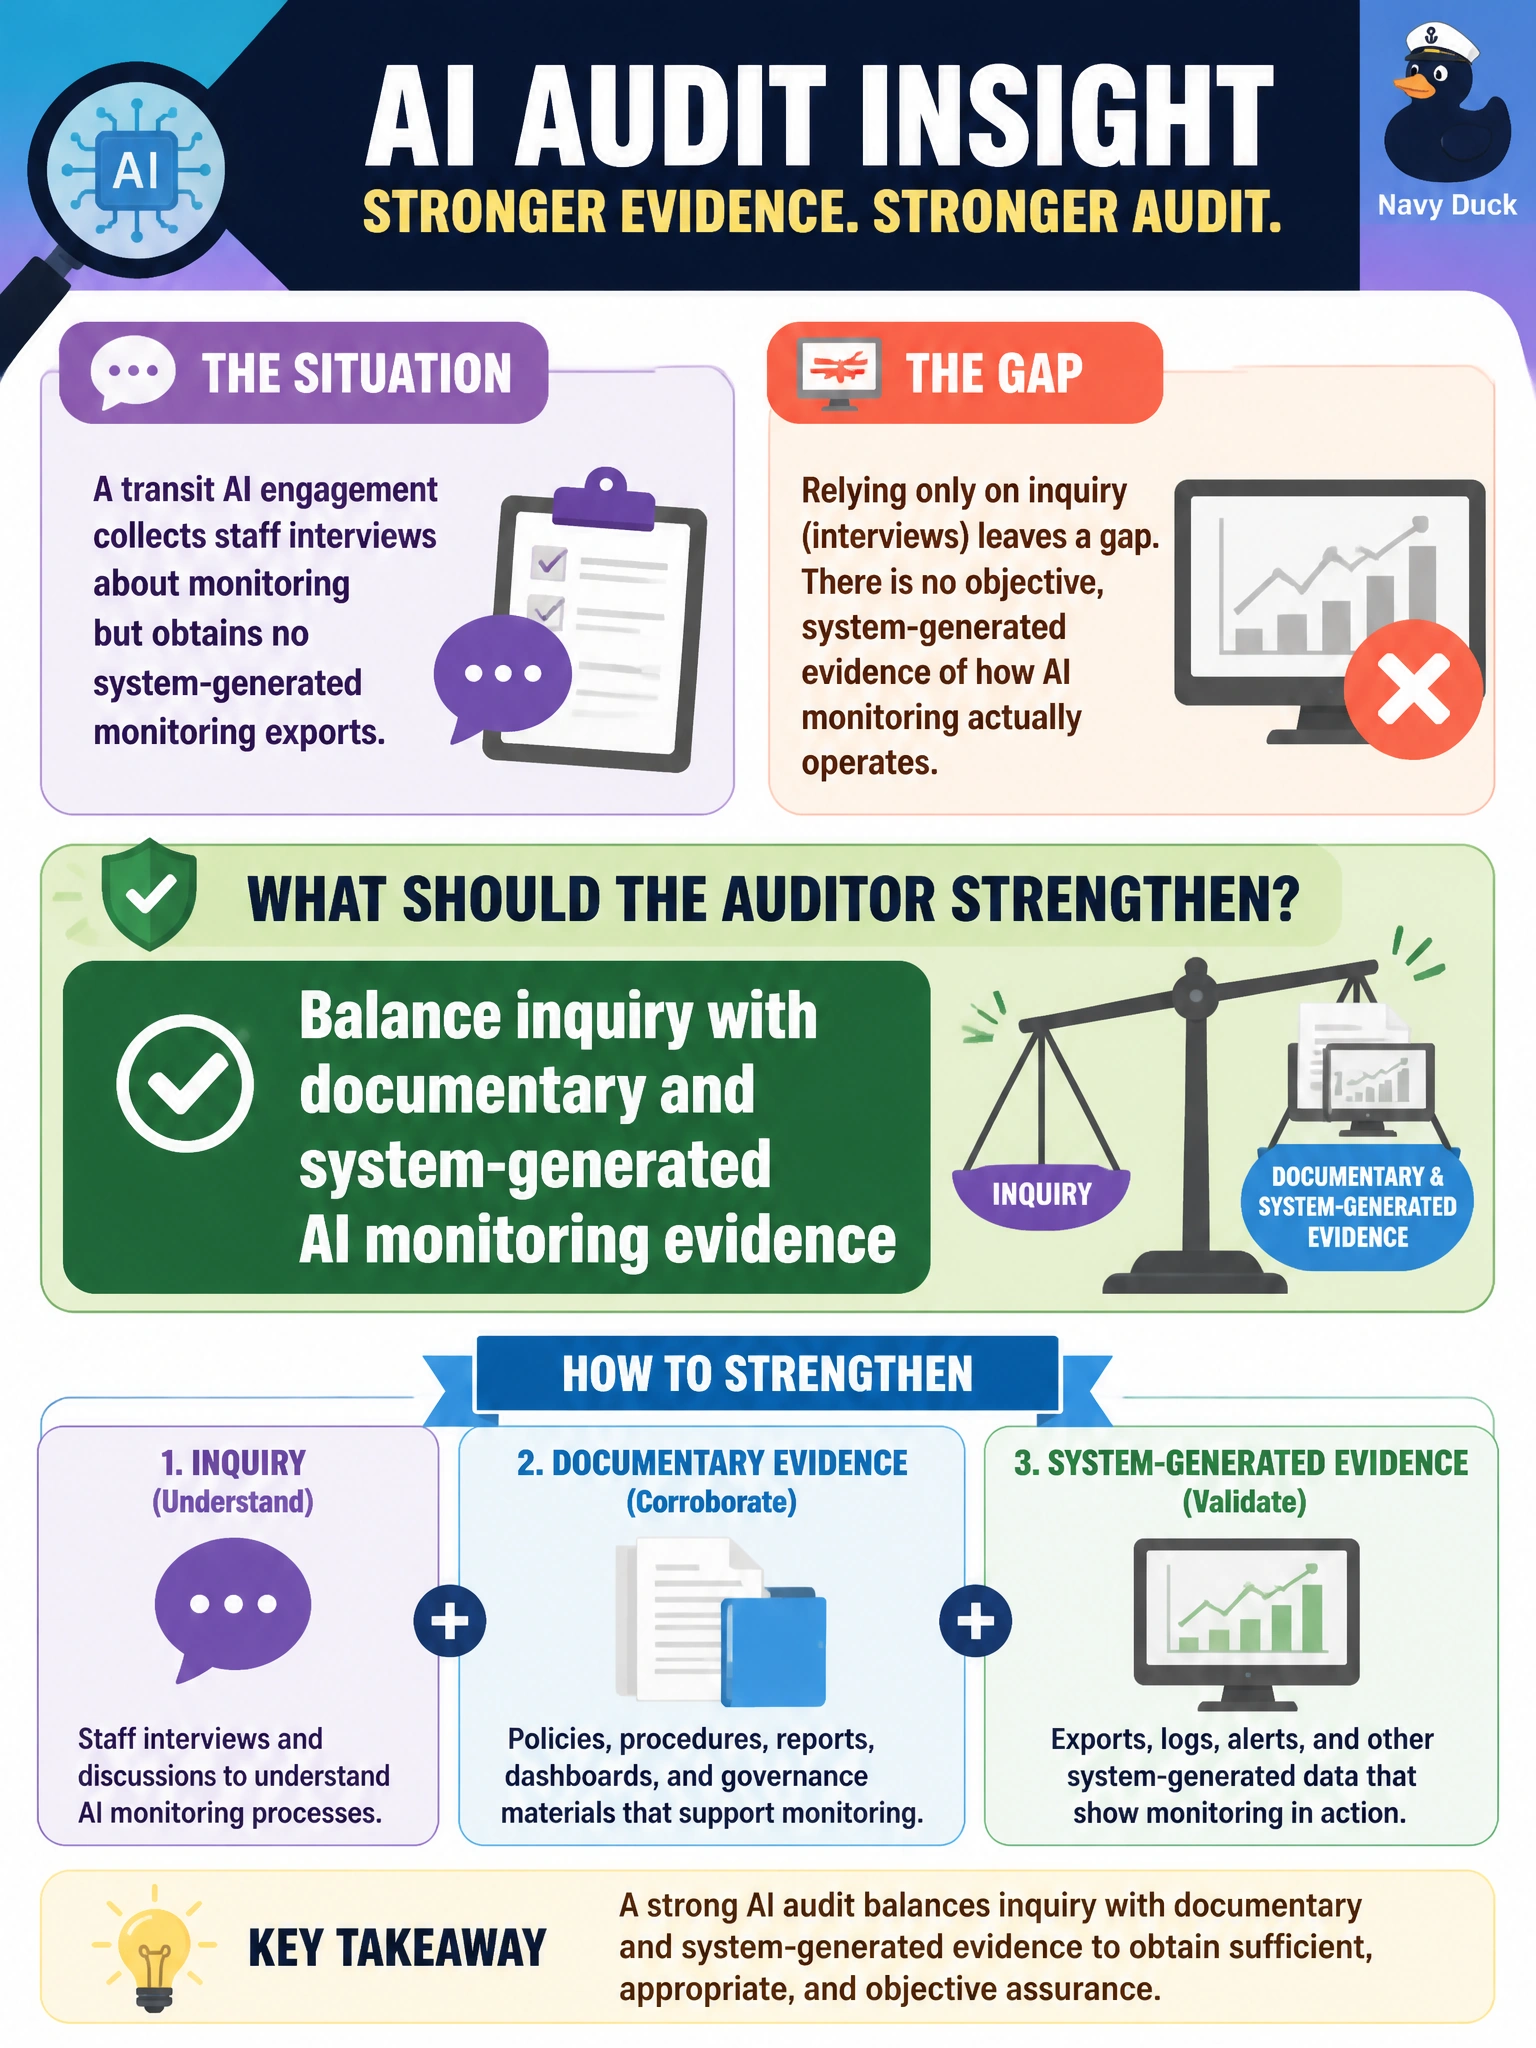
A transit AI engagement collects staff interviews about monitoring but obtains no system-generated monitoring exports. What should the auditor strengthen?
Select an answer to reveal the explanation.
Short Explanation
Extending interview sampling across shifts is fine, but it’s not the whole story — you need to pull the actual monitoring exports. Matching alert thresholds to vendor spec sheets still isn’t system proof — you need the actual monitoring exports. Deferring to 'future review' misses the AI control trail that is needed now.
Full Explanation
Strengthening the engagement means balancing inquiry with documentary and system-generated AI monitoring evidence. Staff interviews about transit monitoring explain intent and perceived practice, but they do not by themselves prove that alerts fired, dashboards were reviewed, or thresholds operated as designed. Obtaining monitoring exports, alert histories, and configuration evidence lets the auditor corroborate narratives and test whether civic transit AI oversight actually runs. Maintaining current alert thresholds while only tracking drift metrics for future review defers obtaining the system-generated monitoring evidence the engagement is missing right now; 'we will look at the data later' does not corroborate what staff already told the auditor about today's monitoring. Extending interview sampling across shifts to confirm monitoring consistency fails because more staff conversations still provide only inquiry, not system-generated proof that alerts fired, dashboards were reviewed, or thresholds operated as designed. Correlating alert threshold settings with vendor specification sheets for completeness fails because comparing configuration to vendor documentation does not produce the system-generated monitoring exports or alert histories needed to prove the controls actually ran in production. Exam caveat: exports must be authenticated to the production monitoring stack and the period under review; stale sandbox dumps can falsely confirm monitoring that operations never used. Operational check: map each monitoring claim from interviews to a system artifact (export, ticket, dashboard snapshot with metadata), reconcile differences, and retain both inquiry notes and documentary evidence in the transit AI workpapers.