
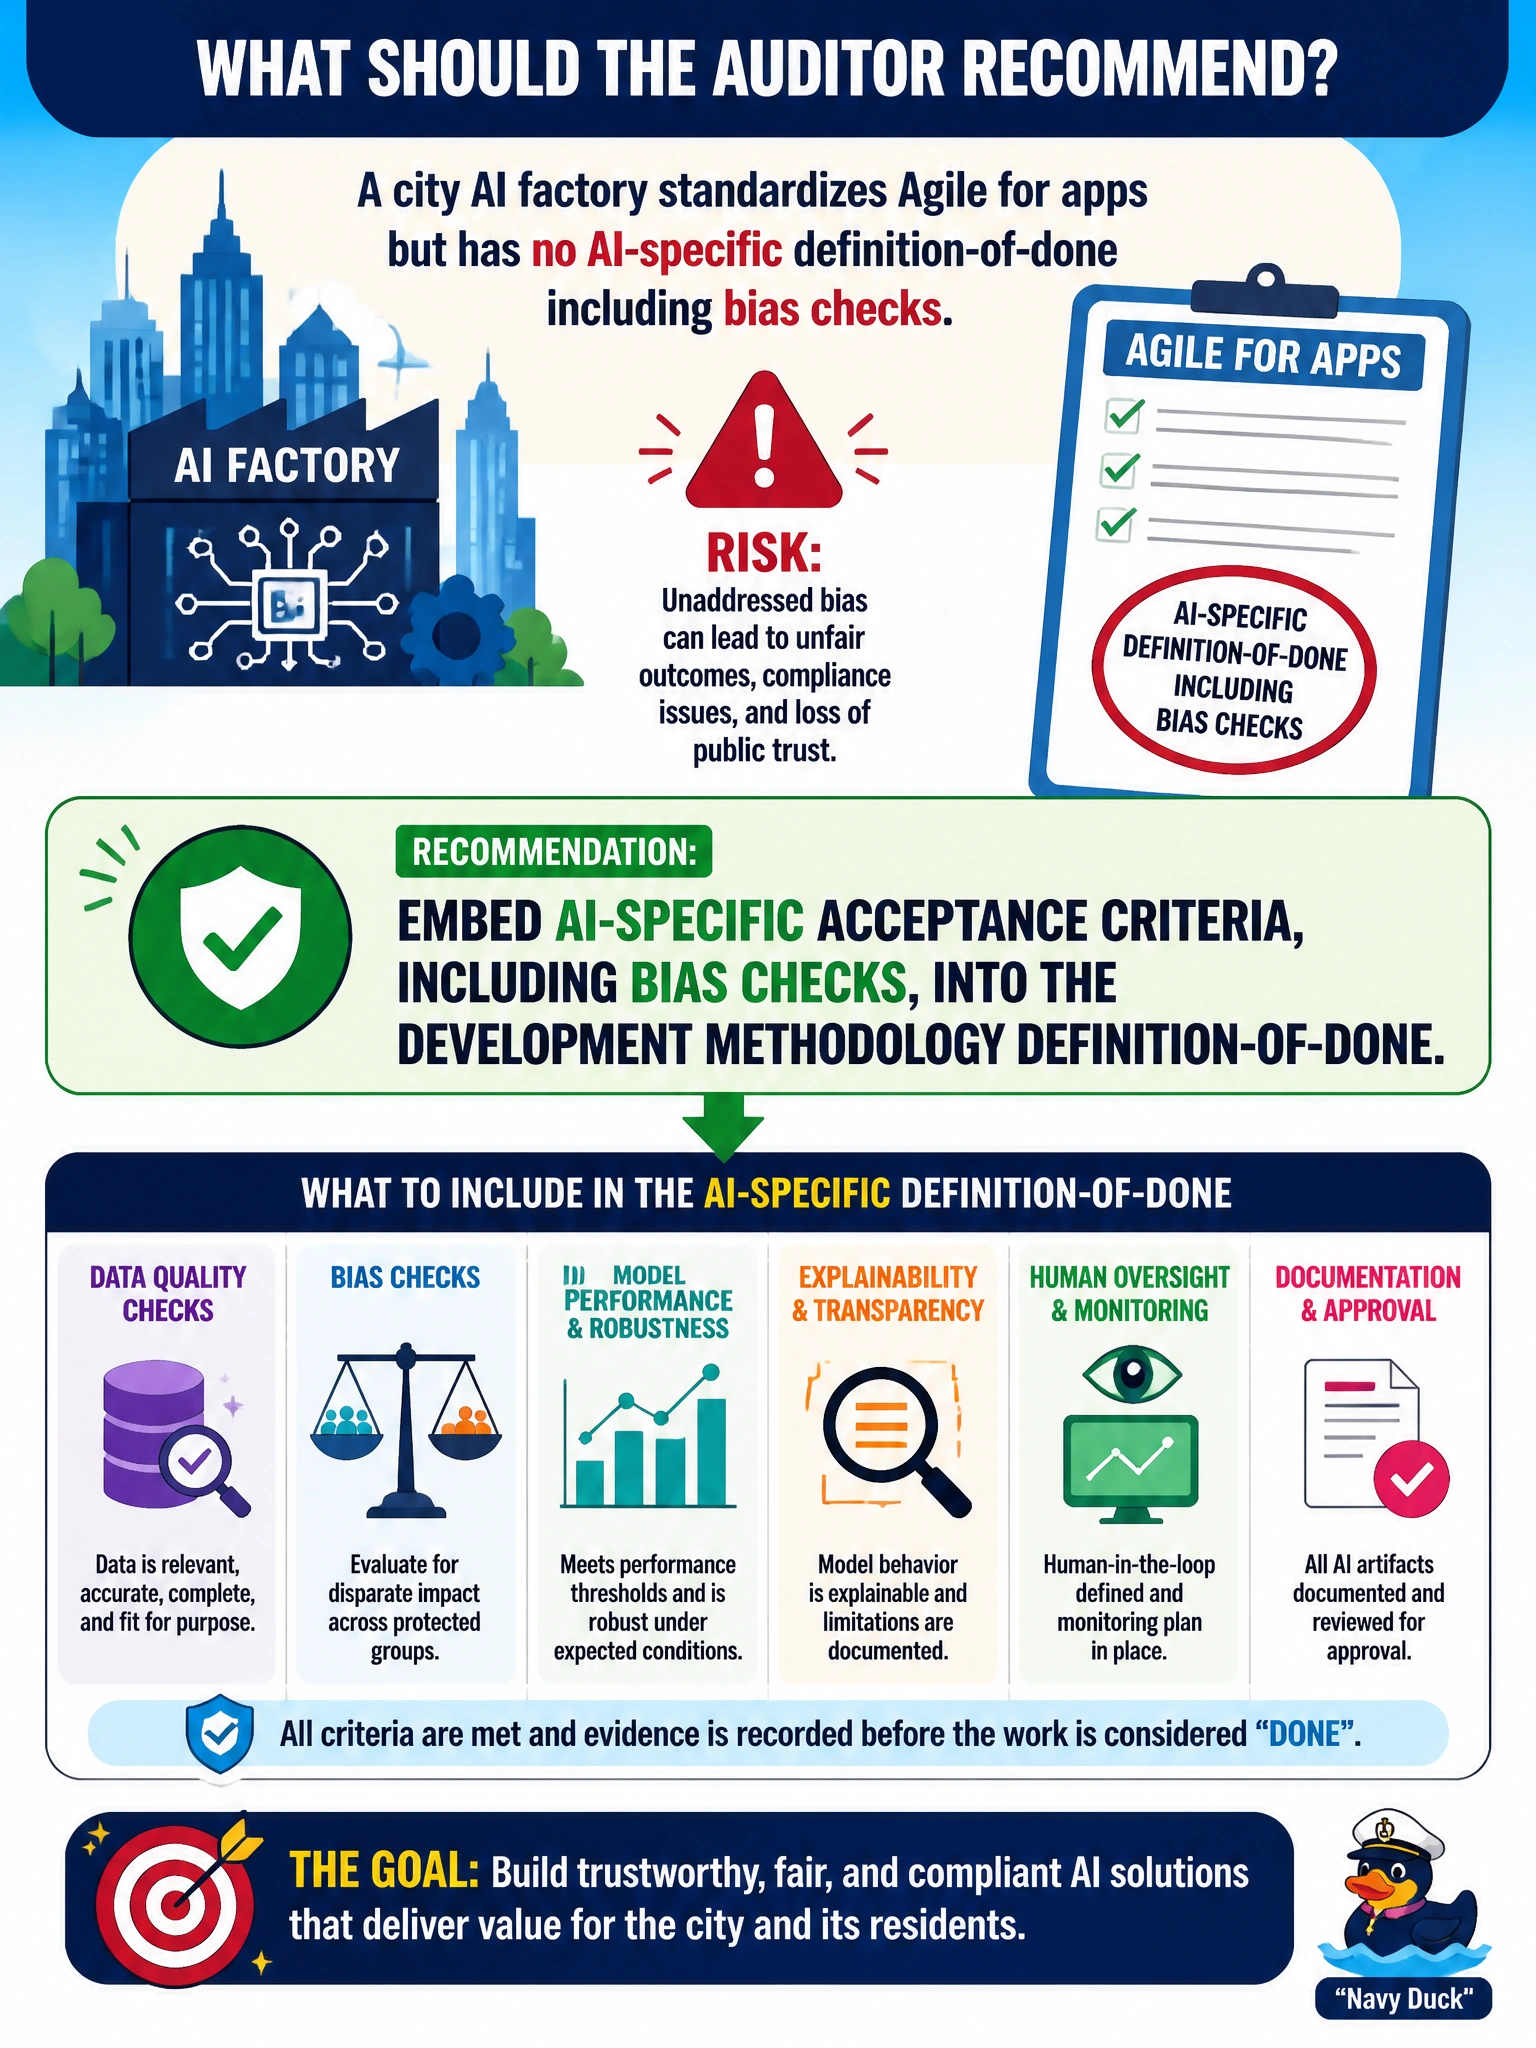
A city AI factory standardizes Agile for apps but has no AI-specific definition-of-done including bias checks. What should the auditor recommend?
Select an answer to reveal the explanation.
Short Explanation
Agile done for a payroll app is not done for an AI that touches residents unevenly. Put bias checks in the definition-of-done. If you push bias checks to retrospectives, backlog debt, or release gates, you’ll ship unfair models on Friday.
Full Explanation
Embedding AI-specific acceptance criteria, including bias checks, into the city AI factory definition-of-done works because generic application DoD (unit tests, code review, deployability) omits fairness, drift, data lineage, and model evaluation gates that resident-affecting AI requires. Stories that touch ranking, eligibility, or service allocation are not “done” when code compiles if disparate-impact tests were skipped. Making bias and related AI checks mandatory exit criteria prevents fairness from becoming optional polish after residents already feel the model. The correct recommendation upgrades methodology DoD for AI work items.
Recording bias evaluation outcomes in sprint retrospectives to guide future process improvement actions fails because retrospectives are process-improvement forums, not story exit criteria, so biased work can still close as done. Tracking identified bias metrics as backlog technical debt for prioritization during future sprint planning fails because it makes fairness deferrable instead of a mandatory done requirement, letting incomplete AI work ship. Capturing bias test summaries in model cards for review at the formal release approval gate following sprint completion fails because it evaluates fairness only after sprint work ends, rather than blocking story completion in the definition-of-done.
Exam caveat: checkbox bias tests with weak metrics can create false completion; DoD criteria should name concrete evaluation methods, datasets, and pass thresholds appropriate to the use case. Operational check: amend the AI factory DoD template to require documented bias/fairness evidence for relevant stories, block sprint closure in tooling when those checks are missing, and sample completed AI stories for DoD adherence each release.